diff --git a/README.md b/README.md
index bcd9ed9..a6f24b7 100644
--- a/README.md
+++ b/README.md
@@ -20,62 +20,139 @@
---
+
+
+**When the work happens** · [Growth, year by year](#user-content-growth) · [Hour of day](#user-content-rhythm) · [Weekday × hour](#user-content-punchcard) · [Weekday vs weekend](#user-content-surplus) · [Per repository](#user-content-ground) · [Cumulative](#user-content-accrual) · [Repository lifecycles](#user-content-lifecycles) · [Releases in time](#user-content-cadence) · [Unbroken days](#user-content-streak)
+
+
+
+
+Growth, year by year Eleven years, square-root scale. **9,313 in 2026** — after two years that are genuinely zero and one year that is genuinely down.
**2016** — one commit. **2017–2018** — nothing; the gap in the chart is real, and it is two years long. **2019** — 13. **2020** — 129, the year of coming back. **2021** — 198. **2022** — 676. **2023** — 589, lower than the year before, and the chart does not smooth it. **2024** — 1,181; the first upstream patch merged into [Dify](https://github.com/langgenius/dify/pull/5631) that July. **2025** — 3,193; `negentropy-perceives` in August, `agentic-ai-cognizes` in October. **2026-01-31** — the trunk starts. **2026-05-18** — both of those repositories are archived into it. **2026** — 9,313 so far.
+
+
+
+Hour of day The surplus, located: **22:00**, 2.54× a flat baseline — 4,349 open-source commits, Asia/Shanghai. Dawn is empty, not missing.
+
+
+
+Weekday × hour The two-dimensional answer: densest cell **Sun 22:00**, 83 commits; 37 of 168 cells are true zeros; weekends hold 34.7% against a 28.6% flat share.
+
+
+
+Weekday vs weekend Weekday vs weekend, normalised to per-day rates (**572 weekdays ÷ 230 weekend days**): same shape, and the weekend actually runs hotter per day — peak at 22:00. "By day" is a job description, not a schedule.
+
+
+
+Per repository [negentropy](https://github.com/ThreeFish-AI/negentropy) knowledge engine · [coding-proxy](https://github.com/ThreeFish-AI/coding-proxy) failover for coding agents · [hyper-git](https://github.com/ThreeFish-AI/hyper-git) changelists for VS Code · [agents.md](https://github.com/ThreeFish-AI/agents.md) the doctrine they are written under
+
+
+
+Cumulative Cumulative, monthly: two curves flatten on the day they graduated into the trunk, which keeps climbing. Window 2024-06-22 → 2026-09-01 — **26 months, not the eleven years above.**
+
+
+
+Repository lifecycles Repositories as intervals, creation to last push; the two same-day endings are the graduation. Deleted repos are invisible at this caliber.
+
+
+
+Releases in time Releases have timing, not just counts — latest: **give-me-a-break v0.1.6**. negentropy ships as merged PRs, not tags.
+
+
+
+Unbroken days The run the rug brackets: **88 days, 2026-03-19 → 2026-06-14**, the longest inside its latest-400-day window; the all-time longest is 88 days (2026-03-19 → 2026-06-14). Of the 802 days in the whole window, 249 carried a commit (31%) — authored commits in source repos, a narrower population than the GitHub calendar above.
+
+
---
+
+
+**How it ships** · [How long a PR waits](#user-content-latency) · [Commit grammar](#user-content-grammar) · [Language shares](#user-content-tongues) · [Upstream pull requests](#user-content-upstream)
+
+
+
+
+How long a PR waits What the median hides: p90 **2.8 h**, longest **11.9 d**; of 1118 closed, 40 were never merged and are excluded. Solo self-merge: this measures change-unit size, not review speed.
+
+
+
+Commit grammar Seventy-seven of a hundred, made countable: **fix 19.0%** leads; **996 subjects (22.9%) don't parse** — drawn as open cells, not hidden.
+
+
+
+Language shares Both conditions, not a silent pick: GitHub's endpoint says **HTML 67.8%**; excluding the one generated-site repo, **Python 69.1%**. Bytes measure source size, not effort or authorship.
+
+
+
+Upstream pull requests N = 6, named: 2024-06-26 → 2025-12-06, 5 merged, one closed unmerged — a fraction of a percent of all public PRs.
+
+
---
### Built against five ways things fall apart
diff --git a/docs/i18n/zh-CN/README.md b/docs/i18n/zh-CN/README.md
index 44c4772..e398b21 100644
--- a/docs/i18n/zh-CN/README.md
+++ b/docs/i18n/zh-CN/README.md
@@ -20,62 +20,139 @@
---
+
+
+**工作发生在何时** · [增长,逐年](#user-content-growth) · [一日节律](#user-content-rhythm) · [星期 × 小时](#user-content-punchcard) · [工作日与周末](#user-content-surplus) · [按仓库计](#user-content-ground) · [累计曲线](#user-content-accrual) · [仓库生灭](#user-content-lifecycles) · [发布节奏](#user-content-cadence) · [连续天数](#user-content-streak)
+
+
+
+
+增长,逐年 十一年,平方根标度。**9,313(2026)**——此前是两个真正的零,和一次真正的回落。
**2016** —— 一条提交。**2017–2018** —— 空的;图上那个缺口是真的,而且长达两年。**2019** —— 13 条。**2020** —— 129 条,回来的那一年。**2021** —— 198 条。**2022** —— 676 条。**2023** —— 589 条,低于上一年,图没有把它抹平。**2024** —— 1,181 条;当年 7 月,第一个上游补丁合入 [Dify](https://github.com/langgenius/dify/pull/5631)。**2025** —— 3,193 条;8 月有了 `negentropy-perceives`,10 月有了 `agentic-ai-cognizes`。**2026-01-31** —— 主干开始。**2026-05-18** —— 那两个仓库归档并入主干。**2026** —— 目前 9,313 条。
+
+
+
+一日节律 余暇的落点:**22:00**,平坦基线的 2.54×——4,349 条开源提交,Asia/Shanghai。黎明是空的,不是缺数据。
+
+
+
+星期 × 小时 二维答案:最密格 **Sun 22:00**(周日 22:00),83 条提交;168 格中 37 格为真实零值;周末占 34.7%(平坦份额 28.6%)。
+
+
+
+工作日与周末 工作日对周末,按日均归一(**572 个工作日 ÷ 230 个周末日**):形状相同,且周末的日均反而更热——峰值落在 22:00。「白天」是职业描述,不是作息表。
+
+
+
+按仓库计 [negentropy](https://github.com/ThreeFish-AI/negentropy) 知识引擎 · [coding-proxy](https://github.com/ThreeFish-AI/coding-proxy) 编码 Agent 故障转移 · [hyper-git](https://github.com/ThreeFish-AI/hyper-git) VS Code 变更列表 · [agents.md](https://github.com/ThreeFish-AI/agents.md) 它们共同遵循的规约
+
+
+
+累计曲线 月度累计:两条曲线在毕业并入主干的那一天走平,而主干继续爬升。窗口 2024-06-22 → 2026-09-01——**26 个月,不是上方那张十一年图。**
+
+
+
+仓库生灭 仓库即区间,自创建至最后推送;两根同日终止的条就是那次毕业。已删除的仓库在此口径下不可见。
+
+
+
+发布节奏 Release 有时机,不止有计数——最新一个:**give-me-a-break v0.1.6**。negentropy 以已合并 PR 交付,不以 tag。
+
+
+
+连续天数 rug 图括号标注的区间:**88 天,2026-03-19 → 2026-06-14**,是它那最近 400 天窗口内最长的一段;历史最长为 88 天(2026-03-19 → 2026-06-14)。整个窗口 802 天中 249 天有提交(31%)——口径为源仓库内我署名的提交,窄于上方的 GitHub 贡献日历。
+
+
---
+
+
+**如何交付** · [一个 PR 等多久](#user-content-latency) · [提交语法](#user-content-grammar) · [语言占比](#user-content-tongues) · [上游 PR](#user-content-upstream)
+
+
+
+
+一个 PR 等多久 中位数藏掉的部分:p90 **2.8 h**,最长 **11.9 d**;已关闭 1118 个中 40 个未合并,未计入。单人自合并:量的是变更单元大小,不是评审速度。
+
+
+
+提交语法 让「一百中之七十七」可数:**fix 19.0%** 居首;**996 条主题(22.9%)不合规**——画作空心格,而不是藏起来。
+
+
+
+语言占比 两种口径并陈,而非悄悄二选一:GitHub 端点说 **HTML 67.8%**;剔除那个静态站构建产物仓库后,**Python 69.1%**。字节数度量源码体积,不度量工作量或作者归属。
+
+
+
+上游 PR N = 6,全部具名:2024-06-26 → 2025-12-06,5 个已合并、一个关闭未合并——占全部公开 PR 的千分之几。
+
+
---
### 针对五种崩坏方式而建
diff --git a/scripts/build_profile_svgs.py b/scripts/build_profile_svgs.py
index 10dbcd3..3a534a8 100644
--- a/scripts/build_profile_svgs.py
+++ b/scripts/build_profile_svgs.py
@@ -70,6 +70,7 @@
MIN_SOURCE_COMMITS = 10 # "source repository" = non-fork repo with >= N commits authored by USER
FIRST_YEAR = 2016
RHYTHM_ORIGIN = 4 # hour axis starts at 04:00 so the night block stays contiguous
+HOUR_ORDER = [(RHYTHM_ORIGIN + k) % 24 for k in range(24)]
DIFY_OWNER = "langgenius" # the one upstream ecosystem the READMEs name by hand
CONVENTIONAL = re.compile(
r"^(feat|fix|docs|style|refactor|perf|test|build|ci|chore|revert)(\([^)]*\))?(!)?:\s*\S"
@@ -140,14 +141,6 @@ def die(msg):
sys.exit(1)
-MODE = "write"
-for _arg in sys.argv[1:]:
- if _arg in ("--lint", "--check"):
- MODE = _arg[2:]
- else:
- die(f"unknown argument {_arg!r} — expected --lint or --check")
-
-
# -------------------------------------------------------------- markers ----
def scan_markers(text, f):
"""Ordered [(kind, key)] of the regions in one file, with well-formedness
@@ -237,17 +230,6 @@ def fig(m):
fig, text, flags=re.S)
-if MODE == "lint":
- _orders = {f: scan_markers(t, f) for f, t in read_readmes().items()}
- audit_parity(_orders)
- audit_assets()
- _d = sum(1 for k, _ in _orders[EN] if k == "DATA")
- _g = sum(1 for k, _ in _orders[EN] if k == "FIG")
- print(f"OK lint: {_d} DATA + {_g} FIG regions, identical set and order in "
- f"both READMEs; assets/ clean")
- sys.exit(0)
-
-
def gh(path):
r = subprocess.run(["gh", "api", path], capture_output=True, text=True)
if r.returncode != 0:
@@ -278,12 +260,12 @@ def anon_contribution_counts(url, expect_year=None):
url, headers={"User-Agent": "threefish-profile-refresh"}
)
with urllib.request.urlopen(req, timeout=60, context=SSL_CTX) as r:
- html = r.read().decode("utf-8", "replace")
+ page = r.read().decode("utf-8", "replace")
days = [
int(x.replace(",", ""))
- for x in re.findall(r">([\d,]+) contributions? on ", html)
+ for x in re.findall(r">([\d,]+) contributions? on ", page)
]
- m = re.search(r"]*>([\d,]+) contributions in (\d{4})", html)
+ m = re.search(r"]*>([\d,]+) contributions in (\d{4})", page)
if m and expect_year and int(m.group(2)) == expect_year:
h2_total = int(m.group(1).replace(",", ""))
if sum(days) != h2_total:
@@ -294,126 +276,6 @@ def anon_contribution_counts(url, expect_year=None):
return days
-# ---------------------------------------------------------------- data ----
-print("collecting: yearly contributions (anonymous view) …")
-now = datetime.now(TZ)
-years, values = [], []
-for y in range(FIRST_YEAR, now.year + 1):
- counts = anon_contribution_counts(
- f"https://github.com/users/{USER}/contributions?from={y}-01-01&to={y}-12-31",
- expect_year=y,
- )
- years.append(y)
- values.append(sum(counts))
- print(f" {y}: {values[-1]:,}")
-
-if sum(values) <= 0:
- die("yearly contribution totals are all zero — page parse broken")
-
-print("collecting: repositories …")
-repos = [r for r in gh_paginate(f"users/{USER}/repos?per_page=100") if not r["fork"]]
-total_stars = sum(r["stargazers_count"] for r in repos)
-acc_stars = next((r["stargazers_count"] for r in repos if r["name"] == ACC_REPO), None)
-if acc_stars is None:
- die(f"{ACC_REPO} missing from repo list — star split is undefined")
-own_stars = total_stars - acc_stars
-
-print("collecting: authored commits per repository (first page probe) …")
-repo_commits = {}
-for r in repos:
- name = r["name"]
- page1 = gh(f"repos/{USER}/{name}/commits?author={USER}&per_page=100")
- if len(page1) < MIN_SOURCE_COMMITS:
- continue # below "source repository" threshold
- if len(page1) < 100:
- commits = page1
- else: # keep page1; only the pages after it are new requests
- commits = page1 + gh_paginate(
- f"repos/{USER}/{name}/commits?author={USER}&per_page=100&page=2"
- )
- repo_commits[name] = commits
- print(f" {name}: {len(commits)} authored commits")
-
-src_repos = len(repo_commits)
-all_commits = [c for lst in repo_commits.values() for c in lst]
-commits_total = len(all_commits)
-if commits_total < 100:
- die(f"only {commits_total} authored commits collected — parse likely broken")
-
-hours = Counter()
-weekhours = Counter() # (weekday 0=Mon, hour) -> n
-day_counts = Counter() # date -> n
-lang_of_commit = [] # commit dates for the shared time-domain
-types = Counter() # Conventional Commits type -> n
-conv = 0
-for c in all_commits:
- a = c["commit"]["author"]
- dt = datetime.strptime(a["date"], "%Y-%m-%dT%H:%M:%SZ").replace(
- tzinfo=timezone.utc
- ).astimezone(TZ)
- hours[dt.hour] += 1
- weekhours[(dt.weekday(), dt.hour)] += 1
- day_counts[dt.date()] += 1
- lang_of_commit.append(dt.date())
- m = CONVENTIONAL.match(c["commit"]["message"].split("\n")[0])
- if m:
- conv += 1
- types[m.group(1)] += 1
-
-sorted_days = sorted(day_counts)
-streak = best = 1
-run_start = run_end = sorted_days[0]
-best_start = best_end = sorted_days[0]
-for prev, cur in zip(sorted_days, sorted_days[1:]):
- if (cur - prev).days == 1:
- streak += 1
- run_end = cur
- else:
- streak = 1
- run_start = cur
- if streak > best:
- best, best_start, best_end = streak, run_start, run_end
-streak = best
-
-# The shared x-domain for every time-axis figure (accrual, lifecycles, cadence,
-# streak): three stacked figures with three silently different ranges is a
-# worse honesty failure than any single figure's caveat.
-DOMAIN = (min(lang_of_commit), max(lang_of_commit))
-WIN_DAYS = (DOMAIN[1] - DOMAIN[0]).days + 1
-
-# Pipeline-closure guard: every authored commit must land in exactly one hour
-# bucket. A mismatch means the hour histogram and the repository table below
-# would silently disagree with each other.
-if sum(hours.values()) != commits_total:
- die(
- f"hour histogram {sum(hours.values())} != repo total {commits_total} — "
- "caliber split, refusing"
- )
-if sum(weekhours.values()) != commits_total or sum(day_counts.values()) != commits_total:
- die(f"weekday/day histogram {sum(weekhours.values())}/{sum(day_counts.values())} "
- f"!= repo total {commits_total} — caliber split, refusing")
-if sum(types.values()) != conv:
- die(f"commit-type histogram {sum(types.values())} != conventional count {conv} "
- "— CONVENTIONAL regex drift, refusing")
-
-print("collecting: negentropy pull requests …")
-pulls = gh_paginate(f"repos/{USER}/negentropy/pulls?state=closed&per_page=100")
-merged = [p for p in pulls if p["merged_at"]]
-neg_pr = len(merged)
-pr_closed = len(pulls)
-pr_unmerged = pr_closed - neg_pr
-lifetimes = []
-for p in merged:
- created = datetime.strptime(p["created_at"], "%Y-%m-%dT%H:%M:%SZ")
- merged_at = datetime.strptime(p["merged_at"], "%Y-%m-%dT%H:%M:%SZ")
- lifetimes.append((merged_at - created).total_seconds() / 60)
-lifetimes_sorted = sorted(lifetimes)
-neg_median = statistics.median(lifetimes)
-pct_hour = sum(1 for m in lifetimes if m <= 60) / len(lifetimes) * 100
-p90_lat = lifetimes_sorted[min(len(lifetimes_sorted) - 1, int(round(0.9 * len(lifetimes_sorted))) - 1)]
-lat_max_min = lifetimes_sorted[-1]
-
-
def human_duration(minutes):
if minutes < 60:
return f"{minutes:.0f} min"
@@ -421,77 +283,7 @@ def human_duration(minutes):
return f"{minutes / 60:.1f} h"
return f"{minutes / 60 / 24:.1f} d"
-print("collecting: releases (every source repo, drafts excluded) …")
-# Roster derived from the source repos, never hand-listed: a hand-listed roster
-# silently rendered a real release as 0 for months. Drafts are excluded because
-# they are invisible anonymously but visible to a push-capable token, which
-# would make a local run and a CI run disagree.
-rel_lists = {}
-for name in repo_commits:
- rel_lists[name] = [
- x for x in gh(f"repos/{USER}/{name}/releases?per_page=100") if not x["draft"]
- ]
-rel_counts = {k: len(v) for k, v in rel_lists.items()}
-rel_total = sum(rel_counts.values())
-rel_repos = sum(1 for v in rel_counts.values() if v)
-
-print("collecting: language bytes per source repo (public caliber) …")
-# This is exactly the data behind the language bar a logged-out visitor sees on
-# each repo page — the one endpoint whose naive answer (HTML, 69.7%) is an
-# artifact of a generated static site. The slope figure exists to show both
-# conditions instead of silently picking one.
-repo_langs = {name: gh(f"repos/{USER}/{name}/languages") for name in repo_commits}
-lang_all = Counter()
-lang_src = Counter() # excluding the generated-site repo
GEN_SITE = "threefish-ai.github.io"
-for name, by in repo_langs.items():
- for lang, byts in by.items():
- lang_all[lang] += byts
- if name != GEN_SITE:
- lang_src[lang] += byts
-zero_byte_repos = [n for n, by in repo_langs.items() if not by]
-
-print("collecting: public PR totals (is:public caliber) …")
-pub_prs = gh(
- "search/issues?q=is:pr+author:ThreeFish-AI+is:public&per_page=1"
-)["total_count"]
-# per_page=30 rather than 1: the same request already carries the items, so the
-# upstream ledger below is derived rather than hand-written prose that rots.
-ext = gh(
- "search/issues?q=is:pr+author:ThreeFish-AI+is:public+-user:ThreeFish-AI&per_page=30"
-)
-ext_prs = ext["total_count"]
-ext_items = ext["items"]
-ext_merged = sum(1 for it in ext_items if it["pull_request"]["merged_at"])
-ext_owners = {it["repository_url"].split("/repos/")[1].split("/")[0] for it in ext_items}
-ext_dify = sum(
- 1 for it in ext_items
- if it["pull_request"]["merged_at"]
- and it["repository_url"].split("/repos/")[1].startswith(f"{DIFY_OWNER}/")
-)
-
-archived_names = sorted(
- r["name"] for r in repos if r["archived"] and r["name"] in repo_commits
-)
-
-# ------------------------------------------------------------- guards ----
-if ext_prs > 10:
- die(f"external public PR count = {ext_prs} — search caliber drifted, refusing")
-# The guard above doubles as the ledger's layout contract; keep them together.
-if ext_prs != len(ext_items):
- die(f"external PR ledger truncated: total_count {ext_prs} != items "
- f"{len(ext_items)} — raise per_page, refusing")
-if ext_merged > ext_prs or ext_dify > ext_merged:
- die(f"ledger arithmetic broken: {ext_dify} dify <= {ext_merged} merged <= "
- f"{ext_prs} total violated, refusing")
-if own_stars != total_stars - acc_stars:
- die("star split arithmetic broken")
-if len(years) != len(values) or any(v < 0 for v in values):
- die("year series malformed")
-if set(rel_counts) != set(repo_commits):
- die(f"release roster {sorted(rel_counts)} != source roster "
- f"{sorted(repo_commits)} — a repo's releases would render as 0, refusing")
-
# ----------------------------------------------------------- rendering ----
# Design tokens (Primer palette, WCAG-verified: text >= 4.5:1, graphics >= 3:1
# on both GitHub canvases). No opacity layering — solid inks only.
@@ -523,6 +315,16 @@ def human_duration(minutes):
FONT_SLACK = 1.14
+def parse_iso(s):
+ """GitHub API timestamp (UTC, second precision) as a naive UTC datetime."""
+ return datetime.strptime(s, "%Y-%m-%dT%H:%M:%SZ")
+
+
+def parse_iso_local(s):
+ """The same timestamp re-based into the profile's timezone."""
+ return parse_iso(s).replace(tzinfo=timezone.utc).astimezone(TZ)
+
+
def text_w(s, size):
"""Advance width of `s` in px, over-estimated (see FONT_SLACK). Unknown
Latin falls back to digit width; CJK and other wide scripts to one full em
@@ -596,8 +398,8 @@ def svg_open(w, h, aria):
def render_growth(values, years, asof, aria):
"""`aria` is passed in, not computed here: under %d '
% (L + pitch * (i + 0.5), y) for i, y in enumerate(years))
- sweep_x = R - L
- motion = ("\n .sweep{fill:%s;opacity:0}\n"
- " @media (prefers-color-scheme:dark){.sweep{fill:%s}}\n"
- " @media (prefers-reduced-motion:no-preference){\n"
- " .sweep{animation:swg 1.9s cubic-bezier(.22,1,.36,1) .15s 1 both}\n"
- " @keyframes swg{0%%{opacity:0;transform:translateX(0)}\n"
- " 10%%{opacity:.7}80%%{opacity:.7;transform:translateX(%dpx)}\n"
- " 100%%{opacity:0;transform:translateX(%dpx)}}\n }\n"
- ) % (LIGHT["acc"], DARK["acc"], sweep_x, sweep_x)
+ motion = sweep_x_motion(round(R - L), "swg", "1.9s", ".15s", ".7", 10, 80)
s = "\n".join([
svg_open(W, H, aria),
style_sheet(motion),
@@ -660,9 +453,8 @@ def render_rhythm(hours, asof, aria):
W, H = 700, 168
L, R, BASE = 42.0, 686.0, 126.0
SPAN, MIN_BAR, ZSLOT, ORIGIN = 80.0, 2.5, 4.0, RHYTHM_ORIGIN
- ZERO_Y = BASE + 2
- assert ZERO_Y > BASE # zero slots strictly below the axis
- order = [(ORIGIN + k) % 24 for k in range(24)] # axis 04→03: night block contiguous
+ ZERO_Y = BASE + 2 # zero slots strictly below the axis
+ order = HOUR_ORDER # axis 04→03: night block contiguous
pitch = (R - L) / 24
bw = round(pitch * 0.6, 1)
cmax = max(hours.values()) or 1
@@ -683,15 +475,8 @@ def render_rhythm(hours, asof, aria):
peak_v = hours[peak_h]
ticks = "".join('%02d '
% (L + pitch * (i + 0.5), h) for i, h in enumerate(order) if i % 4 == 0)
- sweep_dx = round(peak_cx - L, 1)
- motion = ("\n .sweep{fill:%s;opacity:0}\n"
- " @media (prefers-color-scheme:dark){.sweep{fill:%s}}\n"
- " @media (prefers-reduced-motion:no-preference){\n"
- " .sweep{animation:swr 2.1s cubic-bezier(.22,1,.36,1) .6s 1 both}\n"
- " @keyframes swr{0%%{opacity:0;transform:translateX(0)}\n"
- " 12%%{opacity:.7}68%%{opacity:.7;transform:translateX(%spx)}\n"
- " 100%%{opacity:0;transform:translateX(%spx)}}\n }\n"
- ) % (LIGHT["acc"], DARK["acc"], sweep_dx, sweep_dx)
+ motion = sweep_x_motion(round(peak_cx - L, 1), "swr", "2.1s", ".6s",
+ ".7", 12, 68)
s = "\n".join([
svg_open(W, H, aria),
style_sheet(motion),
@@ -707,7 +492,7 @@ def render_rhythm(hours, asof, aria):
return s
-def render_ground(repo_commits, rel, asof, aria):
+def render_ground(repo_commits, rel_counts, asof, aria):
W, H = 700, 224
X_NAME, X_BAR, X_REL, MAXW = 150.0, 160.0, 660.0, 420.0
rows = sorted(repo_commits.items(), key=lambda kv: -kv[1])
@@ -722,14 +507,14 @@ def render_ground(repo_commits, rel, asof, aria):
body.append('%s ' % (X_NAME, y + 9, name))
body.append('%s ' % (X_BAR + w + 8, y + 9, "accv" if focus else "val", format(v, ",")))
- body.append('%d ' % (X_REL, y + 9, rel.get(name, 0)))
+ body.append('%d ' % (X_REL, y + 9, rel_counts.get(name, 0)))
i += 1
head = "\n".join([
'repository ' % X_NAME,
'commits ' % X_BAR,
'releases ' % X_REL,
'%s commits · %d '
'releases · %d source repositories · %s %.1f%% '
% (X_BAR, format(total, ","), rel_total, len(repo_commits), rows[0][0], top_share))
@@ -774,6 +559,20 @@ def sweep_y_motion(dy, kf, x0=42, x1=686, y0=30, dur="1.8s", delay=".3s"):
return extra, rect
+def sweep_x_motion(dx, kf, dur, delay, hi, p_lo, p_hi):
+ """One-shot horizontal scan sweep — the translateX twin of sweep_y_motion.
+ Per-figure curve constants stay explicit at the call sites, as tuned."""
+ return ("\n .sweep{fill:%s;opacity:0}\n"
+ " @media (prefers-color-scheme:dark){.sweep{fill:%s}}\n"
+ " @media (prefers-reduced-motion:no-preference){\n"
+ " .sweep{animation:%s %s cubic-bezier(.22,1,.36,1) %s 1 both}\n"
+ " @keyframes %s{0%%{opacity:0;transform:translateX(0)}\n"
+ " %d%%{opacity:%s}%d%%{opacity:%s;transform:translateX(%spx)}\n"
+ " 100%%{opacity:0;transform:translateX(%spx)}}\n }\n"
+ ) % (LIGHT["acc"], DARK["acc"], kf, dur, delay, kf,
+ p_lo, hi, p_hi, hi, dx, dx)
+
+
def month_ticks(domain, L, R, y, step=2):
"""First-of-month x ticks across the shared domain, every `step` months.
@@ -814,7 +613,7 @@ def render_punchcard(weekhours, domain, asof, aria):
TOP, PITCH = 44.0, 17.0
vmax = max(weekhours.values()) or 1
peak = max(weekhours, key=lambda k: weekhours[k])
- order = [(RHYTHM_ORIGIN + k) % 24 for k in range(24)]
+ order = HOUR_ORDER
pitch = (R - L) / 24
wk = {0: "Mon", 1: "Tue", 2: "Wed", 3: "Thu", 4: "Fri", 5: "Sat", 6: "Sun"}
filled, zeros = [], []
@@ -828,7 +627,7 @@ def render_punchcard(weekhours, domain, asof, aria):
elif (wd, h) != peak: # the peak cell draws as the accented square
s = max(round(math.sqrt(v / vmax) * 13, 1), 2.2)
filled.append("M%.1f %.1fh%.1fv%.1fh-%.1fz" % (cx - s / 2, cy - s / 2, s, s, s))
- pc, pr = landing_motion("ring", "pcr",
+ mo, ring = landing_motion("ring", "pcr",
L + pitch * (order.index(peak[1]) + 0.5),
TOP + 4 + peak[0] * PITCH + PITCH / 2 - 2, "1.7s", ".5s")
s = max(round(math.sqrt(weekhours[peak] / vmax) * 13, 1), 2.2)
@@ -840,12 +639,12 @@ def render_punchcard(weekhours, domain, asof, aria):
% (L - 6, TOP + 4 + wd * PITCH + PITCH / 2, wk[wd]) for wd in range(7))
return "\n".join([
svg_open(W, H, aria),
- style_sheet(pc),
+ style_sheet(mo),
'commits by weekday × hour · cell area ∝ count · axis 04→03 · %s → %s '
% (L, domain[0], domain[1]),
@@ -860,7 +659,7 @@ def render_surplus(wd_hour, we_hour, wd_days, we_days, domain, asof, aria):
W, H = 700, 178
L, R, BASE = 42.0, 686.0, 138.0
SPAN, MIN_BAR = 92.0, 2.0
- order = [(RHYTHM_ORIGIN + k) % 24 for k in range(24)]
+ order = HOUR_ORDER
pitch = (R - L) / 24
wd_rate = [wd_hour[h] / wd_days for h in order]
we_rate = [we_hour[h] / we_days for h in order]
@@ -881,14 +680,7 @@ def step_path(rates, cls):
wp_i = wd_rate.index(max(wd_rate))
ep_i = we_rate.index(max(we_rate))
- motion = ("\n .sweep{fill:%s;opacity:0}\n"
- " @media (prefers-color-scheme:dark){.sweep{fill:%s}}\n"
- " @media (prefers-reduced-motion:no-preference){\n"
- " .sweep{animation:sws 2s cubic-bezier(.22,1,.36,1) .5s 1 both}\n"
- " @keyframes sws{0%%{opacity:0;transform:translateX(0)}\n"
- " 12%%{opacity:.6}70%%{opacity:.6;transform:translateX(%dpx)}\n"
- " 100%%{opacity:0;transform:translateX(%dpx)}}\n }\n"
- ) % (LIGHT["acc"], DARK["acc"], round(R - L), round(R - L))
+ motion = sweep_x_motion(round(R - L), "sws", "2s", ".5s", ".6", 12, 70)
ticks = "".join('%02d '
% (L + pitch * (i + 0.5), h) for i, h in enumerate(order) if i % 4 == 0)
return "\n".join([
@@ -1052,7 +844,7 @@ def render_cadence(rel_lists, domain, asof, aria):
rels = sorted(rels, key=lambda r: r["published_at"])
body.append('%s '
% (fx, y + 15, FS, first["tag_name"]))
if last is not first:
- lx = x_date(datetime.strptime(last["published_at"], "%Y-%m-%dT%H:%M:%SZ")
+ lx = x_date(parse_iso(last["published_at"])
.replace(tzinfo=timezone.utc).date(), domain, L, R) - 3
if lx - text_w(last["tag_name"], FS) > fx + text_w(first["tag_name"], FS) + 4:
body.append('%s '
@@ -1130,17 +922,11 @@ def render_streak(day_counts, run, dom, asof, aria):
if run0 is not None:
runs.append("M%d %dH%d" % (run0, BASE + 3, round(R)))
bx0, bx1 = round(x_date(run[0], dom, L, R)), round(x_date(run[1], dom, L, R))
- motion = ("\n .tick{stroke:%s;fill:none;stroke-width:1.4}\n"
- " @media (prefers-color-scheme:dark){.tick{stroke:%s}}\n"
- " .sweep{fill:%s;opacity:0}\n"
- " @media (prefers-color-scheme:dark){.sweep{fill:%s}}\n"
- " @media (prefers-reduced-motion:no-preference){\n"
- " .sweep{animation:sbs 1.8s cubic-bezier(.22,1,.36,1) .5s 1 both}\n"
- " @keyframes sbs{0%%{opacity:0;transform:translateX(0)}\n"
- " 15%%{opacity:.65}75%%{opacity:.65;transform:translateX(%dpx)}\n"
- " 100%%{opacity:0;transform:translateX(%dpx)}}\n }\n"
- ) % (LIGHT["bar"], DARK["bar"], LIGHT["acc"], DARK["acc"],
- max(bx1 - bx0, 2), max(bx1 - bx0, 2))
+ ticks_css = ("\n .tick{stroke:%s;fill:none;stroke-width:1.4}\n"
+ " @media (prefers-color-scheme:dark){.tick{stroke:%s}}"
+ ) % (LIGHT["bar"], DARK["bar"])
+ motion = ticks_css + sweep_x_motion(max(bx1 - bx0, 2), "sbs", "1.8s",
+ ".5s", ".65", 15, 75)
return "\n".join([
svg_open(W, H, aria),
style_sheet(motion),
@@ -1222,7 +1008,7 @@ def render_latency(buckets, ecdf, stats, asof, aria):
"", ""])
-def render_grammar(types_sorted, nonconf, total, sub1pct, asof, aria):
+def render_grammar(types_sorted, nonconf, total, under_one_pct_note, asof, aria):
"""100-cell waffle: makes "77 of 100" countable. Types under one percent
earn no cell and are folded into the footer instead of stealing one. Height
is derived from content: the last waffle row and the last legend row both
@@ -1235,7 +1021,7 @@ def render_grammar(types_sorted, nonconf, total, sub1pct, asof, aria):
xi = yi = 0
used = 0
- def emit(n, cls):
+ def emit(n):
nonlocal xi, yi, used
d = []
for _ in range(n):
@@ -1249,7 +1035,7 @@ def emit(n, cls):
return d
for rank, (name, c) in enumerate(types_sorted):
- d = emit(round(c / total * 100), "acc" if rank == 0 else "bar")
+ d = emit(round(c / total * 100))
if d:
cells.append('%s %d '
@@ -1257,7 +1043,7 @@ def emit(n, cls):
# The non-conforming block takes every cell the types did not — exactly
# 100 cells are drawn, so "one cell = one percent" stays literally true.
filled = used # snapshot: the open cells below drive the cursor to 100
- zc = emit(100 - used, "zero")
+ zc = emit(100 - used)
mo, ring = landing_motion("ring", "grr",
X0 + (filled % 10 - 0.5) * P, Y0 + (filled // 10) * P + 5,
"1.5s", ".7s")
@@ -1274,7 +1060,7 @@ def emit(n, cls):
'commit subjects by Conventional Commits type · one cell = one percent of %s '
% (42, format(total, ",")),
'open cells do not parse as Conventional Commits · %s '
- % (42, sub1pct),
+ % (42, under_one_pct_note),
'as of %s ' % (686, H - 8, asof),
"", ""])
@@ -1285,16 +1071,16 @@ def render_tongues(lang_all, lang_src, gen_site, zero_repos, asof, aria):
one named repo and it says Python. Both conditions, not a silent pick."""
W, H = 700, 196
XL, XR = 210.0, 470.0
- ta = sum(lang_all.values()) or 1
- ts = sum(lang_src.values()) or 1
+ total_all = sum(lang_all.values()) or 1
+ total_src = sum(lang_src.values()) or 1
names = sorted(set(lang_all) | set(lang_src),
key=lambda n: -lang_src.get(n, 0))[:7]
if "HTML" not in names and lang_all.get("HTML"):
names.append("HTML")
TOP, STEP, SPAN = 44.0, 19.0, 116.0
- na = {n: lang_all.get(n, 0) / ta for n in names}
- ns = {n: lang_src.get(n, 0) / ts for n in names}
- ymax = max(list(na.values()) + list(ns.values())) or 1
+ share_all = {n: lang_all.get(n, 0) / total_all for n in names}
+ share_src = {n: lang_src.get(n, 0) / total_src for n in names}
+ ymax = max(list(share_all.values()) + list(share_src.values())) or 1
def y_of(p):
return TOP + SPAN - p / ymax * SPAN
@@ -1302,15 +1088,15 @@ def y_of(p):
body = []
left, right = [], []
for n in names:
- y1, y2 = y_of(na[n]), y_of(ns[n])
- acc = n == max(ns, key=ns.get)
+ y1, y2 = y_of(share_all[n]), y_of(share_src[n])
+ acc = n == max(share_src, key=share_src.get)
body.append('%s '
% (XR + 8, ly, cls, txt))
- others_a = 1 - sum(na.values())
- others_s = 1 - sum(ns.values())
+ others_a = 1 - sum(share_all.values())
+ others_s = 1 - sum(share_src.values())
return "\n".join([
svg_open(W, H, aria),
style_sheet(),
@@ -1352,15 +1138,15 @@ def render_upstream(items, pub_prs, asof, aria):
# by the ext_prs <= 10 guard, so the figure simply grows a row instead.
BASE = TOP + (len(rows) - 1) * PITCH + 16
H = int(BASE + 50)
- d0 = datetime.strptime(rows[0]["created_at"], "%Y-%m-%dT%H:%M:%SZ").date()
- d1 = datetime.strptime(rows[-1]["created_at"], "%Y-%m-%dT%H:%M:%SZ").date()
+ d0 = parse_iso(rows[0]["created_at"]).date()
+ d1 = parse_iso(rows[-1]["created_at"]).date()
if d1 == d0: # single PR (or several on one day): give the axis some span
d0 -= timedelta(days=15)
d1 += timedelta(days=15)
dom = (d0, d1)
body = []
for i, it in enumerate(rows):
- dt = datetime.strptime(it["created_at"], "%Y-%m-%dT%H:%M:%SZ").date()
+ dt = parse_iso(it["created_at"]).date()
x = x_date(dt, dom, L, R)
y = TOP + i * PITCH
slug = it["repository_url"].split("/repos/")[1]
@@ -1551,7 +1337,7 @@ def growth_shape(values, years):
def zero_runs(hours):
"""Contiguous runs of true-zero hours along the 04→03 axis, as [(lo, hi)]."""
runs, run = [], []
- for h in [(RHYTHM_ORIGIN + k) % 24 for k in range(24)]:
+ for h in HOUR_ORDER:
if hours[h] == 0:
run.append(h)
elif run:
@@ -1560,7 +1346,7 @@ def zero_runs(hours):
return runs + ([(run[0], run[-1])] if run else [])
-def _join(parts, sep, last):
+def oxford_join(parts, sep, last):
if len(parts) < 2:
return "".join(parts)
return sep.join(parts[:-1]) + last + parts[-1]
@@ -1573,7 +1359,7 @@ def growth_alt(f, values, years):
if f == EN:
zc = ("" if not z else
" %s %s exactly zero, drawn as %s below the axis." % (
- _join(z, ", ", " and "), "is" if len(z) == 1 else "are",
+ oxford_join(z, ", ", " and "), "is" if len(z) == 1 else "are",
"an open slot" if len(z) == 1 else "open slots"))
dc = "".join(" %d (%s) is lower than %d (%s)." % (y, format(v, ","), py, format(pv, ","))
for y, v, py, pv in sh["dips"])
@@ -1587,7 +1373,7 @@ def growth_alt(f, values, years):
def rhythm_alt(f, hours):
- order = [(RHYTHM_ORIGIN + k) % 24 for k in range(24)]
+ order = HOUR_ORDER
seq = ", ".join(str(hours[h]) for h in order)
total = sum(hours.values())
ph = max(hours, key=lambda h: hours[h])
@@ -1596,7 +1382,7 @@ def rhythm_alt(f, hours):
last = (RHYTHM_ORIGIN + 23) % 24
if f == EN:
zc = ("" if not runs else " %s exactly zero, drawn as open slots below the axis." % (
- _join(["%02d:00 to %02d:59" % r for r in runs], ", ", " and ") +
+ oxford_join(["%02d:00 to %02d:59" % r for r in runs], ", ", " and ") +
(" is" if len(runs) == 1 and runs[0][0] == runs[0][1] else " are")))
return ("Histogram of %s open-source commits by hour of day, Asia/Shanghai, axis "
"running %02d:00 through %02d:00 so the night block stays contiguous. Values "
@@ -1622,7 +1408,7 @@ def ground_alt(f, counts, rel, archived):
rel_rows = [(n, c) for n, c in sorted(rel.items(), key=lambda kv: -kv[1]) if c]
if f == EN:
arc = ("" if not archived else " %s %s archived — %s graduated into the negentropy trunk."
- % (_join(archived, ", ", " and "), "is" if len(archived) == 1 else "are",
+ % (oxford_join(archived, ", ", " and "), "is" if len(archived) == 1 else "are",
"it" if len(archived) == 1 else "they"))
return ("Horizontal bar chart, commits per source repository, sorted: %s. Total %s "
"commits and %d releases across %d source repositories; %s is %.1f percent of "
@@ -1670,11 +1456,11 @@ def punchcard_alt(f, weekhours, domain, wknd, wd_days, we_days):
def surplus_alt(f, wd_hour, we_hour, wd_days, we_days, domain):
- order = [(RHYTHM_ORIGIN + k) % 24 for k in range(24)]
+ order = HOUR_ORDER
wd_seq = ", ".join("%.1f" % (wd_hour[h] / wd_days) for h in order)
we_seq = ", ".join("%.1f" % (we_hour[h] / we_days) for h in order)
- wp = max(range(24), key=lambda h: wd_hour[h])
- ep = max(range(24), key=lambda h: we_hour[h])
+ wd_peak_h = max(range(24), key=lambda h: wd_hour[h])
+ we_peak_h = max(range(24), key=lambda h: we_hour[h])
if f == EN:
return ("Two step curves on one hour-of-day axis running 04:00 to 03:00, "
"Asia/Shanghai, %s to %s, normalised to commits per day of that kind so "
@@ -1682,13 +1468,13 @@ def surplus_alt(f, wd_hour, we_hour, wd_days, we_days, domain):
"04:00: %s. Weekend rate: %s. Weekday peak %02d:00 at %.1f per day; "
"weekend peak %02d:00 at %.1f. Data: GitHub."
% (domain[0], domain[1], wd_days, we_days, wd_seq, we_seq,
- wp, wd_hour[wp] / wd_days, ep, we_hour[ep] / we_days))
+ wd_peak_h, wd_hour[wd_peak_h] / wd_days, we_peak_h, we_hour[we_peak_h] / we_days))
return ("同一小时轴(04:00 至 03:00,Asia/Shanghai,%s 至 %s)上的两条阶梯曲线,"
"按「该类日」归一为日均提交,使 %d 个工作日与 %d 个周末日可比。工作日自 04:00 起"
"逐小时速率:%s。周末:%s。工作日峰值 %02d:00(日均 %.1f 条);周末峰值 %02d:00"
"(日均 %.1f 条)。数据:GitHub。"
% (domain[0], domain[1], wd_days, we_days, wd_seq, we_seq,
- wp, wd_hour[wp] / wd_days, ep, we_hour[ep] / we_days))
+ wd_peak_h, wd_hour[wd_peak_h] / wd_days, we_peak_h, we_hour[we_peak_h] / we_days))
def accrual_alt(f, monthly, domain, events, final_total):
@@ -1705,7 +1491,7 @@ def accrual_alt(f, monthly, domain, events, final_total):
ev_txt = " ".join(
"On %s %s flatten%s and the trunk keeps rising: %s graduated into the "
"negentropy trunk that day." % (
- d, _join(nms, ", ", " and "), "" if len(nms) > 1 else "s",
+ d, oxford_join(nms, ", ", " and "), "" if len(nms) > 1 else "s",
"they" if len(nms) > 1 else "it")
for d, nms in by_date.items())
return ("Cumulative authored commits per source repository at monthly resolution, "
@@ -1743,41 +1529,6 @@ def lifecycles_alt(f, spans, domain):
% (domain[0], domain[1], rows))
-def cadence_alt(f, rel_lists, domain, trunk_commits):
- lanes = sorted(((n, sorted(v, key=lambda r: r["published_at"]))
- for n, v in rel_lists.items() if v),
- key=lambda kv: (-len(kv[1]), kv[0]))
- # The trunk sentence carries two numbers that MOVE — negentropy is the
- # active repo, so a literal here would have the alt contradict the
- # neg_commits marker rendered beside it within a month.
- trunk_rels = len(rel_lists.get(TRUNK, ()))
- if f == EN:
- rows = "; ".join(
- "%s: %d releases, %s on %s through %s on %s%s" % (
- n, len(v), v[0]["tag_name"], v[0]["published_at"][:10],
- v[-1]["tag_name"], v[-1]["published_at"][:10],
- "" if not all(r["prerelease"] for r in v) else ", all pre-releases")
- for n, v in lanes)
- return ("Dot timeline of %d public releases across %d repositories on one shared "
- "date axis, %s to %s. %s. Hollow dots are pre-releases. %s shows only its "
- "%d release candidates against %s commits because it is a deployed "
- "service, not a distributed package — its shipping unit is the merged "
- "pull request, not the tag. Data: GitHub."
- % (rel_total, len(lanes), domain[0], domain[1], rows,
- TRUNK, trunk_rels, format(trunk_commits, ",")))
- rows = ";".join(
- "%s %d 个 release,%s(%s)至 %s(%s)%s" % (
- n, len(v), v[0]["tag_name"], v[0]["published_at"][:10],
- v[-1]["tag_name"], v[-1]["published_at"][:10],
- "" if not all(r["prerelease"] for r in v) else ",全部为预发布")
- for n, v in lanes)
- return ("各仓库公开 release 的点式时间线(共用日期轴,%s 至 %s)。%s。空心点为预发布。"
- "%s 在 %s 条提交面前只有 %d 个 rc,因为它是部署型服务而非分发包——"
- "它的交付单元是已合并 PR,不是 tag。数据:GitHub。"
- % (domain[0], domain[1], rows,
- TRUNK, format(trunk_commits, ","), trunk_rels))
-
-
def streak_alt(f, act, zeros, best, dom, rug_days):
if f == EN:
return ("Rug plot, one tick per day over the latest %d days, %s to %s; tick height "
@@ -1904,60 +1655,6 @@ def upstream_alt(f, items, pub_prs):
ledger, format(pub_prs, ","), len(rows) / pub_prs * 100))
-# ------------------------------------------------- figure derivations ----
-# Degenerate-but-reachable shapes die cleanly here instead of raising a bare
-# traceback further down; the write-nothing contract holds either way.
-if not lifetimes:
- die("no merged PRs in negentropy — latency figures undefined, refusing")
-if not any(rel_lists.values()):
- die("no releases in any source repo — release figures undefined, refusing")
-if not types:
- die("no Conventional Commits found — grammar figure undefined, refusing")
-if not lang_src:
- die("no language bytes outside the generated-site repo — tongues undefined, refusing")
-
-peak_cell = max(weekhours, key=lambda k: weekhours[k])
-wknd = sum(n for (wd, _), n in weekhours.items() if wd >= 5)
-types_sorted = types.most_common()
-rel_last = max(
- ((n, r["tag_name"], r["published_at"]) for n, v in rel_lists.items() for r in v),
- key=lambda t: t[2])[:2]
-wd_hour = Counter()
-we_hour = Counter()
-wd_days = we_days = 0
-_d = DOMAIN[0]
-while _d <= DOMAIN[1]: # calendar denominators: every day counts, commit or not
- if _d.weekday() >= 5:
- we_days += 1
- else:
- wd_days += 1
- _d += timedelta(days=1)
-if wd_days == 0 or we_days == 0:
- die(f"window has {wd_days} weekdays / {we_days} weekend days — "
- "surplus normalisation undefined, refusing")
-for (wd, h), n in weekhours.items():
- (we_hour if wd >= 5 else wd_hour)[h] += n
-we_peak = max(we_hour, key=lambda h: we_hour[h])
-monthly = Counter()
-for name, lst in repo_commits.items():
- for c in lst:
- dt = datetime.strptime(c["commit"]["author"]["date"], "%Y-%m-%dT%H:%M:%SZ").replace(
- tzinfo=timezone.utc).astimezone(TZ)
- monthly[(name, dt.date().replace(day=1))] += 1
-# Graduation events for the accrual figure: pushed_at of the archived repos is
-# the closest public proxy (GitHub exposes no archive timestamp); the renderer
-# labels the axis "last push", never "archived on".
-grad_events = [
- (datetime.strptime(r["pushed_at"], "%Y-%m-%dT%H:%M:%SZ").date(), r["name"])
- for r in repos if r["archived"] and r["name"] in repo_commits
-]
-spans = [
- (r["name"],
- datetime.strptime(r["created_at"], "%Y-%m-%dT%H:%M:%SZ").date(),
- datetime.strptime(r["pushed_at"], "%Y-%m-%dT%H:%M:%SZ").date(),
- r["archived"])
- for r in repos if r["name"] in repo_commits
-]
LAT_EDGES = [1, 2, 5, 15, 60, 240, 1440, float("inf")]
LAT_LABELS = ["<1m", "1-2", "2-5", "5-15", "15-60m", "1-4h", "4-24h", ">24h"]
@@ -1969,254 +1666,550 @@ def bucket_of(m):
return len(LAT_EDGES) - 1
-lat_buckets = [(LAT_LABELS[i], sum(1 for m in lifetimes if bucket_of(m) == i))
- for i in range(len(LAT_LABELS))]
+RUG_DAYS = 400
+def refresh():
+ # ---------------------------------------------------------------- data ----
+ print("collecting: yearly contributions (anonymous view) …")
+ now = datetime.now(TZ)
+ years, values = [], []
+ for y in range(FIRST_YEAR, now.year + 1):
+ counts = anon_contribution_counts(
+ f"https://github.com/users/{USER}/contributions?from={y}-01-01&to={y}-12-31",
+ expect_year=y,
+ )
+ years.append(y)
+ values.append(sum(counts))
+ print(f" {y}: {values[-1]:,}")
+
+ if sum(values) <= 0:
+ die("yearly contribution totals are all zero — page parse broken")
+
+ print("collecting: repositories …")
+ repos = [r for r in gh_paginate(f"users/{USER}/repos?per_page=100") if not r["fork"]]
+ total_stars = sum(r["stargazers_count"] for r in repos)
+ acc_stars = next((r["stargazers_count"] for r in repos if r["name"] == ACC_REPO), None)
+ if acc_stars is None:
+ die(f"{ACC_REPO} missing from repo list — star split is undefined")
+ own_stars = total_stars - acc_stars
+
+ print("collecting: authored commits per repository (first page probe) …")
+ repo_commits = {}
+ for r in repos:
+ name = r["name"]
+ page1 = gh(f"repos/{USER}/{name}/commits?author={USER}&per_page=100")
+ if len(page1) < MIN_SOURCE_COMMITS:
+ continue # below "source repository" threshold
+ if len(page1) < 100:
+ commits = page1
+ else: # keep page1; only the pages after it are new requests
+ commits = page1 + gh_paginate(
+ f"repos/{USER}/{name}/commits?author={USER}&per_page=100&page=2"
+ )
+ repo_commits[name] = commits
+ print(f" {name}: {len(commits)} authored commits")
+
+ src_repos = len(repo_commits)
+ all_commits = [c for lst in repo_commits.values() for c in lst]
+ commits_total = len(all_commits)
+ if commits_total < 100:
+ die(f"only {commits_total} authored commits collected — parse likely broken")
+
+ hours = Counter()
+ weekhours = Counter() # (weekday 0=Mon, hour) -> n
+ day_counts = Counter() # date -> n
+ commit_dates = [] # commit dates for the shared time-domain
+ types = Counter() # Conventional Commits type -> n
+ conv = 0
+ for c in all_commits:
+ a = c["commit"]["author"]
+ dt = parse_iso_local(a["date"])
+ hours[dt.hour] += 1
+ weekhours[(dt.weekday(), dt.hour)] += 1
+ day_counts[dt.date()] += 1
+ commit_dates.append(dt.date())
+ m = CONVENTIONAL.match(c["commit"]["message"].split("\n")[0])
+ if m:
+ conv += 1
+ types[m.group(1)] += 1
+
+ def windowed_run(dom):
+ """Longest streak + activity counts INSIDE the rug's rolling window, so the
+ figure's bracket and its alt text can never disagree with its own axis.
+ The first active day is itself a run of length 1."""
+ wd_days = [d for d in sorted(day_counts) if dom[0] <= d <= dom[1]]
+ if not wd_days:
+ die("no authored commits inside the rug window — streak figure undefined")
+ best, b_start, b_end, run = 1, wd_days[0], wd_days[0], 1
+ for prev, cur in zip(wd_days, wd_days[1:]):
+ run = run + 1 if (cur - prev).days == 1 else 1
+ if run > best:
+ best, b_end = run, cur
+ b_start = cur - timedelta(days=run - 1)
+ return len(wd_days), best, (b_start, b_end)
+
+
+ # One counting implementation for both records: the all-time streak is the
+ # windowed run over the full domain (windowed_run dies cleanly on an empty
+ # window where the old hand-rolled loop would IndexError).
+ sorted_days = sorted(day_counts)
+ _, streak, (best_start, best_end) = windowed_run(
+ (sorted_days[0], sorted_days[-1]))
+
+ # The shared x-domain for every time-axis figure (accrual, lifecycles, cadence,
+ # streak): three stacked figures with three silently different ranges is a
+ # worse honesty failure than any single figure's caveat.
+ DOMAIN = (min(commit_dates), max(commit_dates))
+ WIN_DAYS = (DOMAIN[1] - DOMAIN[0]).days + 1
+
+ # Pipeline-closure guard: every authored commit must land in exactly one hour
+ # bucket. A mismatch means the hour histogram and the repository table below
+ # would silently disagree with each other.
+ if sum(hours.values()) != commits_total:
+ die(
+ f"hour histogram {sum(hours.values())} != repo total {commits_total} — "
+ "caliber split, refusing"
+ )
+ if sum(weekhours.values()) != commits_total or sum(day_counts.values()) != commits_total:
+ die(f"weekday/day histogram {sum(weekhours.values())}/{sum(day_counts.values())} "
+ f"!= repo total {commits_total} — caliber split, refusing")
+ if sum(types.values()) != conv:
+ die(f"commit-type histogram {sum(types.values())} != conventional count {conv} "
+ "— CONVENTIONAL regex drift, refusing")
+
+ print("collecting: negentropy pull requests …")
+ pulls = gh_paginate(f"repos/{USER}/negentropy/pulls?state=closed&per_page=100")
+ merged = [p for p in pulls if p["merged_at"]]
+ neg_pr = len(merged)
+ pr_closed = len(pulls)
+ pr_unmerged = pr_closed - neg_pr
+ lifetimes = []
+ for p in merged:
+ created = parse_iso(p["created_at"])
+ merged_at = parse_iso(p["merged_at"])
+ lifetimes.append((merged_at - created).total_seconds() / 60)
+ lifetimes_sorted = sorted(lifetimes)
+ neg_median = statistics.median(lifetimes)
+ pct_hour = sum(1 for m in lifetimes if m <= 60) / len(lifetimes) * 100
+ p90_lat = lifetimes_sorted[min(len(lifetimes_sorted) - 1, int(round(0.9 * len(lifetimes_sorted))) - 1)]
+ lat_max_min = lifetimes_sorted[-1]
+
+
+ print("collecting: releases (every source repo, drafts excluded) …")
+ # Roster derived from the source repos, never hand-listed: a hand-listed roster
+ # silently rendered a real release as 0 for months. Drafts are excluded because
+ # they are invisible anonymously but visible to a push-capable token, which
+ # would make a local run and a CI run disagree.
+ rel_lists = {}
+ for name in repo_commits:
+ rel_lists[name] = [
+ x for x in gh(f"repos/{USER}/{name}/releases?per_page=100") if not x["draft"]
+ ]
+ rel_counts = {k: len(v) for k, v in rel_lists.items()}
+ rel_total = sum(rel_counts.values())
+ rel_repos = sum(1 for v in rel_counts.values() if v)
+
+ print("collecting: language bytes per source repo (public caliber) …")
+ # This is exactly the data behind the language bar a logged-out visitor sees on
+ # each repo page — the one endpoint whose naive answer (HTML, 69.7%) is an
+ # artifact of a generated static site. The slope figure exists to show both
+ # conditions instead of silently picking one.
+ repo_langs = {name: gh(f"repos/{USER}/{name}/languages") for name in repo_commits}
+ lang_all = Counter()
+ lang_src = Counter() # excluding the generated-site repo
+ for name, by in repo_langs.items():
+ for lang, byts in by.items():
+ lang_all[lang] += byts
+ if name != GEN_SITE:
+ lang_src[lang] += byts
+ zero_byte_repos = [n for n, by in repo_langs.items() if not by]
+
+ print("collecting: public PR totals (is:public caliber) …")
+ pub_prs = gh(
+ "search/issues?q=is:pr+author:ThreeFish-AI+is:public&per_page=1"
+ )["total_count"]
+ # per_page=30 rather than 1: the same request already carries the items, so the
+ # upstream ledger below is derived rather than hand-written prose that rots.
+ ext = gh(
+ "search/issues?q=is:pr+author:ThreeFish-AI+is:public+-user:ThreeFish-AI&per_page=30"
+ )
+ ext_prs = ext["total_count"]
+ ext_items = ext["items"]
+ ext_merged = sum(1 for it in ext_items if it["pull_request"]["merged_at"])
+ ext_dify = sum(
+ 1 for it in ext_items
+ if it["pull_request"]["merged_at"]
+ and it["repository_url"].split("/repos/")[1].startswith(f"{DIFY_OWNER}/")
+ )
-def ecdf_points():
- cum, out = 0, []
- for i, (_, c) in enumerate(lat_buckets):
- cum += c
- out.append(cum / len(lifetimes) * 100)
- return out
+ archived_names = sorted(
+ r["name"] for r in repos if r["archived"] and r["name"] in repo_commits
+ )
+ # ------------------------------------------------------------- guards ----
+ if ext_prs > 10:
+ die(f"external public PR count = {ext_prs} — search caliber drifted, refusing")
+ # The guard above doubles as the ledger's layout contract; keep them together.
+ if ext_prs != len(ext_items):
+ die(f"external PR ledger truncated: total_count {ext_prs} != items "
+ f"{len(ext_items)} — raise per_page, refusing")
+ if ext_merged > ext_prs or ext_dify > ext_merged:
+ die(f"ledger arithmetic broken: {ext_dify} dify <= {ext_merged} merged <= "
+ f"{ext_prs} total violated, refusing")
+ if len(years) != len(values) or any(v < 0 for v in values):
+ die("year series malformed")
+ if set(rel_counts) != set(repo_commits):
+ die(f"release roster {sorted(rel_counts)} != source roster "
+ f"{sorted(repo_commits)} — a repo's releases would render as 0, refusing")
+
+ def cadence_alt(f, rel_lists, domain, trunk_commits):
+ lanes = sorted(((n, sorted(v, key=lambda r: r["published_at"]))
+ for n, v in rel_lists.items() if v),
+ key=lambda kv: (-len(kv[1]), kv[0]))
+ # The trunk sentence carries two numbers that MOVE — negentropy is the
+ # active repo, so a literal here would have the alt contradict the
+ # neg_commits marker rendered beside it within a month.
+ trunk_rels = len(rel_lists.get(TRUNK, ()))
+ if f == EN:
+ rows = "; ".join(
+ "%s: %d releases, %s on %s through %s on %s%s" % (
+ n, len(v), v[0]["tag_name"], v[0]["published_at"][:10],
+ v[-1]["tag_name"], v[-1]["published_at"][:10],
+ "" if not all(r["prerelease"] for r in v) else ", all pre-releases")
+ for n, v in lanes)
+ return ("Dot timeline of %d public releases across %d repositories on one shared "
+ "date axis, %s to %s. %s. Hollow dots are pre-releases. %s shows only its "
+ "%d release candidates against %s commits because it is a deployed "
+ "service, not a distributed package — its shipping unit is the merged "
+ "pull request, not the tag. Data: GitHub."
+ % (rel_total, len(lanes), domain[0], domain[1], rows,
+ TRUNK, trunk_rels, format(trunk_commits, ",")))
+ rows = ";".join(
+ "%s %d 个 release,%s(%s)至 %s(%s)%s" % (
+ n, len(v), v[0]["tag_name"], v[0]["published_at"][:10],
+ v[-1]["tag_name"], v[-1]["published_at"][:10],
+ "" if not all(r["prerelease"] for r in v) else ",全部为预发布")
+ for n, v in lanes)
+ return ("各仓库公开 release 的点式时间线(共用日期轴,%s 至 %s)。%s。空心点为预发布。"
+ "%s 在 %s 条提交面前只有 %d 个 rc,因为它是部署型服务而非分发包——"
+ "它的交付单元是已合并 PR,不是 tag。数据:GitHub。"
+ % (domain[0], domain[1], rows,
+ TRUNK, format(trunk_commits, ","), trunk_rels))
+
+
+ # ------------------------------------------------- figure derivations ----
+ # Degenerate-but-reachable shapes die cleanly here instead of raising a bare
+ # traceback further down; the write-nothing contract holds either way.
+ if not lifetimes:
+ die("no merged PRs in negentropy — latency figures undefined, refusing")
+ if not any(rel_lists.values()):
+ die("no releases in any source repo — release figures undefined, refusing")
+ if not types:
+ die("no Conventional Commits found — grammar figure undefined, refusing")
+ if not lang_src:
+ die("no language bytes outside the generated-site repo — tongues undefined, refusing")
+
+ peak_cell = max(weekhours, key=lambda k: weekhours[k])
+ wknd = sum(n for (wd, _), n in weekhours.items() if wd >= 5)
+ types_sorted = types.most_common()
+ rel_last = max(
+ ((n, r["tag_name"], r["published_at"]) for n, v in rel_lists.items() for r in v),
+ key=lambda t: t[2])[:2]
+ wd_hour = Counter()
+ we_hour = Counter()
+ wd_days = we_days = 0
+ _d = DOMAIN[0]
+ while _d <= DOMAIN[1]: # calendar denominators: every day counts, commit or not
+ if _d.weekday() >= 5:
+ we_days += 1
+ else:
+ wd_days += 1
+ _d += timedelta(days=1)
+ if wd_days == 0 or we_days == 0:
+ die(f"window has {wd_days} weekdays / {we_days} weekend days — "
+ "surplus normalisation undefined, refusing")
+ for (wd, h), n in weekhours.items():
+ (we_hour if wd >= 5 else wd_hour)[h] += n
+ we_peak = max(we_hour, key=lambda h: we_hour[h])
+ monthly = Counter()
+ for name, lst in repo_commits.items():
+ for c in lst:
+ dt = parse_iso_local(c["commit"]["author"]["date"])
+ monthly[(name, dt.date().replace(day=1))] += 1
+ # Graduation events for the accrual figure: pushed_at of the archived repos is
+ # the closest public proxy (GitHub exposes no archive timestamp); the renderer
+ # labels the axis "last push", never "archived on".
+ grad_events = [
+ (parse_iso(r["pushed_at"]).date(), r["name"])
+ for r in repos if r["archived"] and r["name"] in repo_commits
+ ]
+ spans = [
+ (r["name"],
+ parse_iso(r["created_at"]).date(),
+ parse_iso(r["pushed_at"]).date(),
+ r["archived"])
+ for r in repos if r["name"] in repo_commits
+ ]
+ lat_buckets = [(LAT_LABELS[i], sum(1 for m in lifetimes if bucket_of(m) == i))
+ for i in range(len(LAT_LABELS))]
+
+
+ def ecdf_points():
+ cum, out = 0, []
+ for i, (_, c) in enumerate(lat_buckets):
+ cum += c
+ out.append(cum / len(lifetimes) * 100)
+ return out
+
+
+ lat_stats = {
+ "n": neg_pr,
+ "unmerged": pr_unmerged,
+ "med": human_duration(neg_median),
+ "p90": human_duration(p90_lat),
+ "med_i": next(i for i, m in enumerate(LAT_EDGES) if neg_median <= m),
+ "hour_i": LAT_EDGES.index(60),
+ "lat_max": human_duration(lat_max_min),
+ }
-lat_stats = {
- "n": neg_pr,
- "unmerged": pr_unmerged,
- "med": human_duration(neg_median),
- "p90": human_duration(p90_lat),
- "med_i": next(i for i, m in enumerate(LAT_EDGES) if neg_median <= m),
- "hour_i": LAT_EDGES.index(60),
- "lat_max": human_duration(lat_max_min),
-}
+ rug_dom = (DOMAIN[1] - timedelta(days=RUG_DAYS - 1), DOMAIN[1])
+ rug_act, rug_best_n, rug_run = windowed_run(rug_dom)
+
+
+ # ---------------------------------------------------------------- write ----
+ asof = now.strftime("%Y-%m-%d")
+ current_year = years[-1]
+
+ # Facts are language-neutral (bare numbers, dates, proper nouns) so one
+ # derivation serves both READMEs; sentence framing and links live in the
+ # markdown, per language. A word in any natural language does not belong here —
+ # see archived_names, where the extension is derived and the interpretation
+ # ("graduated, not failed") stays hand-written.
+ facts = {
+ "asof": asof,
+ "cur_year": current_year,
+ "cur_total": f"{values[-1]:,}",
+ "commits_total": f"{commits_total:,}",
+ "src_repos": src_repos,
+ "streak": streak,
+ "conv_pct": f"{conv / commits_total * 100:.1f}%",
+ "peak_h": f"{max(hours, key=lambda h: hours[h]):02d}:00",
+ "peak_n": f"{max(hours.values()):,}",
+ "peak_pct": f"{max(hours.values()) / commits_total * 100:.1f}%",
+ "peak_x": f"{max(hours.values()) / (commits_total / 24):.2f}×",
+ "pub_prs": f"{pub_prs:,}",
+ "neg_pr": f"{neg_pr:,}",
+ "neg_median": f"{neg_median:.0f}",
+ "pct_hour": f"{pct_hour:.0f}%",
+ "own_stars": own_stars,
+ "acc_stars": acc_stars,
+ "total_stars": total_stars,
+ "rel_total": rel_total,
+ "rel_repos": rel_repos,
+ "ext_prs": ext_prs,
+ "ext_merged": ext_merged,
+ "ext_dify": ext_dify,
+ "archived_n": len(archived_names),
+ "archived_names": ", ".join(archived_names),
+ "ext_first": min(it["created_at"] for it in ext_items)[:10],
+ "ext_last": max(it["created_at"] for it in ext_items)[:10],
+ "pc_cell": "%s %02d:00" % (("Mon", "Tue", "Wed", "Thu", "Fri", "Sat", "Sun")[peak_cell[0]], peak_cell[1]),
+ "pc_val": weekhours[peak_cell],
+ "pc_empty": sum(1 for wd in range(7) for h in range(24) if not weekhours.get((wd, h))),
+ "wknd_pct": f"{wknd / commits_total * 100:.1f}%",
+ "win_from": str(DOMAIN[0]),
+ "win_to": str(DOMAIN[1]),
+ "win_days": WIN_DAYS,
+ "win_months": round(WIN_DAYS / 30.44),
+ "p90": human_duration(p90_lat),
+ "lat_max": human_duration(lat_max_min),
+ "pr_closed": pr_closed,
+ "pr_unmerged": pr_unmerged,
+ "top_type": types_sorted[0][0],
+ "top_type_pct": f"{types_sorted[0][1] / commits_total * 100:.1f}%",
+ "nonconf_pct": f"{(commits_total - conv) / commits_total * 100:.1f}%",
+ "nonconf_n": commits_total - conv,
+ "lang_top": lang_src.most_common(1)[0][0],
+ "lang_top_pct": f"{lang_src.most_common(1)[0][1] / sum(lang_src.values()) * 100:.1f}%",
+ "lang_naive": lang_all.most_common(1)[0][0],
+ "lang_naive_pct": f"{lang_all.most_common(1)[0][1] / sum(lang_all.values()) * 100:.1f}%",
+ "rel_last_name": rel_last[0],
+ "rel_last_tag": rel_last[1],
+ "streak_from": str(best_start),
+ "streak_to": str(best_end),
+ "rug_streak": rug_best_n,
+ "rug_streak_from": str(rug_run[0]),
+ "rug_streak_to": str(rug_run[1]),
+ "active_days": len(day_counts),
+ "active_pct": f"{len(day_counts) / WIN_DAYS * 100:.0f}%",
+ "wd_days": wd_days,
+ "we_days": we_days,
+ "we_peak_h": f"{we_peak:02d}:00",
+ "neg_commits": f"{len(repo_commits.get(TRUNK, ())):,}",
+ "rel_cp": rel_counts.get("coding-proxy", 0),
+ "rel_hg": rel_counts.get("hyper-git", 0),
+ "rel_gmab": rel_counts.get("give-me-a-break", 0),
+ }
-def windowed_run(dom):
- """Longest streak + activity counts INSIDE the rug's rolling window, so the
- figure's bracket and its alt text can never disagree with its own axis.
- Same counting semantics as the all-time loop above: the first active day
- is itself a run of length 1."""
- wd_days = [d for d in sorted(day_counts) if dom[0] <= d <= dom[1]]
- if not wd_days:
- die("no authored commits inside the rug window — streak figure undefined")
- best, b_start, b_end, run = 1, wd_days[0], wd_days[0], 1
- for prev, cur in zip(wd_days, wd_days[1:]):
- run = run + 1 if (cur - prev).days == 1 else 1
- if run > best:
- best, b_end = run, cur
- b_start = cur - timedelta(days=run - 1)
- return len(wd_days), best, (b_start, b_end)
+ # Closure between the declared contract and the actual derivation: lint audits
+ # markers against FACT_KEYS without a network call, so the two must agree.
+ if set(facts) != set(FACT_KEYS):
+ die(f"FACT_KEYS closure broken: declared-not-derived "
+ f"{sorted(FACT_KEYS - set(facts))}, derived-not-declared "
+ f"{sorted(set(facts) - set(FACT_KEYS))} — refusing")
+
+ ground_counts = {k: len(v) for k, v in repo_commits.items()}
+ types_under_one_pct = [n for n, c in types_sorted if c / commits_total < 0.01]
+ # In-frame text is English-only: one SVG serves both READMEs (the zh file
+ # references the same assets by absolute URL). Per-language phrasing lives in
+ # the alt text, which is derived per README.
+ under_one_pct_note = ("%d types under one percent each: %s — folded here, not drawn"
+ % (len(types_under_one_pct), ", ".join(types_under_one_pct))) if types_under_one_pct else "no types under one percent"
+ ALTS = {
+ "growth": {f: growth_alt(f, values, years) for f in README_FILES},
+ "rhythm": {f: rhythm_alt(f, hours) for f in README_FILES},
+ "ground": {f: ground_alt(f, ground_counts, rel_counts, archived_names)
+ for f in README_FILES},
+ "punchcard": {f: punchcard_alt(f, weekhours, DOMAIN, wknd, wd_days, we_days)
+ for f in README_FILES},
+ "surplus": {f: surplus_alt(f, wd_hour, we_hour, wd_days, we_days, DOMAIN)
+ for f in README_FILES},
+ "accrual": {f: accrual_alt(f, monthly, DOMAIN, grad_events, commits_total)
+ for f in README_FILES},
+ "lifecycles": {f: lifecycles_alt(f, spans, DOMAIN) for f in README_FILES},
+ "cadence": {f: cadence_alt(f, rel_lists, DOMAIN, len(repo_commits.get(TRUNK, ())))
+ for f in README_FILES},
+ "streak": {f: streak_alt(f, rug_act, RUG_DAYS - rug_act, rug_run, rug_dom, RUG_DAYS)
+ for f in README_FILES},
+ "latency": {f: latency_alt(f, lat_buckets, lat_stats, pct_hour)
+ for f in README_FILES},
+ "grammar": {f: grammar_alt(f, types_sorted, commits_total - conv, commits_total)
+ for f in README_FILES},
+ "tongues": {f: tongues_alt(f, lang_all, lang_src, GEN_SITE, zero_byte_repos)
+ for f in README_FILES},
+ "upstream": {f: upstream_alt(f, ext_items, pub_prs) for f in README_FILES},
+ }
+ if set(ALTS) != set(FIG_SPEC):
+ die(f"alt text missing for figure(s) {sorted(set(FIG_SPEC) - set(ALTS))} — refusing")
+
+ figures = {
+ FIG_SPEC["growth"][0]: render_growth(values, years, asof, ALTS["growth"][EN]),
+ FIG_SPEC["rhythm"][0]: render_rhythm(hours, asof, ALTS["rhythm"][EN]),
+ FIG_SPEC["ground"][0]: render_ground(ground_counts, rel_counts, asof, ALTS["ground"][EN]),
+ FIG_SPEC["punchcard"][0]: render_punchcard(weekhours, DOMAIN, asof, ALTS["punchcard"][EN]),
+ FIG_SPEC["surplus"][0]: render_surplus(wd_hour, we_hour, wd_days, we_days, DOMAIN, asof,
+ ALTS["surplus"][EN]),
+ FIG_SPEC["accrual"][0]: render_accrual(monthly, grad_events, DOMAIN, asof, ALTS["accrual"][EN]),
+ FIG_SPEC["lifecycles"][0]: render_lifecycles(spans, DOMAIN, asof, ALTS["lifecycles"][EN]),
+ FIG_SPEC["cadence"][0]: render_cadence(rel_lists, DOMAIN, asof, ALTS["cadence"][EN]),
+ FIG_SPEC["streak"][0]: render_streak(day_counts, rug_run, rug_dom, asof,
+ ALTS["streak"][EN]),
+ FIG_SPEC["latency"][0]: render_latency(lat_buckets, ecdf_points(), lat_stats, asof,
+ ALTS["latency"][EN]),
+ FIG_SPEC["grammar"][0]: render_grammar(types_sorted, commits_total - conv, commits_total,
+ under_one_pct_note, asof,
+ ALTS["grammar"][EN]),
+ FIG_SPEC["tongues"][0]: render_tongues(lang_all, lang_src, GEN_SITE, zero_byte_repos,
+ asof, ALTS["tongues"][EN]),
+ FIG_SPEC["upstream"][0]: render_upstream(ext_items, pub_prs, asof, ALTS["upstream"][EN]),
+ }
+ report = (
+ f"OK growth(latest {values[-1]:,}) rhythm({commits_total:,} commits/{src_repos} repos, "
+ f"peak {facts['peak_h']}) ground({rel_total} releases/{rel_repos} repos with releases) "
+ f"pub_prs={pub_prs:,} ext={ext_prs} merged={ext_merged} dify={ext_dify} "
+ f"own_stars={own_stars} streak={streak}d median={neg_median:.0f}min "
+ f"archived={archived_names}"
+ )
+ return {
+ "facts": facts, "alts": ALTS, "figures": figures,
+ "values": values, "current_year": current_year, "report": report,
+ }
-RUG_DAYS = 400
-rug_dom = (DOMAIN[1] - timedelta(days=RUG_DAYS - 1), DOMAIN[1])
-rug_act, rug_best_n, rug_run = windowed_run(rug_dom)
-
-
-# ---------------------------------------------------------------- write ----
-asof = now.strftime("%Y-%m-%d")
-current_year = years[-1]
-
-# Facts are language-neutral (bare numbers, dates, proper nouns) so one
-# derivation serves both READMEs; sentence framing and links live in the
-# markdown, per language. A word in any natural language does not belong here —
-# see archived_names, where the extension is derived and the interpretation
-# ("graduated, not failed") stays hand-written.
-facts = {
- "asof": asof,
- "cur_year": current_year,
- "cur_total": f"{values[-1]:,}",
- "commits_total": f"{commits_total:,}",
- "src_repos": src_repos,
- "streak": streak,
- "conv_pct": f"{conv / commits_total * 100:.1f}%",
- "peak_h": f"{max(hours, key=lambda h: hours[h]):02d}:00",
- "peak_n": f"{max(hours.values()):,}",
- "peak_pct": f"{max(hours.values()) / commits_total * 100:.1f}%",
- "peak_x": f"{max(hours.values()) / (commits_total / 24):.2f}×",
- "pub_prs": f"{pub_prs:,}",
- "neg_pr": f"{neg_pr:,}",
- "neg_median": f"{neg_median:.0f}",
- "pct_hour": f"{pct_hour:.0f}%",
- "own_stars": own_stars,
- "acc_stars": acc_stars,
- "total_stars": total_stars,
- "rel_total": rel_total,
- "rel_repos": rel_repos,
- "ext_prs": ext_prs,
- "ext_merged": ext_merged,
- "ext_dify": ext_dify,
- "archived_n": len(archived_names),
- "archived_names": ", ".join(archived_names),
- "ext_first": min(it["created_at"] for it in ext_items)[:10],
- "ext_last": max(it["created_at"] for it in ext_items)[:10],
- "pc_cell": "%s %02d:00" % (("Mon", "Tue", "Wed", "Thu", "Fri", "Sat", "Sun")[peak_cell[0]], peak_cell[1]),
- "pc_val": weekhours[peak_cell],
- "pc_empty": sum(1 for wd in range(7) for h in range(24) if not weekhours.get((wd, h))),
- "wknd_pct": f"{wknd / commits_total * 100:.1f}%",
- "win_from": str(DOMAIN[0]),
- "win_to": str(DOMAIN[1]),
- "win_days": WIN_DAYS,
- "win_months": round(WIN_DAYS / 30.44),
- "p90": human_duration(p90_lat),
- "lat_max": human_duration(lat_max_min),
- "pr_closed": pr_closed,
- "pr_unmerged": pr_unmerged,
- "top_type": types_sorted[0][0],
- "top_type_pct": f"{types_sorted[0][1] / commits_total * 100:.1f}%",
- "nonconf_pct": f"{(commits_total - conv) / commits_total * 100:.1f}%",
- "nonconf_n": commits_total - conv,
- "lang_top": lang_src.most_common(1)[0][0],
- "lang_top_pct": f"{lang_src.most_common(1)[0][1] / sum(lang_src.values()) * 100:.1f}%",
- "lang_naive": lang_all.most_common(1)[0][0],
- "lang_naive_pct": f"{lang_all.most_common(1)[0][1] / sum(lang_all.values()) * 100:.1f}%",
- "rel_last_name": rel_last[0],
- "rel_last_tag": rel_last[1],
- "streak_from": str(best_start),
- "streak_to": str(best_end),
- "rug_streak": rug_best_n,
- "rug_streak_from": str(rug_run[0]),
- "rug_streak_to": str(rug_run[1]),
- "active_days": len(day_counts),
- "active_pct": f"{len(day_counts) / WIN_DAYS * 100:.0f}%",
- "wd_days": wd_days,
- "we_days": we_days,
- "we_peak_h": f"{we_peak:02d}:00",
- "neg_commits": f"{len(repo_commits.get(TRUNK, ())):,}",
- "rel_cp": rel_counts.get("coding-proxy", 0),
- "rel_hg": rel_counts.get("hyper-git", 0),
- "rel_gmab": rel_counts.get("give-me-a-break", 0),
-}
+def main():
+ MODE = "write"
+ for _arg in sys.argv[1:]:
+ if _arg in ("--lint", "--check"):
+ MODE = _arg[2:]
+ else:
+ die(f"unknown argument {_arg!r} — expected --lint or --check")
-# Closure between the declared contract and the actual derivation: lint audits
-# markers against FACT_KEYS without a network call, so the two must agree.
-if set(facts) != set(FACT_KEYS):
- die(f"FACT_KEYS closure broken: declared-not-derived "
- f"{sorted(FACT_KEYS - set(facts))}, derived-not-declared "
- f"{sorted(set(facts) - set(FACT_KEYS))} — refusing")
-
-ground_counts = {k: len(v) for k, v in repo_commits.items()}
-sub1pct = [n for n, c in types_sorted if c / commits_total < 0.01]
-# In-frame text is English-only: one SVG serves both READMEs (the zh file
-# references the same assets by absolute URL). Per-language phrasing lives in
-# the alt text, which is derived per README.
-sub1_txt = ("%d types under one percent each: %s — folded here, not drawn"
- % (len(sub1pct), ", ".join(sub1pct))) if sub1pct else "no types under one percent"
-ALTS = {
- "growth": {f: growth_alt(f, values, years) for f in README_FILES},
- "rhythm": {f: rhythm_alt(f, hours) for f in README_FILES},
- "ground": {f: ground_alt(f, ground_counts, rel_counts, archived_names)
- for f in README_FILES},
- "punchcard": {f: punchcard_alt(f, weekhours, DOMAIN, wknd, wd_days, we_days)
- for f in README_FILES},
- "surplus": {f: surplus_alt(f, wd_hour, we_hour, wd_days, we_days, DOMAIN)
- for f in README_FILES},
- "accrual": {f: accrual_alt(f, monthly, DOMAIN, grad_events, commits_total)
- for f in README_FILES},
- "lifecycles": {f: lifecycles_alt(f, spans, DOMAIN) for f in README_FILES},
- "cadence": {f: cadence_alt(f, rel_lists, DOMAIN, len(repo_commits.get(TRUNK, ())))
- for f in README_FILES},
- "streak": {f: streak_alt(f, rug_act, RUG_DAYS - rug_act, rug_run, rug_dom, RUG_DAYS)
- for f in README_FILES},
- "latency": {f: latency_alt(f, lat_buckets, lat_stats, pct_hour)
- for f in README_FILES},
- "grammar": {f: grammar_alt(f, types_sorted, commits_total - conv, commits_total)
- for f in README_FILES},
- "tongues": {f: tongues_alt(f, lang_all, lang_src, GEN_SITE, zero_byte_repos)
- for f in README_FILES},
- "upstream": {f: upstream_alt(f, ext_items, pub_prs) for f in README_FILES},
-}
-if set(ALTS) != set(FIG_SPEC):
- die(f"alt text missing for figure(s) {sorted(set(FIG_SPEC) - set(ALTS))} — refusing")
-
-figures = {
- FIG_SPEC["growth"][0]: render_growth(values, years, asof, ALTS["growth"][EN]),
- FIG_SPEC["rhythm"][0]: render_rhythm(hours, asof, ALTS["rhythm"][EN]),
- FIG_SPEC["ground"][0]: render_ground(ground_counts, rel_counts, asof, ALTS["ground"][EN]),
- FIG_SPEC["punchcard"][0]: render_punchcard(weekhours, DOMAIN, asof, ALTS["punchcard"][EN]),
- FIG_SPEC["surplus"][0]: render_surplus(wd_hour, we_hour, wd_days, we_days, DOMAIN, asof,
- ALTS["surplus"][EN]),
- FIG_SPEC["accrual"][0]: render_accrual(monthly, grad_events, DOMAIN, asof, ALTS["accrual"][EN]),
- FIG_SPEC["lifecycles"][0]: render_lifecycles(spans, DOMAIN, asof, ALTS["lifecycles"][EN]),
- FIG_SPEC["cadence"][0]: render_cadence(rel_lists, DOMAIN, asof, ALTS["cadence"][EN]),
- FIG_SPEC["streak"][0]: render_streak(day_counts, rug_run, rug_dom, asof,
- ALTS["streak"][EN]),
- FIG_SPEC["latency"][0]: render_latency(lat_buckets, ecdf_points(), lat_stats, asof,
- ALTS["latency"][EN]),
- FIG_SPEC["grammar"][0]: render_grammar(types_sorted, commits_total - conv, commits_total,
- sub1_txt, asof,
- ALTS["grammar"][EN]),
- FIG_SPEC["tongues"][0]: render_tongues(lang_all, lang_src, GEN_SITE, zero_byte_repos,
- asof, ALTS["tongues"][EN]),
- FIG_SPEC["upstream"][0]: render_upstream(ext_items, pub_prs, asof, ALTS["upstream"][EN]),
-}
-texts = read_readmes()
-orders = {f: scan_markers(t, f) for f, t in texts.items()}
-audit_parity(orders)
-audit_assets()
-
-outputs = {}
-for f, text in texts.items():
- # Monotonicity guard, year-flip aware: the annual total can only decrease
- # when the README still refers to the *current* year. In January the
- # headline legitimately resets to a small partial-year number. The README is
- # the pipeline's only state store, which is why this reads the old value
- # back out of the markdown rather than from a cache.
- mc = re.search(r"(\d{4})", text)
- if mc and int(mc.group(1)) == current_year:
- m = re.search(r"(.*?)", text, re.S)
- if m:
- nums = re.findall(r"\d[\d,]*", m.group(1))
- if nums and int(nums[0].replace(",", "")) > values[-1]:
- die(f"current-year total decreased ({nums[0]} -> {values[-1]}) — "
- "parse likely broken")
- alts = {k: ALTS[k][f] for k in ALTS}
- once = substitute(text, f, facts, alts)
- if substitute(once, f, facts, alts) != once:
- die(f"{f}: substitution is not idempotent — anchors are being consumed, "
- "the next run would find nothing, refusing")
- if scan_markers(once, f) != orders[f]:
- die(f"{f}: substitution changed the marker sequence — refusing")
- outputs[f] = once
-
-# Validate every rendered figure BEFORE anything is written to disk. Every
-# figure's byte count is structurally bounded (fixed cells, fixed lanes, or a
-# rolling window), so the flat 8,192 B ceiling stays binding for all of them.
-for name, src in figures.items():
- n = assert_svg_sane(src, name)
- print(f" {name}: {n}B PASS")
-
-if MODE == "check":
+ if MODE == "lint":
+ _orders = {f: scan_markers(t, f) for f, t in read_readmes().items()}
+ audit_parity(_orders)
+ audit_assets()
+ _d = sum(1 for k, _ in _orders[EN] if k == "DATA")
+ _g = sum(1 for k, _ in _orders[EN] if k == "FIG")
+ print(f"OK lint: {_d} DATA + {_g} FIG regions, identical set and order in "
+ f"both READMEs; assets/ clean")
+ sys.exit(0)
+
+
+ out = refresh()
+ texts = read_readmes()
+ orders = {f: scan_markers(t, f) for f, t in texts.items()}
+ audit_parity(orders)
+ audit_assets()
+
+ outputs = {}
+ for f, text in texts.items():
+ # Monotonicity guard, year-flip aware: the annual total can only decrease
+ # when the README still refers to the *current* year. In January the
+ # headline legitimately resets to a small partial-year number. The README is
+ # the pipeline's only state store, which is why this reads the old value
+ # back out of the markdown rather than from a cache.
+ mc = re.search(r"(\d{4})", text)
+ if mc and int(mc.group(1)) == out["current_year"]:
+ m = re.search(r"(.*?)", text, re.S)
+ if m:
+ nums = re.findall(r"\d[\d,]*", m.group(1))
+ if nums and int(nums[0].replace(",", "")) > out["values"][-1]:
+ die(f"current-year total decreased ({nums[0]} -> {out['values'][-1]}) — "
+ "parse likely broken")
+ alts = {k: a[f] for k, a in out["alts"].items()}
+ once = substitute(text, f, out["facts"], alts)
+ if substitute(once, f, out["facts"], alts) != once:
+ die(f"{f}: substitution is not idempotent — anchors are being consumed, "
+ "the next run would find nothing, refusing")
+ if scan_markers(once, f) != orders[f]:
+ die(f"{f}: substitution changed the marker sequence — refusing")
+ outputs[f] = once
+
+ # Validate every rendered figure BEFORE anything is written to disk. Every
+ # figure's byte count is structurally bounded (fixed cells, fixed lanes, or a
+ # rolling window), so the flat 8,192 B ceiling stays binding for all of them.
+ for name, src in out["figures"].items():
+ n = assert_svg_sane(src, name)
+ print(f" {name}: {n}B PASS")
+
+ if MODE == "check":
+ for f, text in outputs.items():
+ on_disk = texts[f]
+ if text != on_disk:
+ diff = "".join(difflib.unified_diff(
+ on_disk.splitlines(keepends=True), text.splitlines(keepends=True),
+ fromfile=f"{f} (on disk)", tofile=f"{f} (would write)"))
+ print(diff, end="")
+ for name, src in out["figures"].items():
+ p = pathlib.Path("assets") / name
+ if p.is_file() and p.read_text(encoding="utf-8") != src:
+ print(f"--- a/assets/{name} (on disk)\n+++ b/assets/{name} (would write)")
+ print("OK check: all guards passed, nothing written "
+ f"(re-run without --check to write)")
+ sys.exit(0)
+
+ # All guards passed — write everything.
+ pathlib.Path("assets").mkdir(exist_ok=True)
+ for name, src in out["figures"].items():
+ with open(pathlib.Path("assets") / name, "w", encoding="utf-8") as fh:
+ fh.write(src)
for f, text in outputs.items():
- on_disk = texts[f]
- if text != on_disk:
- diff = "".join(difflib.unified_diff(
- on_disk.splitlines(keepends=True), text.splitlines(keepends=True),
- fromfile=f"{f} (on disk)", tofile=f"{f} (would write)"))
- print(diff, end="")
- for name, src in figures.items():
- p = pathlib.Path("assets") / name
- if p.is_file() and p.read_text(encoding="utf-8") != src:
- print(f"--- a/assets/{name} (on disk)\n+++ b/assets/{name} (would write)")
- print("OK check: all guards passed, nothing written "
- f"(re-run without --check to write)")
- sys.exit(0)
-
-# All guards passed — write everything.
-pathlib.Path("assets").mkdir(exist_ok=True)
-for name, src in figures.items():
- with open(pathlib.Path("assets") / name, "w", encoding="utf-8") as fh:
- fh.write(src)
-for f, text in outputs.items():
- with open(f, "w", encoding="utf-8") as fh:
- fh.write(text)
-
-print(
- f"OK growth(latest {values[-1]:,}) rhythm({commits_total:,} commits/{src_repos} repos, "
- f"peak {facts['peak_h']}) ground({rel_total} releases/{rel_repos} repos with releases) "
- f"pub_prs={pub_prs:,} ext={ext_prs} merged={ext_merged} dify={ext_dify} "
- f"own_stars={own_stars} streak={streak}d median={neg_median:.0f}min "
- f"archived={archived_names}"
-)
+ with open(f, "w", encoding="utf-8") as fh:
+ fh.write(text)
+
+ print(out["report"])
+
+if __name__ == "__main__":
+ main()
diff --git a/tests/__init__.py b/tests/__init__.py
new file mode 100644
index 0000000..e69de29
diff --git a/tests/_bps.py b/tests/_bps.py
new file mode 100644
index 0000000..79ffe5f
--- /dev/null
+++ b/tests/_bps.py
@@ -0,0 +1,56 @@
+"""Test loader: expose scripts/build_profile_svgs.py symbols WITHOUT executing
+its module-level network collection.
+
+Mechanism (characterization only — no copies, no mocks): parse the module's
+real source on every run and exec only (a) imports, (b) every function def,
+(c) module constants on a name allowlist. Nodes are selected by NAME, not line
+number, so the loader survives refactors that move code within the file; the
+collection (inside refresh()) and orchestration (main()) are simply never
+executed. If the module later grows an import-safe layout, tests may switch to
+a plain import — assertions must not change either way (see Gate 1)."""
+import ast
+import pathlib
+
+ROOT = pathlib.Path(__file__).resolve().parents[1]
+MODULE_PATH = ROOT / "scripts" / "build_profile_svgs.py"
+
+# Module-level constants the pure functions close over (sections A/C/E).
+_CONSTANTS = frozenset({
+ "USER", "TZ", "EN", "ZH", "README_FILES", "ACC_REPO", "TRUNK",
+ "MIN_SOURCE_COMMITS", "FIRST_YEAR", "RHYTHM_ORIGIN", "DIFY_OWNER",
+ "CONVENTIONAL", "FACT_KEYS", "FIG_SPEC", "SRC_PREFIX", "MARKER",
+ "FONT", "LIGHT", "DARK", "_GLYPHS", "GLYPH_W", "FONT_SLACK",
+ "BANNED", "KEYFRAME", "TEXT_EL", "FILL_ONLY", "STROKED",
+ "LAT_EDGES", "LAT_LABELS", "RUG_DAYS", "GEN_SITE", "HOUR_ORDER",
+})
+
+
+def _target_names(node):
+ out = set()
+ for t in node.targets:
+ if isinstance(t, ast.Name):
+ out.add(t.id)
+ elif isinstance(t, ast.Tuple):
+ out |= {e.id for e in t.elts if isinstance(e, ast.Name)}
+ return out
+
+
+def _selected(tree):
+ for node in tree.body:
+ if isinstance(node, (ast.Import, ast.ImportFrom, ast.Try)):
+ yield node
+ elif isinstance(node, ast.FunctionDef):
+ yield node
+ elif isinstance(node, ast.Assign) and _target_names(node) <= _CONSTANTS:
+ yield node
+
+
+def load():
+ tree = ast.parse(MODULE_PATH.read_text(encoding="utf-8"))
+ module = ast.Module(body=list(_selected(tree)), type_ignores=[])
+ ns = {"__name__": "build_profile_svgs_under_test"}
+ exec(compile(module, str(MODULE_PATH), "exec"), ns)
+ return ns
+
+
+NS = load()
diff --git a/tests/golden/accrual_synthetic.svg b/tests/golden/accrual_synthetic.svg
new file mode 100644
index 0000000..9a30de4
--- /dev/null
+++ b/tests/golden/accrual_synthetic.svg
@@ -0,0 +1,33 @@
+
+
+graduated
+hyper-git
+negentropy
+total 35
+2026-03
+cumulative authored commits per repo · monthly · 2026-01-05 → 2026-03-01 · not the eleven years above
+as of 2026-09-05
+
diff --git a/tests/golden/cadence_synthetic.svg b/tests/golden/cadence_synthetic.svg
new file mode 100644
index 0000000..820ea40
--- /dev/null
+++ b/tests/golden/cadence_synthetic.svg
@@ -0,0 +1,35 @@
+
+
+v0.1.0
+v0.2.0
+coding-proxy · 2
+v0.0.1
+negentropy · 1
+2026-03
+releases on the commit timeline · hollow = pre-release · counts at left
+negentropy ships as merged PRs, not tags — it is a deployed service, not a distributed package
+as of 2026-09-05
+
diff --git a/tests/golden/grammar_synthetic.svg b/tests/golden/grammar_synthetic.svg
new file mode 100644
index 0000000..c974242
--- /dev/null
+++ b/tests/golden/grammar_synthetic.svg
@@ -0,0 +1,32 @@
+
+
+fix 827
+docs 725
+feat 697
+test 6
+none-parse 996
+commit subjects by Conventional Commits type · one cell = one percent of 4,349
+open cells do not parse as Conventional Commits · 19.0
+as of 2026-09-05
+
diff --git a/tests/golden/ground_synthetic.svg b/tests/golden/ground_synthetic.svg
new file mode 100644
index 0000000..b49461b
--- /dev/null
+++ b/tests/golden/ground_synthetic.svg
@@ -0,0 +1,29 @@
+
+
+repository
+commits
+releases
+negentropy
+40
+0
+coding-proxy
+12
+3
+hyper-git
+7
+1
+59 commits · 4 releases · 3 source repositories · negentropy 67.8%
+as of 2026-09-05
+
diff --git a/tests/golden/growth_synthetic.svg b/tests/golden/growth_synthetic.svg
new file mode 100644
index 0000000..a05361c
--- /dev/null
+++ b/tests/golden/growth_synthetic.svg
@@ -0,0 +1,47 @@
+
+
+contributions per year · square-root scale
+1
+0
+0
+13
+129
+198
+676
+589 ↓
+1,181
+3,193
+9,313
+2016 2017 2018 2019 2020 2021 2022 2023 2024 2025 2026
+as of 2026-09-05
+
diff --git a/tests/golden/latency_synthetic.svg b/tests/golden/latency_synthetic.svg
new file mode 100644
index 0000000..a5559a4
--- /dev/null
+++ b/tests/golden/latency_synthetic.svg
@@ -0,0 +1,56 @@
+
+
+median 6 min
+1 h
+5
+<1m
+2
+1-2
+3
+2-5
+4
+5-15
+3
+15-60m
+2
+1-4h
+1
+4-24h
+0
+>24h
+100%
+0%
+merged-PR lifetime in negentropy · 20 merged, 2 closed-unmerged excluded
+solo self-merge: unit size, not review speed · log buckets, tail compressed by design — longest was 11.9 d
+as of 2026-09-05
+
diff --git a/tests/golden/lifecycles_synthetic.svg b/tests/golden/lifecycles_synthetic.svg
new file mode 100644
index 0000000..0ff1f07
--- /dev/null
+++ b/tests/golden/lifecycles_synthetic.svg
@@ -0,0 +1,36 @@
+
+
+old-wing
+2025-06 → 2026-02
+negentropy
+2026-01 → 2026-03
+2025-06
+2025-08
+2025-10
+2025-12
+2026-02
+repository lifespans, creation to last push · ends are last push, not archive dates
+■ graduated (archived) · bars in blue are live · deleted repos are invisible at public caliber
+as of 2026-09-05
+
diff --git a/tests/golden/punchcard_synthetic.svg b/tests/golden/punchcard_synthetic.svg
new file mode 100644
index 0000000..7b0f2b6
--- /dev/null
+++ b/tests/golden/punchcard_synthetic.svg
@@ -0,0 +1,27 @@
+
+
+Mon Tue Wed Thu Fri Sat Sun
+04 08 12 16 20 00
+commits by weekday × hour · cell area ∝ count · axis 04→03 · 2026-01-05 → 2026-03-01
+as of 2026-09-05
+
diff --git a/tests/golden/rhythm_synthetic.svg b/tests/golden/rhythm_synthetic.svg
new file mode 100644
index 0000000..aeec4a2
--- /dev/null
+++ b/tests/golden/rhythm_synthetic.svg
@@ -0,0 +1,50 @@
+
+
+open-source commits by hour · Asia/Shanghai · axis 04→03
+400
+04 08 12 16 20 00
+as of 2026-09-05
+
diff --git a/tests/golden/streak_synthetic.svg b/tests/golden/streak_synthetic.svg
new file mode 100644
index 0000000..d3ec48e
--- /dev/null
+++ b/tests/golden/streak_synthetic.svg
@@ -0,0 +1,31 @@
+
+
+10 days, 2026-06-10 → 2026-06-19
+2026-06
+one tick per day, latest 30 · height ∝ √commits · authored commits in source repos, not the GitHub calendar
+as of 2026-09-05
+
diff --git a/tests/golden/surplus_synthetic.svg b/tests/golden/surplus_synthetic.svg
new file mode 100644
index 0000000..351243d
--- /dev/null
+++ b/tests/golden/surplus_synthetic.svg
@@ -0,0 +1,28 @@
+
+
+commits per day, weekday vs weekend · axis 04→03 · 2026-01-05 → 2026-03-01
+per-day rates: 90 commits ÷ 40 weekdays · 100 commits ÷ 12 weekend days
+6.7/d
+as of 2026-09-05
+04 08 12 16 20 00
+
diff --git a/tests/golden/tongues_synthetic.svg b/tests/golden/tongues_synthetic.svg
new file mode 100644
index 0000000..5d33b51
--- /dev/null
+++ b/tests/golden/tongues_synthetic.svg
@@ -0,0 +1,28 @@
+
+
+TypeScript 10.3%
+Python 25.6%
+HTML 64.1%
+HTML 1.8%
+TypeScript 28.1%
+Python 70.2%
+as GitHub counts it
+excluding threefish-ai.github.io
+others 0.0% / 0.0% · bytes measure committed source size, not authorship or effort · no zero-byte source repos
+language byte share under two conditions · threefish-ai.github.io is generated static-site output
+as of 2026-09-05
+
diff --git a/tests/golden/upstream_synthetic.svg b/tests/golden/upstream_synthetic.svg
new file mode 100644
index 0000000..f410729
--- /dev/null
+++ b/tests/golden/upstream_synthetic.svg
@@ -0,0 +1,22 @@
+
+
+langgenius/dify#5631 · merged · 2026-01-09
+foo/bar#124 · closed unmerged · 2026-02-01
+
+2 external public PRs — 0.4% of 500 public PRs; the rest are my own repositories
+pull requests into code I do not own · hollow = closed unmerged · blue = Dify ecosystem
+as of 2026-09-05
+
diff --git a/tests/test_cli.py b/tests/test_cli.py
new file mode 100644
index 0000000..428b941
--- /dev/null
+++ b/tests/test_cli.py
@@ -0,0 +1,31 @@
+"""Characterization of the CLI boundary: --lint is the exact audit the PR CI
+job runs (zero network), and an unknown argument must die without writing."""
+import subprocess
+import sys
+import unittest
+
+from tests._bps import ROOT
+
+
+class TestCliLint(unittest.TestCase):
+ def test_lint_passes_with_stable_output_format(self):
+ r = subprocess.run(
+ [sys.executable, "scripts/build_profile_svgs.py", "--lint"],
+ cwd=ROOT, capture_output=True, text=True, timeout=120)
+ self.assertEqual(r.returncode, 0, r.stderr)
+ self.assertTrue(r.stdout.startswith("OK lint: "), r.stdout)
+ self.assertIn("DATA + ", r.stdout)
+ self.assertIn(
+ "identical set and order in both READMEs; assets/ clean",
+ r.stdout)
+
+ def test_unknown_argument_dies(self):
+ r = subprocess.run(
+ [sys.executable, "scripts/build_profile_svgs.py", "--bogus"],
+ cwd=ROOT, capture_output=True, text=True, timeout=120)
+ self.assertEqual(r.returncode, 1)
+ self.assertTrue(r.stderr.startswith("ABORT:"), r.stderr)
+
+
+if __name__ == "__main__":
+ unittest.main()
diff --git a/tests/test_contract.py b/tests/test_contract.py
new file mode 100644
index 0000000..3229a42
--- /dev/null
+++ b/tests/test_contract.py
@@ -0,0 +1,181 @@
+"""Characterization of the marker/parity/substitution contract (Section A).
+
+Locks today's behavior of scan_markers / audit_parity / audit_assets /
+substitute — the functions the monthly cron and the PR lint job both stand on —
+plus a real-file Golden Master over both READMEs and assets/."""
+import contextlib
+import io
+import os
+import pathlib
+import re
+import tempfile
+import unittest
+
+from tests._bps import NS, ROOT
+
+scan_markers = NS["scan_markers"]
+audit_parity = NS["audit_parity"]
+audit_assets = NS["audit_assets"]
+substitute = NS["substitute"]
+FIG_SPEC = NS["FIG_SPEC"]
+EN, ZH = NS["EN"], NS["ZH"]
+
+# A minimal README skeleton exercising both marker kinds. Facts/alt stubs are
+# intentionally unlike anything real so a byte-exact diff proves replacement.
+_DOC = (
+ "stale body\n"
+ "total old now\n"
+ "2020\n"
+)
+_FACTS = {"cur_total": "9,313", "cur_year": "2026"}
+_ALTS = {"growth": 'says "1, 0" & more'}
+_STUB_FACTS = {k: "2026" if k == "cur_year" else "0" for k in NS["FACT_KEYS"]}
+_STUB_ALTS = {k: "stub alt" for k in FIG_SPEC}
+
+
+def _die_message(case, call):
+ """Run `call`, returning (exit_code, stderr_text) of the expected die()."""
+ err = io.StringIO()
+ with case.assertRaises(SystemExit) as cm, contextlib.redirect_stderr(err):
+ call()
+ return cm.exception.code, err.getvalue()
+
+
+class TestScanMarkers(unittest.TestCase):
+ def test_wellformed_order(self):
+ text = _DOC + "x y"
+ self.assertEqual(
+ scan_markers(text, EN),
+ [("FIG", "growth"), ("DATA", "cur_total"), ("DATA", "cur_year"),
+ ("FIG", "streak")])
+
+ def test_unknown_key_dies(self):
+ code, err = _die_message(self, lambda: scan_markers(
+ "1", EN))
+ self.assertEqual(code, 1)
+ self.assertIn("not derivable", err)
+
+ def test_nested_region_dies(self):
+ code, err = _die_message(self, lambda: scan_markers(
+ ""
+ "", EN))
+ self.assertEqual(code, 1)
+ self.assertIn("nested", err)
+
+ def test_unclosed_region_dies(self):
+ code, err = _die_message(self, lambda: scan_markers(
+ "body", EN))
+ self.assertEqual(code, 1)
+ self.assertIn("unclosed", err)
+
+ def test_mismatched_closer_dies(self):
+ code, err = _die_message(self, lambda: scan_markers(
+ "body", EN))
+ self.assertEqual(code, 1)
+ self.assertIn("does not close", err)
+
+
+class TestSubstitute(unittest.TestCase):
+ def test_fig_body_rebuilt_from_spec_exactly(self):
+ out = substitute(_DOC, EN, _FACTS, _ALTS)
+ # html.escape(alt, quote=True): quotes become entities, amp doubled.
+ expected_img = (''
+ 'ok ')
+
+
+class TestRealAssetsPassGates(unittest.TestCase):
+ def test_all_thirteen_assets_pass(self):
+ svgs = sorted(p.name for p in ASSETS.glob("*.svg"))
+ self.assertEqual(len(svgs), 13)
+ for name in svgs:
+ n = assert_svg_sane((ASSETS / name).read_text(encoding="utf-8"),
+ name)
+ self.assertLessEqual(n, 8192, name)
+
+
+class TestGateRefusals(unittest.TestCase):
+ def test_loop_animation_banned(self):
+ src = _CHASSIS.replace("ok", "infinite")
+ with self.assertRaises(AssertionError) as cm:
+ assert_svg_sane(src, "mutant")
+ self.assertIn("infinite/indefinite loop", str(cm.exception))
+
+ def test_fill_only_class_on_stroked_mark(self):
+ src = _CHASSIS.replace("",
+ 'aaaaaaaaaa '
+ 'bbbbbbbbbb '
+ "")
+ with self.assertRaises(AssertionError) as cm:
+ assert_svg_sane(src, "mutant")
+ self.assertIn("overlap on baseline", str(cm.exception))
+
+ def test_a11y_metadata_missing(self):
+ src = _CHASSIS.replace(' role="img" aria-label="chassis"', "")
+ with self.assertRaises(AssertionError) as cm:
+ assert_svg_sane(src, "mutant")
+ self.assertIn("a11y metadata missing", str(cm.exception))
+
+ def test_malformed_xml(self):
+ src = _CHASSIS.replace("ok", "a < b")
+ with self.assertRaises(AssertionError) as cm:
+ assert_svg_sane(src, "mutant")
+ self.assertIn("not well-formed XML", str(cm.exception))
+
+ def test_byte_budget(self):
+ padding = ""
+ src = _CHASSIS.replace("", padding + "")
+ with self.assertRaises(AssertionError) as cm:
+ assert_svg_sane(src, "mutant")
+ self.assertIn("over budget", str(cm.exception))
+
+ def test_external_resource(self):
+ src = _CHASSIS.replace("ok", "@import url(x)")
+ with self.assertRaises(AssertionError) as cm:
+ assert_svg_sane(src, "mutant")
+ self.assertIn("external resource", str(cm.exception))
+
+ def test_motion_must_be_opt_in(self):
+ src = _CHASSIS.replace(
+ "",
+ "")
+ with self.assertRaises(AssertionError) as cm:
+ assert_svg_sane(src, "mutant")
+ self.assertIn("motion not opt-in", str(cm.exception))
+
+
+class TestRendererGoldenMaster(unittest.TestCase):
+ """Synthetic inputs, byte-exact expectations for ALL 13 renderers: any
+ structural change that alters rendering output by a byte fails here.
+ Goldens are regenerated ONLY by a reviewed, deliberate act (the lab's
+ gen_golden*.py scripts verify determinism and gate-cleanliness first)."""
+
+ ASOF = "2026-09-05"
+ ARIA = "synthetic aria"
+ D = datetime.date
+ DOMAIN = (D(2026, 1, 5), D(2026, 3, 1))
+
+ def _cases(self):
+ R, D, ASOF, ARIA = NS, self.D, self.ASOF, self.ARIA
+ return {
+ "growth": lambda: R["render_growth"](
+ [1, 0, 0, 13, 129, 198, 676, 589, 1181, 3193, 9313],
+ list(range(2016, 2027)), ASOF, ARIA),
+ "rhythm": lambda: R["render_rhythm"](
+ Counter({18: 400, 10: 200}), ASOF, ARIA),
+ "ground": lambda: R["render_ground"](
+ {"negentropy": 40, "coding-proxy": 12, "hyper-git": 7},
+ {"coding-proxy": 3, "hyper-git": 1}, ASOF, ARIA),
+ "punchcard": lambda: R["render_punchcard"](
+ Counter({(0, 22): 30, (6, 21): 25, (3, 10): 12, (5, 23): 8}),
+ self.DOMAIN, ASOF, ARIA),
+ "surplus": lambda: R["render_surplus"](
+ Counter({22: 60, 10: 30}), Counter({22: 80, 11: 20}),
+ 40, 12, self.DOMAIN, ASOF, ARIA),
+ "accrual": lambda: R["render_accrual"](
+ Counter({("negentropy", D(2026, 1, 1)): 20,
+ ("negentropy", D(2026, 2, 1)): 10,
+ ("hyper-git", D(2026, 2, 1)): 5}),
+ [(D(2026, 2, 15), "hyper-git")], self.DOMAIN, ASOF, ARIA),
+ "lifecycles": lambda: R["render_lifecycles"](
+ [("negentropy", D(2026, 1, 1), D(2026, 3, 1), False),
+ ("old-wing", D(2025, 6, 1), D(2026, 2, 1), True)],
+ (D(2025, 6, 1), D(2026, 3, 1)), ASOF, ARIA),
+ "cadence": lambda: R["render_cadence"](
+ {"coding-proxy": [
+ {"tag_name": "v0.1.0", "published_at": "2026-01-20T10:00:00Z",
+ "prerelease": False},
+ {"tag_name": "v0.2.0", "published_at": "2026-02-14T09:30:00Z",
+ "prerelease": True}],
+ "negentropy": [
+ {"tag_name": "v0.0.1", "published_at": "2026-02-01T08:00:00Z",
+ "prerelease": False}]},
+ self.DOMAIN, ASOF, ARIA),
+ "streak": lambda: R["render_streak"](
+ {D(2026, 6, d): (d % 5) for d in range(1, 31)},
+ (D(2026, 6, 10), D(2026, 6, 19)),
+ (D(2026, 6, 1), D(2026, 6, 30)), ASOF, ARIA),
+ "latency": lambda: R["render_latency"](
+ [("<1m", 5), ("1-2", 2), ("2-5", 3), ("5-15", 4), ("15-60m", 3),
+ ("1-4h", 2), ("4-24h", 1), (">24h", 0)],
+ [27.8, 38.9, 55.6, 77.8, 94.4, 100.0, 100.0, 100.0],
+ {"n": 20, "unmerged": 2, "med": "6 min", "p90": "2.8 h",
+ "med_i": 3, "hour_i": 4, "lat_max": "11.9 d"}, ASOF, ARIA),
+ "grammar": lambda: R["render_grammar"](
+ [("fix", 827), ("docs", 725), ("feat", 697), ("test", 6)],
+ 996, 4349, 19.0, ASOF, ARIA),
+ "tongues": lambda: R["render_tongues"](
+ Counter({"HTML": 50000, "Python": 20000, "TypeScript": 8000}),
+ Counter({"Python": 20000, "TypeScript": 8000, "HTML": 500}),
+ "threefish-ai.github.io", [], ASOF, ARIA),
+ "upstream": lambda: R["render_upstream"](
+ [{"html_url": "https://github.com/langgenius/dify/pull/1",
+ "repository_url": "https://api.github.com/repos/langgenius/dify",
+ "state": "closed",
+ "pull_request": {"merged_at": "2026-01-10T00:00:00Z"},
+ "number": 5631, "created_at": "2026-01-09T00:00:00Z"},
+ {"html_url": "https://github.com/foo/bar/pull/2",
+ "repository_url": "https://api.github.com/repos/foo/bar",
+ "state": "closed",
+ "pull_request": {"merged_at": None},
+ "number": 124, "created_at": "2026-02-01T00:00:00Z"}],
+ 500, ASOF, ARIA),
+ }
+
+ def test_all_renderers_match_goldens(self):
+ for name, render in self._cases().items():
+ with self.subTest(figure=name):
+ actual = render()
+ assert_svg_sane(actual, name) # goldens must be gate-clean
+ expected = (GOLDEN / f"{name}_synthetic.svg").read_text(
+ encoding="utf-8")
+ self.assertEqual(actual, expected)
+
+ def test_golden_files_are_exactly_thirteen(self):
+ self.assertEqual(
+ sorted(p.name for p in GOLDEN.glob("*.svg")),
+ [f"{k}_synthetic.svg" for k in sorted(self._cases())])
+
+
+if __name__ == "__main__":
+ unittest.main()
 Eleven years, square-root scale. **9,313 in 2026** — after two years that are genuinely zero and one year that is genuinely down.
**2016** — one commit. **2017–2018** — nothing; the gap in the chart is real, and it is two years long. **2019** — 13. **2020** — 129, the year of coming back. **2021** — 198. **2022** — 676. **2023** — 589, lower than the year before, and the chart does not smooth it. **2024** — 1,181; the first upstream patch merged into [Dify](https://github.com/langgenius/dify/pull/5631) that July. **2025** — 3,193; `negentropy-perceives` in August, `agentic-ai-cognizes` in October. **2026-01-31** — the trunk starts. **2026-05-18** — both of those repositories are archived into it. **2026** — 9,313 so far.
+
 The surplus, located: **22:00**, 2.54× a flat baseline — 4,349 open-source commits, Asia/Shanghai. Dawn is empty, not missing.
+
 The two-dimensional answer: densest cell **Sun 22:00**, 83 commits; 37 of 168 cells are true zeros; weekends hold 34.7% against a 28.6% flat share.
+
 Weekday vs weekend, normalised to per-day rates (**572 weekdays ÷ 230 weekend days**): same shape, and the weekend actually runs hotter per day — peak at 22:00. "By day" is a job description, not a schedule.
+
 [negentropy](https://github.com/ThreeFish-AI/negentropy) knowledge engine · [coding-proxy](https://github.com/ThreeFish-AI/coding-proxy) failover for coding agents · [hyper-git](https://github.com/ThreeFish-AI/hyper-git) changelists for VS Code · [agents.md](https://github.com/ThreeFish-AI/agents.md) the doctrine they are written under
+
 Cumulative, monthly: two curves flatten on the day they graduated into the trunk, which keeps climbing. Window 2024-06-22 → 2026-09-01 — **26 months, not the eleven years above.**
+
 Repositories as intervals, creation to last push; the two same-day endings are the graduation. Deleted repos are invisible at this caliber.
+
 Releases have timing, not just counts — latest: **give-me-a-break v0.1.6**. negentropy ships as merged PRs, not tags.
+
 The run the rug brackets: **88 days, 2026-03-19 → 2026-06-14**, the longest inside its latest-400-day window; the all-time longest is 88 days (2026-03-19 → 2026-06-14). Of the 802 days in the whole window, 249 carried a commit (31%) — authored commits in source repos, a narrower population than the GitHub calendar above.
+
 What the median hides: p90 **2.8 h**, longest **11.9 d**; of 1118 closed, 40 were never merged and are excluded. Solo self-merge: this measures change-unit size, not review speed.
+
 Seventy-seven of a hundred, made countable: **fix 19.0%** leads; **996 subjects (22.9%) don't parse** — drawn as open cells, not hidden.
+
 Both conditions, not a silent pick: GitHub's endpoint says **HTML 67.8%**; excluding the one generated-site repo, **Python 69.1%**. Bytes measure source size, not effort or authorship.
+
 N = 6, named: 2024-06-26 → 2025-12-06, 5 merged, one closed unmerged — a fraction of a percent of all public PRs.
+
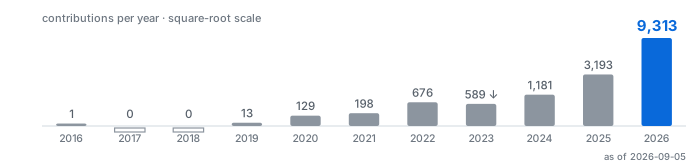 十一年,平方根标度。**9,313(2026)**——此前是两个真正的零,和一次真正的回落。
**2016** —— 一条提交。**2017–2018** —— 空的;图上那个缺口是真的,而且长达两年。**2019** —— 13 条。**2020** —— 129 条,回来的那一年。**2021** —— 198 条。**2022** —— 676 条。**2023** —— 589 条,低于上一年,图没有把它抹平。**2024** —— 1,181 条;当年 7 月,第一个上游补丁合入 [Dify](https://github.com/langgenius/dify/pull/5631)。**2025** —— 3,193 条;8 月有了 `negentropy-perceives`,10 月有了 `agentic-ai-cognizes`。**2026-01-31** —— 主干开始。**2026-05-18** —— 那两个仓库归档并入主干。**2026** —— 目前 9,313 条。
+
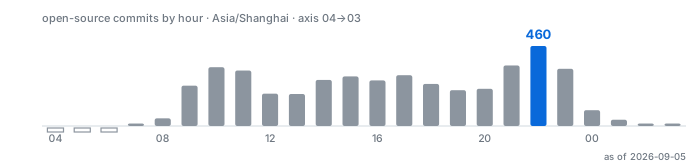 余暇的落点:**22:00**,平坦基线的 2.54×——4,349 条开源提交,Asia/Shanghai。黎明是空的,不是缺数据。
+
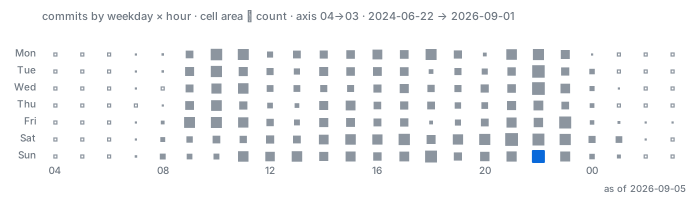 二维答案:最密格 **Sun 22:00**(周日 22:00),83 条提交;168 格中 37 格为真实零值;周末占 34.7%(平坦份额 28.6%)。
+
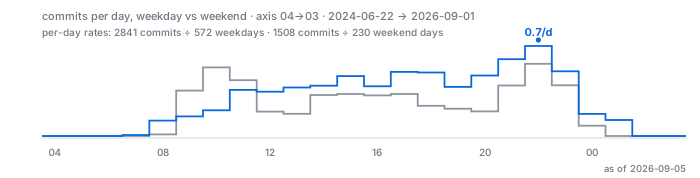 工作日对周末,按日均归一(**572 个工作日 ÷ 230 个周末日**):形状相同,且周末的日均反而更热——峰值落在 22:00。「白天」是职业描述,不是作息表。
+
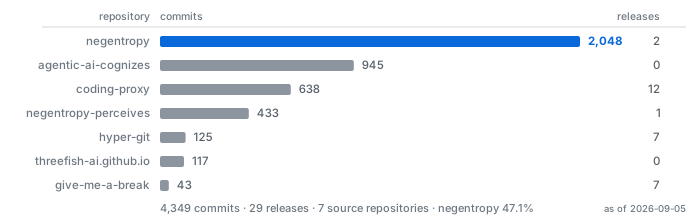 [negentropy](https://github.com/ThreeFish-AI/negentropy) 知识引擎 · [coding-proxy](https://github.com/ThreeFish-AI/coding-proxy) 编码 Agent 故障转移 · [hyper-git](https://github.com/ThreeFish-AI/hyper-git) VS Code 变更列表 · [agents.md](https://github.com/ThreeFish-AI/agents.md) 它们共同遵循的规约
+
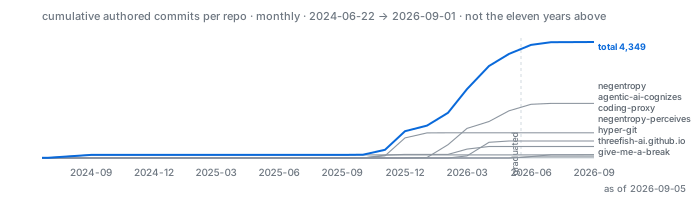 月度累计:两条曲线在毕业并入主干的那一天走平,而主干继续爬升。窗口 2024-06-22 → 2026-09-01——**26 个月,不是上方那张十一年图。**
+
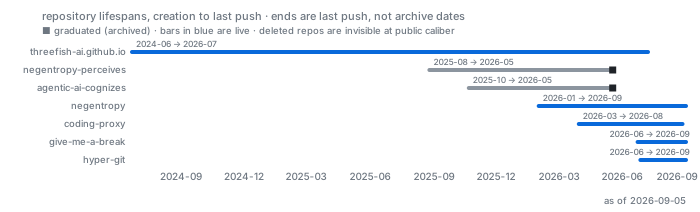 仓库即区间,自创建至最后推送;两根同日终止的条就是那次毕业。已删除的仓库在此口径下不可见。
+
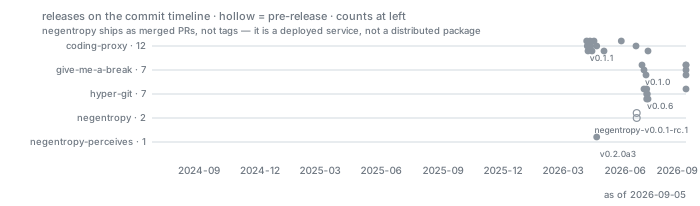 Release 有时机,不止有计数——最新一个:**give-me-a-break v0.1.6**。negentropy 以已合并 PR 交付,不以 tag。
+
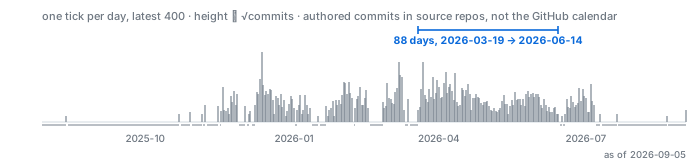 rug 图括号标注的区间:**88 天,2026-03-19 → 2026-06-14**,是它那最近 400 天窗口内最长的一段;历史最长为 88 天(2026-03-19 → 2026-06-14)。整个窗口 802 天中 249 天有提交(31%)——口径为源仓库内我署名的提交,窄于上方的 GitHub 贡献日历。
+
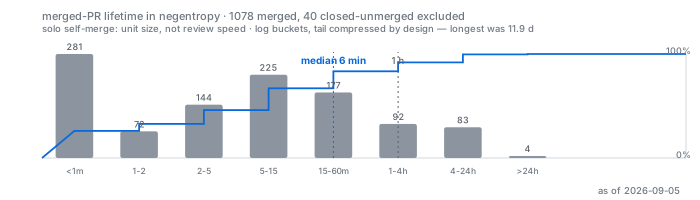 中位数藏掉的部分:p90 **2.8 h**,最长 **11.9 d**;已关闭 1118 个中 40 个未合并,未计入。单人自合并:量的是变更单元大小,不是评审速度。
+
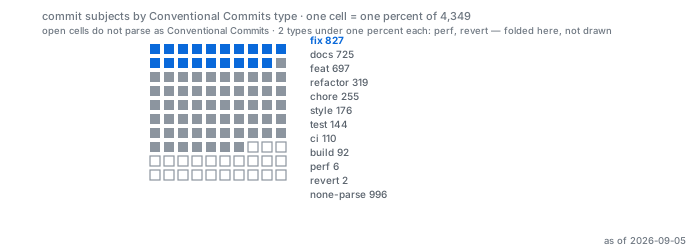 让「一百中之七十七」可数:**fix 19.0%** 居首;**996 条主题(22.9%)不合规**——画作空心格,而不是藏起来。
+
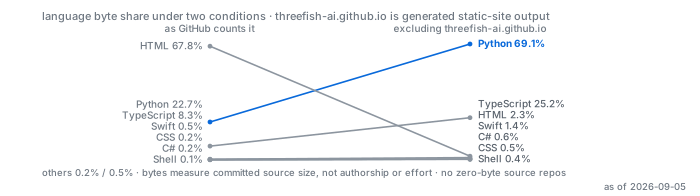 两种口径并陈,而非悄悄二选一:GitHub 端点说 **HTML 67.8%**;剔除那个静态站构建产物仓库后,**Python 69.1%**。字节数度量源码体积,不度量工作量或作者归属。
+
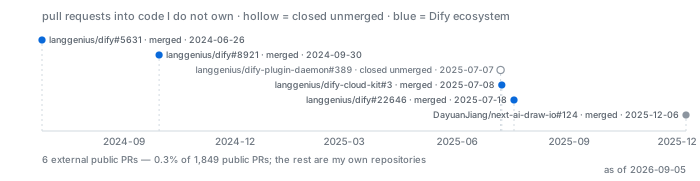 N = 6,全部具名:2024-06-26 → 2025-12-06,5 个已合并、一个关闭未合并——占全部公开 PR 的千分之几。
+