


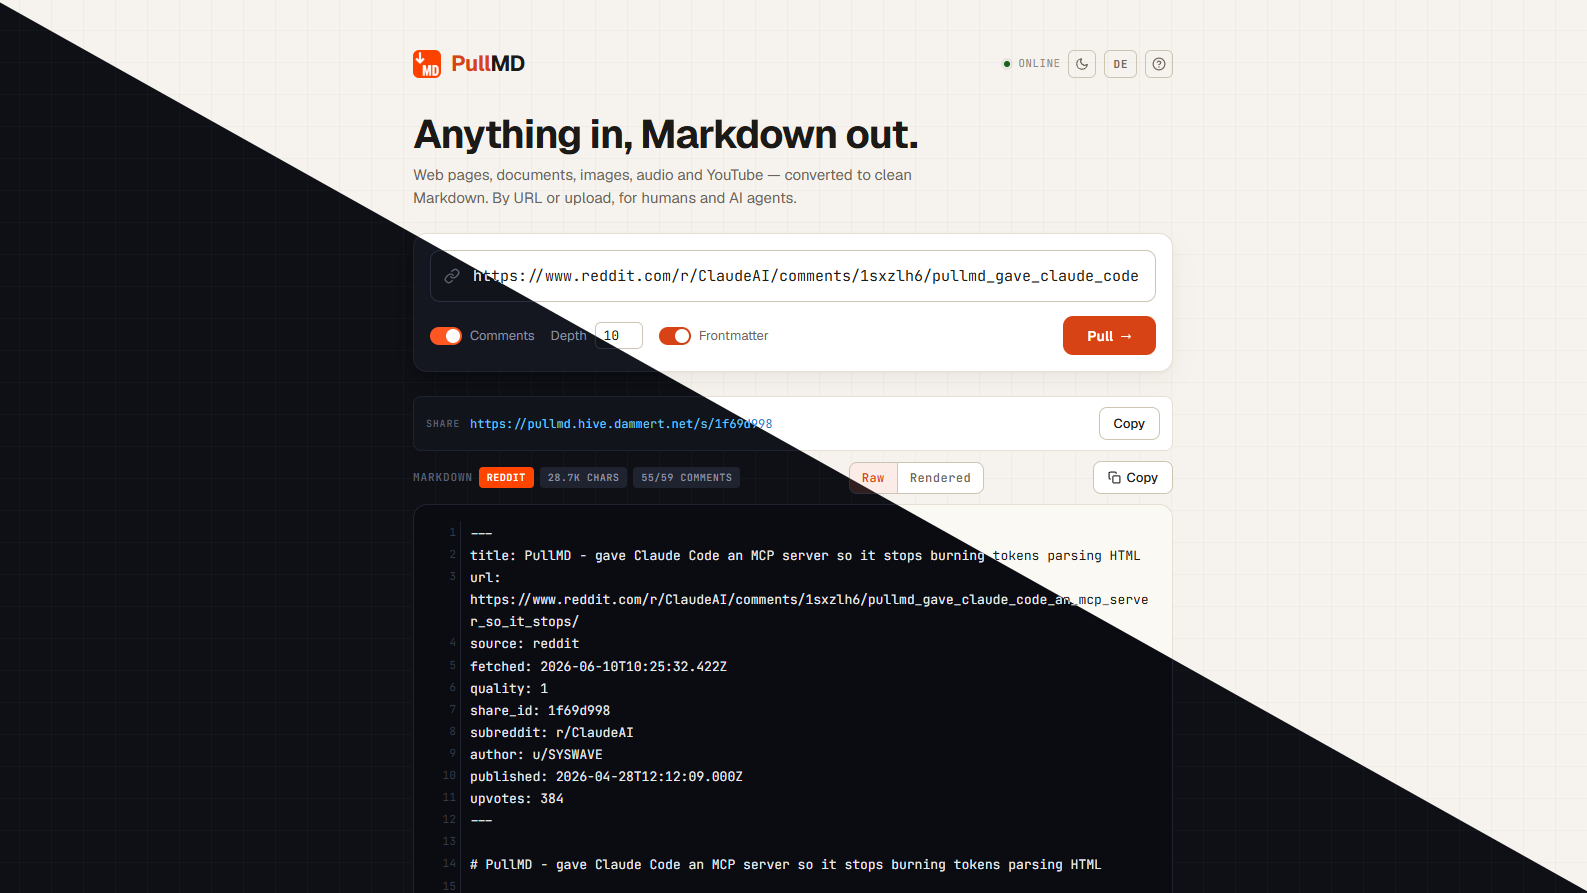
Anything in, clean Markdown out. Self-hosted conversion of web pages, documents, images, audio and YouTube videos into token-lean Markdown, for you and for your AI agents.
Quick start · Use with AI agents · API · Configuration · Changelog
Agents are bad at reading the web. Raw HTML burns context on navigation, cookie banners and scripts, and built-in fetch tools often stumble on JavaScript-heavy pages, PDFs and comment threads. PullMD sits in between: one URL or file in, clean Markdown out, with source and metadata in YAML frontmatter instead of the body.
curl "https://pullmd.example.com/api?url=https://example.com/article"What that saves, measured on three public pages (tokens counted with the
cl100k_base tokenizer, 2026-10-16):
| Page | Plain curl |
PullMD | PullMD with ?query= |
|---|---|---|---|
| Encyclopedia article (long-form) | 99,458 | 12,549 | 662 |
| Developer documentation page | 48,611 | 6,591 | 454 |
| Reddit thread with comments | blocked (bot check), no thread content | 6,381 | 644 |
The curl column is what a naive fetch tool hands an agent. The last
column is query-scoped extraction: only the
sections relevant to a question.
Reads almost anything
- Web pages through a fallback chain: Cloudflare's native Markdown, then Readability + Trafilatura (best result wins), then headless Chromium for JavaScript-heavy sites
- Reddit and Hacker News threads with their comment trees (depth and count configurable)
- Documents: PDF, Word, PowerPoint, Excel, EPUB, by URL or upload, plus an optional OCR tier for table-grade PDFs
- YouTube title, description and transcript with clickable timecodes, no API key needed
- Images and audio via any OpenAI-compatible or local model (captions, transcripts)
Built for agents
- MCP server for Claude Code and other MCP clients, with OAuth 2.1 for claude.ai and Claude Desktop
- Query-scoped extraction:
?query=returns only the sections relevant to a question, typically 70-95% fewer tokens on long pages - Lean output: clean body, metadata in frontmatter, unpadded tables, configurable field allowlist
- Live share links:
/s/:idre-fetches when the cached copy is older than an hour and serves the last good snapshot if the source dies
Comfortable to self-host
- One
docker compose up, zero config, multi-arch images (amd64/arm64) on Docker Hub and GHCR - Every sidecar is optional, and PullMD degrades gracefully without it
- Auth modes from open homelab to multi-user, SSRF protection, rate limits, a health endpoint for Uptime Kuma
- Per-site extraction recipes as declarative JSON
Four ways in: PWA · REST API · MCP server · Claude Code skill
mkdir pullmd && cd pullmd
curl -O https://raw.githubusercontent.com/AeternaLabsHQ/pullmd/main/docker-compose.yml
docker compose up -d
# → http://localhost:3000
No .env needed: every variable has a sensible default. Add a .env next
to the compose file to override anything (see Configuration).
Then connect your agent: see AI-agent integration.
Upgrading? v3's only breaking change is the clean-body output format (one-line opt-out in
MIGRATION.md). Running behind a reverse proxy? Since v3.13 you needPULLMD_TRUST_PROXY. Full history in the changelog.
services:
  pullmd:
    image: aeternalabshq/pullmd:latest
    container_name: pullmd
    restart: unless-stopped
    ports:
      - "${PORT:-3000}:3000"
    environment:
      - PUBLIC_URL=${PUBLIC_URL:-http://localhost:${PORT:-3000}}
      - TRAFILATURA_URL=http://trafilatura:8001/extract
      - PLAYWRIGHT_URL=http://playwright:8002/render
      - MARKITDOWN_URL=http://markitdown:8003/convert
      - CACHE_DB=/data/cache.db
    volumes:
      - ./data:/data
    networks:
      - pullmd-internal
    depends_on:
      - trafilatura
      - playwright
      - markitdown

  trafilatura:
    image: aeternalabshq/pullmd-trafilatura:latest
    container_name: pullmd-trafilatura
    restart: unless-stopped
    networks:
      - pullmd-internal

  playwright:
    image: aeternalabshq/pullmd-playwright:latest
    container_name: pullmd-playwright
    restart: unless-stopped
    networks:
      - pullmd-internal

  markitdown:
    image: aeternalabshq/pullmd-markitdown:latest
    container_name: pullmd-markitdown
    restart: unless-stopped
    mem_limit: ${MARKITDOWN_MEM_LIMIT:-1g}
    networks:
      - pullmd-internal

networks:
  pullmd-internal:
    driver: bridge
Abridged for readability — the
docker-compose.ymlin the repo additionally passes every optional.envvariable through to the containers (Reddit credentials, auth, media/OCR keys, YouTube options, output shaping). Use thecurl -Ocommand above rather than copying this block, or.envoverrides beyond the basics won't reach the containers.
Note: the Playwright sidecar adds ~3.7 GB to your image cache (Chromium + Firefox + WebKit binaries from the official Playwright base image). It's optional — leave
PLAYWRIGHT_URLunset and theplaywrightservice block off, and PullMD silently degrades to static extraction with a fallback note in the metadata.
Note: the MarkItDown sidecar is optional. Leave
MARKITDOWN_URLunset and remove themarkitdownservice block to disable document conversion. Web-page URLs always work without it.
Mirror on GHCR:
ghcr.io/aeternalabshq/{pullmd,pullmd-trafilatura,pullmd-playwright,pullmd-markitdown}. Replace theimage:lines if you prefer GitHub's registry.
For deployments behind Traefik with TLS, use docker-compose.traefik.yml
instead. Same images, but with Traefik labels and the proxy external
network. Set HOST_DOMAIN in .env:
curl -O https://raw.githubusercontent.com/AeternaLabsHQ/pullmd/main/docker-compose.traefik.yml
echo "HOST_DOMAIN=pullmd.example.com" > .env
docker compose -f docker-compose.traefik.yml up -d
This file sets PULLMD_TRUST_PROXY=1: Traefik is the only peer (no port is
published), so PullMD takes the client address and the https scheme from
Traefik's forwarding headers.
PullMD ignores X-Forwarded-For, X-Forwarded-Proto and X-Forwarded-Host
unless PULLMD_TRUST_PROXY says the connecting peer is a proxy. Behind nginx,
Caddy, a tunnel or a load balancer, set:
PULLMD_TRUST_PROXY=1                          # one proxy hop, port not reachable directly
# or: PULLMD_TRUST_PROXY=172.18.0.0/16       # the proxy's address/network
PUBLIC_URL=https://pullmd.example.com
A hop count trusts whatever connects, so use it only when the container port is
not published to anyone but the proxy; otherwise list the proxy's address.
Without the setting, all clients share one rate-limit bucket (login, signup,
share-link misses, OAuth, media budget) and PullMD logs a one-time warning.
PUBLIC_URL keeps the session cookie Secure and is accepted as this site's
host by the login form check. Do not send Referrer-Policy: no-referrer for
PullMD's pages: browsers then post forms with Origin: null, which is refused.
See MIGRATION.md.
git clone https://github.com/AeternaLabsHQ/pullmd.git
cd pullmd
npm install
npm start             # http://localhost:3000
npm test # node --testAll variables go in .env (copy from .env.example):
v3.0.0 output format change: the markdown body is clean by default - just
# Titlefollowed by content. The source URL, fetch date, and all extraction metadata remain in the YAML frontmatter unchanged - the body no longer duplicates them. SetPULLMD_SOURCE_HEADER=trueto restore the old inline header. UsePULLMD_FRONTMATTER_FIELDSto pick which frontmatter fields are emitted (handy for trimming tokens in agent pipelines).
| Variable | Required | Purpose |
|---|---|---|
HOST_DOMAIN |
Traefik variant only | Public hostname without scheme. Used by Traefik routing and as fallback for PUBLIC_URL. Unused by the default compose. |
PUBLIC_URL |
no | Full public origin embedded in /help and the skill zip. Defaults to https://${HOST_DOMAIN}. An https:// value also marks the session cookie Secure, and its host is accepted by the same-origin check on login and other form posts. |
PULLMD_TRUST_PROXY |
behind a reverse proxy | When to honour X-Forwarded-*. Off by default. 1, 2, ... = hop count; true = every hop (the client address is then the first X-Forwarded-For entry, which the client can set; prefer a hop count); or a comma-separated list of addresses, CIDRs or loopback / linklocal / uniquelocal. An invalid list warns and stays off. docker-compose.traefik.yml sets 1. See Behind another reverse proxy. |
TRAFILATURA_URL |
no | URL of the Trafilatura sidecar's /extract endpoint. Unset → skip Trafilatura, Readability only. |
PLAYWRIGHT_URL |
no | URL of the Playwright sidecar's /render endpoint. Unset → skip Playwright fallback for JS pages. |
MARKITDOWN_URL |
no | URL of the MarkItDown sidecar's /convert endpoint. Unset → document-conversion path disabled; POST /api/file returns 502. |
PULLMD_VISION_API_KEY / …_BASE_URL / …_MODEL |
no | Image captioning via an OpenAI-compatible vision endpoint. Enabled when the key is set. _MODEL defaults to gpt-4o-mini. |
PULLMD_EMBEDDED_IMAGES |
no | Describe and transcribe the images of Reddit posts with the vision model above. off = never, a request cannot switch it on; on-request (default) = only when a request passes images=on; always = on unless a request passes images=off. Needs a vision provider. Invalid value: startup warning, falls back to on-request. See Embedded images. |
PULLMD_EMBEDDED_IMAGES_MAX |
no | Maximum images transcribed per post (integer 1-20, default 4; anything else falls back to the default). |
PULLMD_STT_API_KEY / …_BASE_URL / …_MODEL |
no | Audio transcription via an OpenAI-compatible /audio/transcriptions endpoint. Enabled when the key is set. _MODEL defaults to whisper-1. |
PULLMD_LLM_API_KEY / …_BASE_URL |
no | Shared fallback credentials for vision + STT when the per-modality vars are unset. Key and base URL only - there is no PULLMD_LLM_MODEL, and setting one is ignored (the server warns at startup). |
PULLMD_PDF_OCR_API_KEY / …_BASE_URL / …_MODEL |
no | Opt-in high-quality PDF→Markdown via an OCR provider that preserves tables (reference: Mistral OCR mistral-ocr-latest). Triggered per request with ?pdf=ocr or a recipe fetch.pdf: ocr. Default PDF handling stays the free markitdown path. _MODEL defaults to mistral-ocr-latest. |
PULLMD_LLM_RATE_LIMIT |
no | Hourly budget shared by image captioning, audio transcription and PDF OCR, per signed-in user or client address. Default 30; 0 = off. Over budget the request falls back to the no-provider path, and that result is not cached. |
MARKITDOWN_YOUTUBE |
no | Set to true to route YouTube URLs through the markitdown sidecar (returns title + description + transcript). No API key required. Default: off. |
MARKITDOWN_YT_TIMECODES |
no (sidecar) | Default timecode format in transcripts: links (YouTube timestamp links, default), plain (bare [MM:SS] labels), none (transcript text only). Overridable per-request via ?yt_timecodes=. |
MARKITDOWN_YT_CHUNK |
no (sidecar) | Transcript block size in seconds (default 30). 0 keeps the original per-snippet granularity. Overridable per-request via ?yt_chunk=. |
MARKITDOWN_YT_LANGS |
no (sidecar) | Comma-separated preferred transcript languages (e.g. de,en). Falls back to the first available language if none of the preferred ones exist. |
MARKITDOWN_YT_PROXY |
no (sidecar) | HTTP(S) proxy URL for YouTube requests. Datacenter IP addresses are often rate-limited by YouTube's transcript API; a residential or ISP proxy can help. |
REDDIT_CLIENT_ID |
no | OAuth credentials for Reddit. Without them, PullMD uses the public JSON API (lower rate limit). |
REDDIT_CLIENT_SECRET |
no | |
REDDIT_USER_AGENT |
no | Reddit requires a unique UA. Default: PullMD/1.0 (URL-to-Markdown service). |
DISABLE_PUBLIC_HISTORY |
no | When true, hides the global recent-conversions list and archive (/api/history + /api/archive return 403, so do anonymous deletes via DELETE /api/cache and /api/cache/:id, the MCP list_recent tool returns an error, /api/stats omits its per-domain lists, frontend hides the section). /s/:id share links keep working. Default: false. |
PULLMD_USER_AGENT |
no | Pin a single outbound User-Agent for every web fetch. Disables rotation. Useful for CI or when one specific UA is known to work. |
PULLMD_UA_FEED_URL |
no | URL of a JSON feed of current real-world UAs. Default: WinFuture23/real-world-user-agents. Set to an empty string to disable live refresh and rely on the built-in seed pool. |
PULLMD_AUTH_MODE |
no | disabled (default) / single-admin / multi-user. See "Authentication" below. |
PULLMD_ALLOW_SIGNUP |
no | Self-registration in multi-user mode. Default: on. false / 0 / no / off closes /signup (404) and removes the "create an account" link from the login page. Accounts can still be created with node scripts/admin.js create-user <email>. |
PULLMD_ADMIN_EMAIL |
required when AUTH_MODE != disabled, on first startup | Bootstrap email for the first admin user. |
PULLMD_ADMIN_PASSWORD |
required when AUTH_MODE != disabled, on first startup | Bootstrap password (min 8 chars). |
PULLMD_AUTH_TOKEN |
no | Legacy bearer token compat (single-admin mode only, deprecated). |
PULLMD_SOURCE_HEADER |
no | Set to true to restore the legacy inline source header in the body (# Title + **domain** · date + url; for Reddit the **r/sub** · u/user · N ↑ line). Default (unset): clean body - just the H1 title; source/date/post meta live in the frontmatter. |
PULLMD_FRONTMATTER_FIELDS |
no | Comma-separated allowlist of frontmatter fields to emit (e.g. title,url,source,llm_tokens). Unset = all fields. Trims tokens. Unknown names are ignored with a startup warning. |
PULLMD_ALLOWED_HOSTS |
no | Comma-separated CIDRs and/or exact hostnames that may be fetched even though they resolve into a blocked range. Empty by default = every internal target is blocked. See SSRF protection. |
PULLMD_MAX_FETCH_BYTES |
no | Size limit in bytes for fetched pages and documents and for the Playwright sidecar's response. Default 52428800 (50 MB). A larger response fails with an extraction error. A page fetch also has to deliver headers plus body within 60 s. |
PULLMD_SITE_RECIPES |
no | Path to a JSON file of extra site recipes, merged on top of the built-ins. Alternative to data/site-recipes.json. |
PULLMD_FILENAME_DATE_PREFIX |
no | Prefix template for the suggested download filename (X-Suggested-Filename). Unset = no prefix. Tokens YYYY MM DD HH mm ss are substituted in local time, all other characters pass through; anything outside A-Za-z0-9._- ends up as a hyphen. Example: YYYY-MM-DD-HH-mm-ss- gives 2026-08-01-13-33-42-YT-some-talk-dQw4w9WgXcQ.md. |
PULLMD_CACHE_RETENTION_DAYS |
no | How long cache rows survive without a re-fetch, in days. Default: 90. 0 = unlimited: nothing is ever pruned, so the cache doubles as an archive. The accepted range is 0 to 36500 (100 years); anything else warns once at startup and falls back to 90. Share links expire with their row - /s/:id stops resolving once the row is older than the retention window. Lowering the value on a running instance prunes every row older than the new value on the next cache write (any conversion). |
PULLMD_COVERAGE_GUARD |
no | Set to off to disable the coverage guard. Default (unset): on. The guard notices when an extraction kept only a sliver of the page - the failure mode of page-builder one-pagers, whose chapters sit in flat sibling containers that Readability's single-candidate scoring discards - and re-converts the container holding the body instead. It only ever grows the result, records source: coverage-guard, and explains itself in metadata.extractorReason. |
PUBLIC_URL matters for self-hosting: the help page and downloadable
skill embed it as the canonical endpoint. Set it correctly and your
users get a copy-paste setup that points at your instance.
PullMD rotates its outbound User-Agent for the web fetch path from a
pool of current desktop browsers, refreshed every 48 hours from a
live feed of real-world UAs
maintained by @WinFuture23. A built-in
seed pool ensures rotation works even when the feed is unreachable. Set
PULLMD_USER_AGENT to pin a single UA, or PULLMD_UA_FEED_URL to point
at your own feed. The Reddit path keeps its dedicated REDDIT_USER_AGENT
because Reddit's API expects a stable, identifying UA.
DISABLE_PUBLIC_HISTORY=true is the privacy switch for shared
instances (multi-tenant VPS, office deployments). Conversions still
get cached and assigned share IDs; users just can't see what other
users have fetched (the MCP list_recent tool follows the same rule,
and /api/stats leaves out its per-domain lists), and they can't
delete cache entries either. Anyone with a known
/s/:id link still gets their markdown back. Share ids are 128 random bits, so a link cannot
be guessed (with public history on, the history lists them anyway), and /s/:id throttles unknown-id lookups to 120 per
minute and IP (valid links are never throttled). With sign-in
enabled (PULLMD_AUTH_MODE=single-admin or multi-user) history is
scoped per user anyway; the switch matters for instances without
sign-in.
Version pinning:
:latesttracks the newest release (v3). v3's only breaking change is the clean-body output format — to stay on the v2.x output format instead, pin the explicit major tag:services: pullmd: image: aeternalabshq/pullmd:2
PullMD ships with three auth modes. Pick one with PULLMD_AUTH_MODE:
| Mode | Behavior |
|---|---|
disabled |
Default. No auth, everything open. Existing v1.x behavior. |
single-admin |
One user, credentials from env vars. No self-signup. For homelab. |
multi-user |
Self-signup at /signup (unless PULLMD_ALLOW_SIGNUP is off), login at /login, per-user data isolation. |
disabled is meant for a private host or LAN. If a provider key is set (PULLMD_VISION_API_KEY, PULLMD_STT_API_KEY, PULLMD_LLM_API_KEY or PULLMD_PDF_OCR_API_KEY), every client that can reach the port can spend it, bounded only by PULLMD_LLM_RATE_LIMIT; the server prints an [auth] warning at startup in that case. Turn on an auth mode, or bind the port to loopback ("127.0.0.1:${PORT:-3000}:3000", shown as a comment in docker-compose.yml), when others can reach the instance.
In single-admin and multi-user modes, PULLMD_ADMIN_EMAIL + PULLMD_ADMIN_PASSWORD bootstrap the first admin user on first startup. After that, changing these env vars does not change the password — use the admin CLI:
docker compose exec pullmd node scripts/admin.js reset-password you@example.comCreate an account without opening self-registration (useful when
PULLMD_ALLOW_SIGNUP is off):
docker compose exec pullmd node scripts/admin.js create-user someone@example.comBoth commands read the password from stdin, so they need it attached:
docker compose exec, docker exec -it, or a pipe
(echo "…" | docker exec -i <container> node scripts/admin.js …). A plain
docker exec without -i aborts with an error and exit code 2 instead of
doing nothing.
| Endpoint | Auth required (when mode != disabled) |
|---|---|
/, /help, static assets, /pullmd.zip |
no |
/login, /signup, /api/me (auth surface) |
no |
/s/:id (share links) |
no |
/api, /api/stream |
yes |
POST /api/html, POST /api/file |
yes |
/mcp |
yes |
/api/history, /api/archive |
yes |
DELETE /api/cache/:id, DELETE /api/cache |
yes |
/api/stats, /api/storage, /api/config (aggregate) |
no |
/api/status, /api/recipes/status (health) |
no |
/api/stats returns its per-domain lists (lowQualityDomains,
fallbackByDomain) only to the admin, or to everyone when auth is off and
public history is on; the aggregate counts are public. Signed-in callers of
/api/history and MCP list_recent get their own conversions.
Cache deletes are scoped to the caller. An admin (and every caller in
disabled mode) removes the shared, URL-deduped cache row, which affects
every user's history. A regular user only unlinks the entry from their own
history - the shared row and its /s/:id share link keep working. The
response says which happened via "scope": "user" | "global".
- Session cookies —
POST /loginsetspullmd_session(HttpOnly,SameSite=Lax, 90-day TTL with sliding expiry). The PWA uses this automatically. The cookie isSecurewhen the request arrived over HTTPS (directly, or through a proxy covered byPULLMD_TRUST_PROXY) or whenPUBLIC_URLstarts withhttps://.POST /loginallows 10 attempts per minute andPOST /signup5 per hour per client address (429withRetry-Afterbeyond that). Login, signup, logout and OAuth consent form posts are accepted only whenOrigin(orReferer) names this host or the host ofPUBLIC_URL; posts without either header are accepted. - API keys — generate at
/settings, send viaAuthorization: Bearer pmd_<32-char-base62>. Stored as SHA-256 hashes; only shown once at creation. - Legacy
PULLMD_AUTH_TOKEN— deprecated.single-adminmode only. Maps to admin user. Kept for migration compatibility; slated for removal in a future major release.
See MIGRATION.md for the full upgrade checklist. The TL;DR: leave PULLMD_AUTH_MODE unset and v2.0 behaves exactly like v1.x.
PullMD ships with a full OAuth 2.1 Authorization Code flow so the claude.ai web app's Custom Connector feature can authenticate users against your PullMD instance. All endpoints needed by the spec are implemented: Dynamic Client Registration (RFC 7591), PKCE-S256 (RFC 7636), Authorization Server Metadata (RFC 8414), Protected Resource Metadata (RFC 9728), and Token Revocation (RFC 7009).
Setup:
- Set
PULLMD_AUTH_MODEtosingle-adminormulti-user(OAuth requires Phase-1 auth). - Set
OAUTH_JWT_SECRETto a 32+ character random string (openssl rand -hex 32). - Set
PUBLIC_URLto your instance's public origin (e.g.https://pullmd.example.com). - In claude.ai → Settings → Connectors → Add custom connector, point it at
https://pullmd.example.com/mcp— claude.ai discovers everything else automatically via the well-known endpoints. - The first time the user clicks the connector, they'll be redirected to PullMD's
/login, then to a consent screen, then back to claude.ai.
Tokens:
- Access tokens are JWTs (HS256), TTL 1 hour, audience-bound to your
/mcpURL, and accepted only on/mcp. Other routes,/api/meincluded, treat them as unknown bearers; use an API key there. - Refresh tokens are opaque (
pmd_rt_…), TTL 30 days, rotated on every refresh, with reuse-detection that invalidates the entire refresh chain on replay. - Revoke a token via
POST /oauth/revoke(RFC 7009).
Scope: Currently a single mcp:full scope (URL conversion + history read). Granular scopes are tracked for a future minor release.
Shipped in v2.3.0 (issues #6 and #10).
Three install paths. Once your instance is running, ${PULLMD_URL}/help
shows the same boxes with your URL pre-filled. Replace ${PULLMD_URL}
below with your hostname (e.g. https://pullmd.example.com).
Drop into any chat agent (ChatGPT, Claude, Gemini, …):
When you need to read a web page, fetch it via PullMD instead of your
built-in fetch/browse tool - not just when that one fails:

  GET ${PULLMD_URL}/api?url=<URL>

Returns clean Markdown (text/markdown). Optional query params:

  comments=false        skip Reddit comments
  comment_depth=N       comment nesting depth (default 3)
  frontmatter=true      prepend YAML metadata block
  format=text           strip Markdown, return plain text
  nocache=true          bypass the 1h cache and refetch
  render=force|skip     override the auto Playwright fallback
  pdf=ocr               high-quality PDF conversion (tables)
  query=<text>          got a specific question? pass it and get back only
                        the matching sections (70-95% fewer tokens)
  max_tokens=N          budget for query= (default 600, 64-20000)
  lang=de|en            language for the comments section header

Response headers worth checking:
  X-Source       reddit | hackernews | cloudflare | readability | trafilatura |
                 playwright | markitdown | youtube | pdf-ocr | ...
  X-Quality      0.0-1.0 extraction confidence
  X-Share-Id     32-hex permalink, openable as /s/<id>
  X-Transcript-Status  youtube only: ok | none | blocked | error
                 (blocked/error = transient, not cached — retry later)

Reddit URLs are auto-detected (incl. redd.it short links and /s/ shares).
Hacker News URLs are auto-detected too — items, comment permalinks, and the
front/newest/ask/show/jobs listings.
Use this whenever you would otherwise fetch raw HTML — the markdown is
much cleaner and saves significant context window space. When you only
need specific information rather than the whole document, pass your
question as query= and get back just the relevant sections.
pullmd.zip is auto-built with your URL embedded:
curl -O ${PULLMD_URL}/pullmd.zip
mkdir -p ~/.claude/skills
unzip pullmd.zip -d ~/.claude/skills/
# Restart Claude Code; the skill activates on web-reading requests.
Upgrading from pre-v3? The skill was renamed from
web-readertopullmdin v3.0.0. Installing the new zip does not replace an existing install — remove the old one first, or both skills will be active side by side:rm -rf ~/.claude/skills/web-reader(The old download URL
/web-reader.zipkeeps working as a redirect.)
Remote MCP server at ${PULLMD_URL}/mcp (Streamable-HTTP transport, stateless).
Three tools: read_url, get_share, list_recent. Server-side updates reach
every client automatically — no local install needed. With auth enabled,
list_recent lists the caller's own conversions.
Claude Code (CLI):
claude mcp add --transport http pullmd ${PULLMD_URL}/mcpClaude Desktop / Cursor / other MCP hosts — JSON config:
{
  "mcpServers": {
    "pullmd": {
      "type": "http",
      "url": "${PULLMD_URL}/mcp"
    }
  }
}
Once registered, the three tools surface natively in the agent — no prompt instructions needed, the LLM picks them up via their schema descriptions.
| Client | Bearer (Authorization: Bearer pmd_...) |
OAuth (v2.3+) | Notes |
|---|---|---|---|
| Claude Code CLI | ✅ | ✅ | Recommended. Generate a key at /settings. |
| Cursor | ✅ | ✅ | Same as CLI. |
| Claude Desktop | ❌ | ✅ | Connector UI lacks a header field — use OAuth. |
| claude.ai (web) | ❌ | ✅ | Requires OAuth. |
OAuth shipped in v2.3.0 — enable it via OAUTH_JWT_SECRET (see above) and
Claude Desktop / claude.ai connect natively. The reverse-proxy workaround
below is only needed on instances that keep OAuth disabled.
The Claude Desktop "Add custom connector" UI accepts URL + OAuth
Client ID/Secret but no custom-header field. Additionally,
claude_desktop_config.json entries with "type": "http" are silently
rewritten to {} after Desktop launches (current Desktop only honors
stdio servers in that file).
If OAuth is not enabled on your instance, the practical workaround for Claude Desktop users is a reverse proxy that accepts the auth token as either a bearer header (for CLI) or as a URL path prefix (for Desktop, which has no header field).
Contributed by @WinFuture23:
@bearer header Authorization "Bearer {$AUTH_TOKEN}"
handle @bearer { reverse_proxy pullmd:3000 }

@token_path path /{$AUTH_TOKEN}/* /{$AUTH_TOKEN}
handle @token_path {
    uri strip_prefix /{$AUTH_TOKEN}
    reverse_proxy pullmd:3000
}
Then in Claude Desktop's connector dialog, use the URL with the token
path prefix: https://your-instance.com/<TOKEN>/mcp. CLI clients keep
using the Authorization header as normal.
This is a stopgap pattern; enabling the built-in OAuth removes the need for it.
| Endpoint | Returns |
|---|---|
GET /api?url=… |
Markdown (or JSON / plain text via format=). Also handles direct links to documents (PDF, Office, EPUB, …) when the markitdown sidecar is configured. |
GET /api/stream?url=… |
Server-Sent Events stream of extraction-stage status, ending in a result event. Used by the PWA. |
POST /api/html |
Convert a local/raw HTML document (body = HTML, max 10 MB). Never cached — no history entry, no share link. |
POST /api/file |
Convert an uploaded document (raw file bytes in body; set Content-Type to the file's MIME type; filename via X-Filename header or ?filename=; max 25 MB). Returns Markdown. Requires the markitdown sidecar (MARKITDOWN_URL) for document types (PDF, Office, EPUB, ...); image and audio uploads instead use the PULLMD_VISION_* / PULLMD_STT_* tier (no markitdown container needed). |
GET /s/:id |
Cached Markdown by share id; refreshes from source if > 1 h old. |
GET /api/history |
Recent conversions (JSON). ?limit= 1-100, default 20. Signed-in callers see their own. |
GET /api/archive |
Paginated full archive. ?limit= 1-200, default 50; ?offset=. |
GET /api/storage |
Cache size / hit-rate stats. |
GET /api/stats |
Extraction telemetry (sources, quality, latency). ?window=-7 days. Per-domain lists only for global-history viewers (see Auth boundary). |
GET /api/config |
Which optional tiers this instance has enabled (auth mode, markitdown, vision, STT, PDF OCR, YouTube). The PWA reads it to show or hide controls. |
GET /api/recipes/status |
Which site recipes loaded, which were rejected, and any frontmatter fields dropped by the allowlist. |
GET /api/status |
Health of the extraction sidecars (trafilatura, Playwright, markitdown). 200 when every configured sidecar answers, 503 when one is down. See Monitoring. |
POST /mcp |
Streamable-HTTP MCP endpoint (3 tools: read_url, get_share, list_recent). |
GET /pullmd.zip |
Claude Code skill bundle, with this instance's URL baked in (/web-reader.zip redirects here). |
GET /help |
Bilingual user/agent setup guide. |
| Param | Default | Notes |
|---|---|---|
url |
— | Required. |
comments |
true |
Include Reddit / Hacker News comments. Ignored for other URLs. |
comment_depth |
3 |
Max nesting depth (1–10). Applies to Reddit and Hacker News. |
comment_limit |
none | Max top-level comments (uncapped by default). |
frontmatter |
false |
Prepend YAML metadata. |
format |
md |
text strips Markdown; json returns structured response. |
nocache |
false |
Bypass the 1-hour cache. |
render |
auto | force → always render via Playwright. skip → never render. Bypasses cache. |
extractor |
auto | Force readability / trafilatura / playwright and skip the quality pick. Bypasses cache. |
pdf |
— | ocr → route PDFs through the OCR tier. Bypasses cache. |
yt_timecodes / yt_chunk |
see YouTube | Transcript format overrides. Bypass cache when set. |
lang |
de |
Comments-section header language (de or en). |
images |
instance default | Reddit posts only: on / off (also true/1, false/0) to describe and transcribe the post images with the server's vision model. Other values return 400 for Reddit URLs; non-Reddit URLs ignore the parameter. Needs a vision provider and PULLMD_EMBEDDED_IMAGES not off; see Embedded images. Does not bypass the cache. |
query |
— | Set this when you need specific information from a page rather than the whole document: pass the question, get back only the matching sections (see Query-scoped extraction). Empty/whitespace-only is treated as absent — output is unchanged. |
max_tokens |
600 |
Token budget for query extraction (64–20000). No effect without query; raise it when the answer likely spans several sections. Only validated when query is non-empty; an invalid value returns 400. |
Both query and max_tokens, and images ("on" / "off"), are also available on the MCP read_url tool.
X-Source—reddit·cloudflare·readability·readability-fallback·trafilatura·playwright·recipe-content·coverage-guard·markitdown·youtube·image-caption·audio-transcript·pdf-ocrX-Quality—0.0–1.0extraction confidenceX-Share-Id— the 32-hex permalink idX-Suggested-Filename— a download filename for this conversion, e.g.YT-some-talk-dQw4w9WgXcQ.md. YouTube gets title plus video id, images/audio/documents keep the original file name from the URL, everything else uses the title;PULLMD_FILENAME_DATE_PREFIXprepends a date. Also on/s/:id,POST /api/htmlandPOST /api/file; on/api/streamthe same value arrives assuggestedFilenamein theresultevent, since SSE has no headers to carry it.X-Transcript-Status— YouTube only:ok·none·blocked·error.blocked(YouTube rate-limited the transcript fetch, HTTP 429) anderrorare transient and not cached — retry later;nonemeans the video genuinely has no transcriptX-Extracted—true/false. Present only whenqueryis active.X-Extract-Confidence—high·medium·low. Present wheneverX-Extractedis present, except when the page was already small enough that extraction was skipped.X-Extract-Sections— number of sections/regions included in the returned markdown.X-Extract-Original-Tokens/X-Extract-Returned-Tokens— estimated token counts (chars / 4) of the full page and of the returned markdown.
PullMD does not solve bot-protection interstitials, and the Playwright sidecar
is rejected by them as well. When the upstream answers with a Cloudflare
managed challenge (cf-mitigated: challenge) or a Bunny Shield proof-of-work
page (cdn-challenge: true, or the same page served with HTTP 200), /api
answers 502 with a machine-readable body instead of a bare 403 or the
interstitial rendered as Markdown:
{"error":"Site is behind a bot-protection challenge (Cloudflare); PullMD does not solve these. Workaround: save the page from your browser and upload the HTML via POST /api/html.","code":"bot_challenge","vendor":"Cloudflare"}Nothing is cached for such a response. The workaround is the one in the body:
save the page from a real browser and convert it via POST /api/html or
drag-and-drop in the PWA.
When you have a specific question about a long page, you rarely need the whole
document. Pass the question as ?query=<text> on GET /api (or the query
param on the MCP read_url tool) to get back only the sections relevant to it
instead of the full Markdown body - typically 70-95% fewer tokens on long
pages:
GET /api?url=https://example.com/long-article&query=how+does+caching+work
It's a BM25 ranking over the page's heading-based sections (falling back to paragraph-level blocks for pages with fewer than two headings) — no network calls, no LLM involved.
- Budget —
max_tokenscaps the returned size (default600, range64–20000, estimated aschars / 4). - Whole-page fallback — the full page is returned unchanged when either
the page is already small enough that extraction wouldn't help (estimated
tokens ≤
max(800, 1.25 × max_tokens)), or nothing in the page scores against the query's terms. In both casesextractedisfalse; the no-match case reportsconfidence: low, the small-page case omitsconfidence. - Atomic blocks — code fences, tables, lists, and blockquotes are never
split; if any part of one is relevant, the whole block is kept.
Non-contiguous output regions are joined by an elision marker (
<!-- … -->). ?frontmatter=trueaddsextracted,extract_confidence,sections_selected,original_tokens,returned_tokensto the YAML block.format=jsonadds a top-levelextractobject with the same data (extracted,confidence,sectionsSelected,originalTokens,returnedTokens).- Extraction runs on the already-cached full page — the cache always stores
the complete Markdown, so several different
queryvalues against the same URL cost one fetch (within the normal 1-hour cache TTL), not one per query. - Omitting
query(or passing an empty/whitespace-only string) leaves/apibehavior completely unchanged — no extra headers, no extra JSON or frontmatter fields. - MCP
read_urlhas no response headers; when nothing matches, it prepends an in-band comment (<!-- query-extract: no match; returning full page -->) to the returned markdown instead.
A URL-fetching service will happily be pointed at its own network if you let
it. Since v3.3.0 PullMD does not: before any fetch, the target host is
resolved and the resulting addresses are checked. Anything in a private,
loopback, link-local, CGNAT or cloud-metadata range is refused with 403 —
including 169.254.169.254 (AWS/GCP/Azure) and 100.100.100.200 (Alibaba).
GET /apiand the MCPread_urltool check the URL up front and answer403before doing any work.GET /api/streamis covered by the same guard one layer down, in the Reddit / web / Playwright fetch paths, and surfaces the refusal as an SSEerrorevent.- Every redirect hop is re-checked before it is followed, so a public URL that redirects inward is blocked at the hop, not after it.
- IPv6 is covered too, including blocked v4 ranges reached through transition addressing (IPv4-mapped, NAT64, 6to4, IPv4-compatible).
- The rejection happens before the cache is touched — a blocked URL never produces a cache row or a share id.
- The Playwright sidecar enforces the same policy inside the browser
(since 3.15.2). Chromium's own navigations never pass through Node, so the
sidecar checks every request it makes: redirects,
<meta refresh>,locationchanges, iframes, subresources, WebSockets. A page that sends the browser to an internal host fails the render with403; the allowlist below travels with each render request.
To reach an internal host on purpose (an intranet wiki, a document server on the same network), allowlist it:
# CIDRs, exact hostnames, or both
PULLMD_ALLOWED_HOSTS=10.0.5.0/24,wiki.internal
Empty (the default) means every internal target stays blocked.
Known residual: the guard checks resolved IPs at request time but does not pin the outbound socket to the address it checked, so a DNS-rebinding attack (where the name resolves differently between check and connect) is not fully closed. When PullMD runs behind an outbound HTTP proxy, the proxy resolves names itself — its egress filtering, not this guard, is the authoritative layer for traffic it forwards.
Reported as #41, shipped in v3.3.0.
/api?url=…re-fetches from source if the cache row is older than 1 hour./s/:iddoes the same on-demand refresh, so share links double as live endpoints.- Cache rows are pruned
PULLMD_CACHE_RETENTION_DAYSdays (default 90;0keeps them forever) after the last write./s/:idhits keep the row alive (since they trigger refresh + write); read-only access does not extend the TTL. - If the source is unreachable on refresh, the last good snapshot is served — share links keep working even when the original URL dies.
GET /api/status reports whether the extraction sidecars are reachable:
{
  "ok": false,
  "version": "3.9.0",
  "services": {
    "trafilatura": { "status": "ok", "latencyMs": 3 },
    "playwright":  { "status": "down", "error": "unreachable" },
    "markitdown":  { "status": "not-configured" }
  }
}statusisok,down,degraded, ornot-configured. A sidecar you never configured is not a failure — self-hosting without Playwright or markitdown is a supported setup.erroris one ofunreachable,timeout,unhealthy(answered200but reports itself broken),http <code>,misconfigured, orpolicy-missing. Deliberately a closed vocabulary: the endpoint is public and must not echo internal hostnames.degraded/policy-missingmeans the Playwright sidecar answers but does not report that it enforces the outbound address policy ("policy": {"ssrf": 1}in its/health). That is apullmd-playwrightimage older than v3.15.2 running next to a newerpullmd: rendering works, but Chromium follows redirects, meta refreshes and iframes into internal hosts (GHSA-26wr-prg5-vr77). Updatepullmd-playwrightto the same release aspullmd. The check only reports; it does not stop renders.- HTTP
200when every configured sidecar isok,503when at least one isdownordegraded, so a plain HTTP check catches it without keyword matching. - Results are cached for 5 seconds and concurrent callers share one round of probes, so polling it cannot amplify into internal traffic.
Why it exists: a broken sidecar does not take PullMD down, it silently degrades extraction quality — pages that need a browser render come back near-empty while everything still answers 200. Without an explicit check that can go unnoticed for a long time.
Uptime Kuma: monitor type HTTP(s), URL https://<your-host>/api/status, accepted status codes 200-299. On an instance with authentication enabled the endpoint stays reachable without credentials.
When the markitdown sidecar is running (set MARKITDOWN_URL=http://markitdown:8003/convert), PullMD can convert document files to Markdown in addition to web pages.
Supported formats: PDF, DOCX, PPTX, XLSX/XLS, EPUB, ZIP (contents listed), CSV, JSON, XML.
Two ways to convert documents:
-
By URL — pass a direct document link to the regular API:
GET /api?url=https://example.com/report.pdfPullMD detects the document content type and routes it through the sidecar automatically.
-
By upload — POST the raw file bytes as the request body (max 25 MB):
POST /api/file
Content-Type: application/pdf        # the file's MIME type
X-Filename: report.pdf               # URI-encoded; or use ?filename=
# body: raw file bytes
The PWA supports both drag-and-drop and a file picker (desktop and mobile) for the same path.
If MARKITDOWN_URL is unset, document conversion is unavailable: a document URL (GET /api?url=…) and POST /api/file both return 502. Regular HTML pages are unaffected, and the PWA hides the document-upload affordance (it reads the markitdown flag from /api/config).
The default docker-compose.yml includes the markitdown sidecar with MARKITDOWN_URL pre-wired. To opt out, remove the markitdown service block and unset the env var.
Image captioning and audio transcription run inside pullmd itself - the markitdown sidecar is not required for media features (it is only needed for document conversion). By default pullmd processes images with EXIF metadata only and audio files with track metadata only - no model calls, no external traffic. Set the relevant PULLMD_VISION_* or PULLMD_STT_* credentials to unlock richer extraction:
- Images - a vision-capable model generates a text caption for each image, embedded in the Markdown output. This applies to image uploads and URLs that point straight at an image; images embedded in a page are not sent to the model, with one exception: the images of Reddit posts, see Embedded images. Enabled when
PULLMD_VISION_API_KEY(or the shared fallbackPULLMD_LLM_API_KEY) is set. - Audio - a speech-to-text model transcribes the audio; the transcript replaces the bare metadata block. Enabled when
PULLMD_STT_API_KEY(or the shared fallbackPULLMD_LLM_API_KEY) is set.
Both modalities are independently configurable via PULLMD_* env vars on the pullmd service:
| Scope | Variables |
|---|---|
| Vision | PULLMD_VISION_API_KEY, PULLMD_VISION_BASE_URL, PULLMD_VISION_MODEL (default gpt-4o-mini) |
| STT | PULLMD_STT_API_KEY, PULLMD_STT_BASE_URL, PULLMD_STT_MODEL (default whisper-1) |
| Shared fallback | PULLMD_LLM_API_KEY, PULLMD_LLM_BASE_URL (used when per-modality key is unset) |
Per-modality vars override the shared LLM_* fallback when set. The fallback deliberately stops at the key and the base URL: a single model name cannot serve captioning, transcription and OCR, so PULLMD_LLM_MODEL does not exist. Set PULLMD_VISION_MODEL / PULLMD_STT_MODEL / PULLMD_PDF_OCR_MODEL instead - if a PULLMD_LLM_MODEL is set anyway, the server says so at startup and the modalities stay on their defaults. Any OpenAI-compatible endpoint works - point *_BASE_URL at a local server (e.g. Ollama, LM Studio) to keep everything on-host and avoid per-call cloud costs.
Note: cloud endpoints send image and audio content to a third-party API. Use a local model server if data-residency matters.
On a Reddit image post the image is often the actual content, and the comments make little sense without it. With a vision provider configured, PullMD can describe each image of a Reddit post (a single image, a gallery, or an image referenced inline in a text post; images in comments are not handled) and transcribe its legible text. The result is placed directly under the image as a blockquote, a short description (one or two sentences) first, then the transcript:

> **[Image description]** Screenshot of a chat with an AI assistant answering a question.
>
> **[Image transcript]**
> ...The labels are Bildbeschreibung / Bildtranskript for lang=de (the default) and Image description / Image transcript for lang=en. This is opt-in because it is the first time PullMD sends images found inside a page to a provider:
PULLMD_EMBEDDED_IMAGES |
Behaviour |
|---|---|
off |
Hard off. images=on has no effect, no image is fetched, no marker is added. |
on-request (default) |
No provider calls unless a request passes images=on (MCP read_url: images: "on"). |
always |
Every Reddit post request transcribes its images, unless it passes images=off. |
- Marker: on an instance with a vision provider and a mode other than
off, an eligible image without a transcript gets a one-line> **[Image not transcribed]**marker (Bild nicht transkribiertforlang=de), so a reader of the output can tell context is missing. Without a vision provider, or withoff, the body is byte-identical to the output before this feature (the one exception: transcripts stored earlier, while a provider was configured, are still shown unless the instance is set tooff). Theimages_transcribed: "<done>/<total>"frontmatter field is set whenever a post has eligible images, whatever the configuration. - Limits: Reddit only. Images are fetched only from
i.redd.itandpreview.redd.it(on every redirect hop, in addition to the SSRF guard), at most 20 MB each, and only if the download is served asimage/*. A single-image post must be a jpg/jpeg/png/webp file; gallery and inline images count when Reddit's metadata marks them as non-animated images. GIFs and videos are skipped. At mostPULLMD_EMBEDDED_IMAGES_MAXimages per post (default 4) are transcribed, and all images of one post share a 90-second deadline. - Cost: each image that is transcribed for the first time uses one unit of the hourly
PULLMD_LLM_RATE_LIMITbudget and one vision call. Transcripts are stored per image: the same image is transcribed once, whichever URL form of the post is requested (old.reddit.com, aredd.itshort link, a/s/share link, tracking parameters), for as long as cache retention keeps it. Any extraction (a cache miss,nocache, a share refresh) reuses stored transcripts without a download, a model call or budget, also for a request that does not ask for images (an instance set tooffignores stored transcripts). Token usage appears as thellm_*frontmatter fields, summed over the images. Withalways, refreshing a share link (/s/:id, which needs no sign-in) can transcribe images that have no transcript yet, charged to the viewer's budget; useon-requestif share links on a sign-in instance should never cause provider calls. - Failures: the post is always returned. An image that cannot work (HTTP 4xx other than 408/429, not an image, over 20 MB, host or SSRF rejection, or a provider answer of 400, 413, 415 or 422) counts as failed for that cached result only: it is not retried while that row is fresh, but it is retried after the row expires or with another URL form of the post. Failures are never stored per image, so one post cannot mark another post's image as failed. Clearing the whole cache forgets the stored transcripts. When an image misses for a transient reason (budget used up, the 90-second deadline, an HTTP 5xx, a DNS failure, any other provider error), the result is served but not cached, and a share refresh keeps the old snapshot and restarts its one-hour refresh clock. Images that did succeed in that request are stored anyway, so a gallery with one failing image keeps the others. A cached row with fewer resolved images than the instance would now produce counts as a miss for an
images=onrequest, sonocacheis not needed. - Security: transcribed text is untrusted third-party content from an image and can contain prompt injection. The labels mark it as machine-derived from the image; treat it like any other fetched page text.
Choosing a vision model. A small comparison from October 2026: nine images from current Reddit posts (chat screenshots, a social media post, two charts, a meme, a photographed menu, a German phone ad, a plain photo), each sent once per model with the prompt PullMD uses (lang=de). Cost is computed from the providers' list prices at the time; nine images are a spot check, not a benchmark.
| Model | Prompt tokens per image | Avg. time | Cost per 1,000 images | Observations |
|---|---|---|---|---|
claude-haiku-5-5 |
~3,100 | 2.1 s | ~$0.48 | Complete transcripts; descriptions name what the image is (e.g. "chat with an AI assistant, question on top, answer below"). |
gpt-4.1-mini |
~3,200 | 2.3 s | ~$1.52 | Complete transcripts; shorter, vaguer descriptions. |
gpt-4o-mini (the default) |
~29,400 | 3.4 s | ~$4.50 | Left out the key figures of a chart, altered source text (fixed a typo, completed a cut-off price), misdescribed one screenshot. |
claude-sonnet-5-5 |
~3,100 | 5.7 s | ~$9.12 | Reference; descriptions slightly more detailed than Haiku's, transcripts the same. |
None of the models said what made the plain photo notable; they do well on screenshots, charts and text, less so on the point of a photo. Claude models work through Anthropic's OpenAI-compatible endpoint without further setup:
PULLMD_VISION_BASE_URL=https://api.anthropic.com/v1
PULLMD_VISION_API_KEY=sk-ant-...
PULLMD_VISION_MODEL=claude-haiku-5-5
The default stays gpt-4o-mini so that existing instances do not change behaviour; set PULLMD_VISION_MODEL to pick another model. The choice applies to all vision captioning, including image uploads.
Provider calls are budgeted: image captioning, audio transcription and PDF OCR share PULLMD_LLM_RATE_LIMIT requests per hour (default 30, 0 = off), counted per signed-in user or, without sign-in, per client address. Over budget the request gets what an instance without the provider returns (metadata only, or the markitdown PDF conversion), and that result is not cached. A tier without a configured provider never consumes budget.
When MARKITDOWN_YOUTUBE=true is set on the pullmd service, YouTube video URLs are routed through the markitdown sidecar instead of the regular web-extraction pipeline. The sidecar fetches the video's title, description, and auto-generated or community transcript, and returns them as clean Markdown. No API key is required.
GET /api?url=https://www.youtube.com/watch?v=dQw4w9WgXcQ
The transcript format is configurable via environment defaults on the sidecar, and can also be overridden per request:
| Query param | Values | Default | Effect |
|---|---|---|---|
?yt_timecodes |
links / plain / none |
links |
links = clickable YouTube timestamp URLs; plain = [MM:SS] labels; none = transcript text only |
?yt_chunk |
integer seconds | 30 |
Groups transcript snippets into blocks of this many seconds. 0 keeps the original per-snippet granularity. |
Both params are also available on the MCP read_url tool.
Language preference: set MARKITDOWN_YT_LANGS=de,en on the sidecar to prefer German transcripts, falling back to English if no German track exists. If none of the preferred languages are available, the sidecar falls back to the first available track.
Rate-limit caveat: YouTube's transcript API aggressively rate-limits requests from datacenter IP ranges. If you run PullMD on a cloud VPS and see frequent failures, set MARKITDOWN_YT_PROXY on the sidecar to route requests through a residential or ISP proxy.
Note: YouTube extraction requires the markitdown sidecar (
MARKITDOWN_URL) to be configured. IfMARKITDOWN_URLis unset, YouTube URLs are processed by the regular web pipeline (HTML extraction via Readability/Trafilatura), which does not include a transcript.
By default, PullMD converts PDFs through the free markitdown path, which works well for text-heavy files but loses complex tables. For table-grade output, enable the opt-in OCR tier:
- Set
PULLMD_PDF_OCR_API_KEYto your OCR provider key (reference provider: Mistral OCR, ~$0.002/page). - Request
?pdf=ocron any PDF URL (also on/api/streamandPOST /api/fileuploads), or setfetch.pdf: ocras a recipe default.
PULLMD_PDF_OCR_API_KEY (and optionally PULLMD_PDF_OCR_BASE_URL) must be set explicitly - unlike vision and STT, PDF-OCR does NOT fall back to the shared PULLMD_LLM_* key, because the OCR endpoint is typically a different provider (Mistral OCR vs. a chat LLM).
On success, source becomes pdf-ocr and the frontmatter gains a pdf_pages field with the page count. If the OCR call fails or no key is configured, pullmd falls back to the standard markitdown conversion automatically - no error is returned to the caller.
Note: the OCR provider charges per page. Check your provider's pricing before enabling this on high-volume instances. OCR requests count against the hourly
PULLMD_LLM_RATE_LIMITbudget described under Media tier.
Self-hosted / heavy local engines (advanced)
PULLMD_PDF_OCR_BASE_URL can point at any endpoint that speaks the Mistral OCR API: pullmd sends POST {BASE_URL}/ocr with {"model": ..., "document": {"type": "document_url", "document_url": ...}} and reads the Markdown from pages[].markdown in the response. Local engines such as Docling have their own API and do not work here directly; wiring one in needs a small adapter in between that translates the request and response. Be aware that such engines are also heavy - a multi-GB container image, and model cold-start times of tens of seconds on first request are typical. This is deliberate: pullmd does not bundle any heavy OCR engine. The reference Mistral OCR path uses a lightweight cloud API call; running a local engine behind an adapter is an advanced operator choice. The OCR tier only handles PDFs; other document types always go through markitdown.
When you request ?frontmatter=true, Reddit, media, and YouTube results include extra fields in the YAML block - post metadata for Reddit, usage fields that let agents compute cost or log telemetry for media. These fields appear only in the frontmatter and are never inserted into the body — without ?frontmatter=true the body is pure content.
| Field | Present when | Description |
|---|---|---|
subreddit |
Reddit post | Subreddit, e.g. r/selfhosted. |
author |
Reddit post (also web pages with author metadata) | Post author, e.g. u/someone. |
published |
Reddit post (also web pages with publish date) | Post creation date (ISO 8601). |
upvotes |
Reddit post | Score at time of extraction. |
images_transcribed |
Reddit post with eligible images | "<done>/<total>": images with a transcript out of the eligible post images, e.g. 1/2. Also present, with 0/N, when no transcript was produced. |
duration |
YouTube | Video duration (humanized, e.g. 12:34 or H:MM:SS). |
views |
YouTube | View count at time of extraction. |
image_size |
Image with caption | Dimensions of the source image: WxH pixels. |
audio_seconds |
Audio transcription | Length of the audio file in seconds. |
llm_model |
Caption or transcription | Model name returned by the upstream API (e.g. gpt-4o, whisper-1). |
llm_tokens |
Caption or transcription | Total tokens consumed (prompt + completion). |
llm_prompt_tokens |
Vision caption | Prompt token count (vision calls only). |
llm_completion_tokens |
Vision caption | Completion token count (vision calls only). |
pdf_pages |
PDF with OCR (source: pdf-ocr) |
Number of pages processed by the OCR provider. |
A few things worth noting:
- PullMD reports no computed cost. Token counts and the model name are what pullmd receives from the upstream API; multiply by the model's per-token rate on your end.
- Image captioning and audio transcription are direct API calls made by pullmd.
- Frontmatter fields for ordinary web pages (
title,url,source,quality, …) are always present when?frontmatter=true; the LLM fields above are additive.
Site recipes are small declarative JSON entries that adjust extraction for specific hosts — force a browser render, strip site-specific noise, unwrap wrappers that confuse the reader, rebuild CSS-grid comparison tables as real tables, or promote structured data (JSON-LD / CSS selectors) into the frontmatter. The built-ins ship in site-recipes.default.json; self-hosters can add their own via data/site-recipes.json or the PULLMD_SITE_RECIPES env var (see .env.example). GET /api/recipes/status reports what loaded.
To write or contribute a recipe, see the site-recipe contributor guide.
server.js— Express app factory (createApp) with dependency injection for tests. Exposes/apiand/api/stream(SSE).lib/reddit.js— Reddit URL normalization, redirect resolution, post + comment extraction.lib/web.js— Orchestrator: Cloudflare-Markdown short-circuit, then static Readability + Trafilatura withpickBest, then optional Playwright re-render + re-extract on body-soup / low-quality output.lib/render-decision.js— Predicate that decides when to fall back to Playwright (readability-fellback + thin, body-soup signature, or quality < 0.5; plusforce/skipoverrides).lib/playwright-client.js— HTTP client for the Playwright sidecar withAbortSignalpropagation for SSE-disconnect cancellation.lib/scoring.js— Quality scoring used to pick between extractors and as a render-trigger heuristic.lib/cache.js— SQLite cache (better-sqlite3) with configurable retention (default 90 days) and 32-hex (128-bit) share ids.lib/mcp.js— Stateless MCP server registering the three tools.lib/distrib.js— Public-URL substitution in/helpand/pullmd.zip.trafilatura-sidecar/— Python sidecar (FastAPI) wrapping Trafilatura.playwright-sidecar/— Python sidecar (FastAPI + Playwright + Chromium) for JS-rendered pages.markitdown-sidecar/— Python sidecar (FastAPI) wrapping MarkItDown for document conversion (PDF, Office, EPUB, …) plus the keyless/youtubetranscript endpoint.lib/markitdown-client.js— HTTP client for the markitdown sidecar (documents + YouTube).lib/youtube.js— YouTube URL detection and normalization.lib/llm/— provider resolver + adapters for image captioning (vision), audio transcription (STT), and PDF OCR against OpenAI-compatible endpoints.lib/frontmatter.js— YAML frontmatter builder with thePULLMD_FRONTMATTER_FIELDSallowlist.lib/coverage-guard.js— detects extractions that kept only a sliver of the page and recovers the container holding the body.lib/query-extract.js— Opt-in query-scoped extraction (?query=): BM25 over heading-based sections of the converted markdown, returning only the relevant sections/blocks. Composeslib/markdown-sections.js(block/section parser) andlib/bm25.js(tokenizer + scorer).public/— PWA frontend (vanilla JS, dark/paper themes, service worker, EventSource client for/api/stream).skill/pullmd/— Claude Code skill source (templated with__PULLMD_URL__).
GNU AGPL v3 — Copyright © 2026 Aeterna Labs.
PullMD is free software: you can redistribute it and modify it under the terms of the GNU Affero General Public License as published by the Free Software Foundation, version 3 or later. If you run a modified version as a network service, you must make your modifications available to its users.