







RapidOCRLite (PyPI RapidOCRLite 5.0.0a6) is the lightweight, fast edition of RapidOCR: a C++ PP-OCRv6 engine with a C ABI, a C++ API, and a Python package whose import name is still rapidocr and whose Python API is fully compatible with RapidOCR. The ONNX Runtime 3.x line (latest tag v3.9.2) stays in RapidAI/RapidOCR. Hosted demos linked from the badges above run that 3.x line.
RapidOCR(params={"Det.model_type": "lite", "Rec.model_type": "lite"}) runs the bundled Indra OCR models from python/src/rapidocr/models/lite/ (about 17.1 MB). Nothing is downloaded.
- Different license. These weights are not Apache-2.0. They use a modified OpenRAIL-M license (see
models/lite/LICENSEandNOTICE), with use restrictions:- Entities with more than USD 20M revenue or funding in the prior year may use them only for personal use or research.
- Entities that offer products or services competing with Datalab may not use them.
- The license also covers the model's Output (paragraph 8).
- Runtime. Fully native: librapidocrlite's C++ kernels run every model and the image preprocessing; the pipeline code is vendored from indra-ocr 0.3.2 (Apache-2.0,
python/src/rapidocr/_indra_vendor/). No onnxruntime, OpenCV or indra-ocr is needed.PPOCR_INDRA_BACKEND=ortruns the upstream onnxruntime pipeline instead, as a test-only reference (installindra-ocr==0.3.2yourself). - Same public API. Differences from PP-OCRv6: boxes are axis-aligned rectangles,
txtscome in reading order, andbox_thresh/unclip_ratiohave no effect.
Six side-by-side samples (printed scan with two columns and a table, dense mixed Chinese/English text, poster, photographed form, street sign, vertical text) are in the Chinese README: README-CN.md, section "lite 与 PP-OCR 效果对照". Each sample shows the original, the detection boxes of PP-OCRv6 small (blue) and lite (red, numbers = reading order), a "redraw" image (recognized text drawn in black at each box position), per-page time and the recognized text. In short: lite reads printed documents in better order and faster; PP-OCR is clearly better on posters, photos, scene text and vertical text.


RapidOCR is an open-source OCR library aimed at small models, offline deployment, and a short path from a PP-OCR weight file to a text box. Version 5 keeps the RapidOCR() call that 3.x applications already use, and runs PP-OCRv6 inside this repository instead of through ONNX Runtime.
The interpreter implements the operators used by the official PP-OCRv6 tiny, small, and medium ONNX detector and recognizer graphs: convolutions, GEMM, pooling, normalization, resize, shape ops, attention matmul, and the DB / CTC post-process. It is a PP-OCRv6 runtime, which means a general ONNX model still needs another engine.
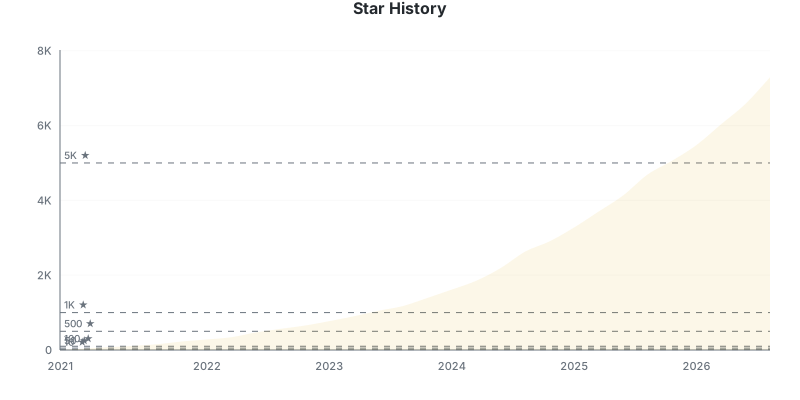
If this project helps your work, a ⭐ Star helps it reach the next person.
- C++ PP-OCRv6 detector and recognizer. The library does not link ONNX Runtime, Paddle Inference, or OpenCV.
- One binary dispatches at runtime to AVX-512, AVX2+FMA, or AArch64 NEON.
PPOCR_FORCE_ISA=scalar|avx2|avx512|neonselects a legal path for measurements. An AVX2-only machine never executes the AVX-512 object file. - LoongArch (loongarch64, Linux): LSX (the la64v1.0 baseline) runs the NEON code paths through
src/neon_lsx_shim.hpp; LASX GEMM (FMA, 4-row), depthwise, GELU, CTC argmax, elementwise, fused ExpandGeluProjectAdd, gated fused depthwise+pointwise 3x3/5x5, and gated fused depthwise+ExpandGelu 3x3 are entered only whengetauxval(AT_HWCAP)reports LASX (PPOCR_FORCE_ISA=lasx|lsx|scalar). Cross-built withcmake/toolchains/loongarch64-linux-gnu.cmakeand verified only under QEMU user mode (CI jobloongarch64 qemu: text identical toexpected_cpu_texts.json, raw scores within about 4e-5 of x86; LASX kernels round in a different order than LSX, so scores can differ from LSX by about 1e-6, text unchanged). No real-hardware benchmarks; CI ships a C/C++ SDK tarball andmanylinux_2_38_loongarch64CPython 3.9–3.13 wheels on the GitHub Release only (PyPI rejects loongarch64 tags); the wheels are install- and OCR-tested under QEMU (Debian loong64) against the x86 reference texts. The Java fat jar also shipsnative/linux-loongarch64/, likewise verified only under QEMU (Debian loong64 OpenJDK; OCR text identical to x86_64). - Optional Vulkan compute. Source builds embed SPIR-V when
third_party/Vulkan-HeadersandglslangValidatorare present (PPOCR_ENABLE_VULKANdefaults toON). The loader isdlopen/LoadLibraryoflibvulkan.so.1orvulkan-1.dll, so Vulkan is not aDT_NEEDEDdependency. Published wheels pass-DPPOCR_ENABLE_VULKAN=OFF. - C ABI (
include/rapidocrlite/rapidocrlite.h), C++ API (include/rapidocrlite/rapidocrlite.hpp), and the Python packagerapidocr. Python calls the C ABI with ctypes. - The Python call shape follows 3.x:
RapidOCR(params={"Section.key": value}), thenresult.txts,result.scores,result.boxes,result.elapse,to_json(),to_markdown(), andvis(). - Missing model files are downloaded from the ModelScope URLs in
default_models.yaml(the same file names as 3.x; PP-OCRv6 files from tagv3.10.0) intoGlobal.model_root_dir, and the SHA256 is checked.

The animation is the RapidOCR 3.x web demo. On this branch the checked line sample is Hello RapidOCR 123 from python/tests/data/hello.png (960×240).

These timings use the PP-OCRv6 tiny ONNX files. The Python default (RapidOCR() with no model paths) is PP-OCRv6 small, the same as 3.x. use_cls=False, so the angle classifier does not run.
| Sample | Size | What it contains |
|---|---|---|
| hello | 960×240 | one line, Hello RapidOCR 123 (python/tests/data/hello.png) |
| page | 1700×2200 | 45 lines. The page file is a local measurement image and is not committed in this repository. |
x86, Python wall clock. 4 vCPU Intel Xeon (family 6, model 207) with AVX2 and AVX-512F/DQ/BW/VL, constant 2.4 GHz, g++ 13.3, Python 3.12. The default pool is 4 threads (min(16, hardware_concurrency)). Forced AVX2 is PPOCR_FORCE_ISA=avx2 in the 5.0.0a1 process; ONNX Runtime 1.30.0 on this CPU stays on AVX-512. Each figure is the median of 8 calls after one warmup. Both packages use the shared Python defaults (config.yaml: short-side limit 736, mean/std 0.5, dilation on). A 960×240 line is enlarged until the short side reaches 736. rapidocr==3.9.2's own published default is PP-OCRv6 small with the classifier left on; that configuration was not timed.
| Package | hello | page |
|---|---|---|
| rapidocr 5.0.0a1, AVX-512 | 105.1 ms | 356.7 ms |
| rapidocr 5.0.0a1, AVX2 | 119.1 ms | 454.7 ms |
| rapidocr 3.9.2 (ORT 1.30.0) | 193.0 ms | 508.3 ms |
Against the 3.9.2 median, AVX-512 hello is 46% faster and the page is 30% faster. Forced AVX2 hello is 38% faster and the page is 11% faster. 3.9.2 was not remeasured for this table; 193.0 ms and 508.3 ms are the earlier back-to-back run. The page text is the same 45 strings on all three rows. Hello is Hello RapidOCR 123. Boxes versus the previous 5.0.0a1 binary have IoU 1.0 on both images.
ARM, C++. 20 cores: 10× Cortex-X925 (up to 3.9 GHz) and 10× Cortex-A725 (up to 2.8 GHz), g++ 13.3, NEON. ppocr_determinism with Backend::cpu_only, 16 threads, and the C++ defaults (long-side limit 960, ImageNet detector mean/std, dilation off). AArch64 recognition widths stay exact.
| ISA | Threads | hello | page |
|---|---|---|---|
| NEON | 16 | 32.7 ms | 222.9 ms |
Determinism passed on both images (1 line and 45 lines).
The older x86 C++ long-side-960 rows and the 1-thread rows are not listed. Repeating ppocr_determinism on this VM after the current kernels moved the AVX-512 page mean across about 203–229 ms from one pass to the next, so those means are not published. RapidOCR() in Python keeps the short-side preprocess in the table above. Set Det.limit_type, Det.limit_side_len, Det.mean, and Det.std when you want the C++ defaults. Earlier kernel notes live in docs/PERFORMANCE.md and are older than this section.
Vulkan page times from earlier adapter checks are not repeated here. Lavapipe on this VM is a software rasterizer, so its milliseconds are not GPU performance. Backend::gpu_only does not fall back to a CPU neural graph.
GPU on Apple silicon: Mac mini, Apple M4 (10 CPU cores 4P+6E, 10 GPU cores, 16 GB), macOS. Vulkan is MoltenVK through the Homebrew Vulkan loader; Metal is the native backend. ppocr_bench, PP-OCRv6 tiny det/rec, 3 warmup runs, median of 20, idle machine; both rounds of an alternating A/B run agreed within 2%. The page is a synthetic 1700×2200 image with 45 text lines, not the screenshot used for the x86 table.
| Image | CPU (NEON, PPOCR_BACKEND=cpu) |
Vulkan (MoltenVK) gpu_only |
Metal (PPOCR_BACKEND=metal) |
|---|---|---|---|
| hello (1 line) | 25.3 ms | 77.4 ms | 11.3 ms |
| page (45 lines) | 210 ms | 672 ms | 107.2 ms |
Metal is about 2× faster than NEON on hello and about 1.85× faster on the page, with text equal to CPU, box IoU 1.0, identical results across 4 threads, and no Metal API validation errors. It replaces the heaviest translated kernels with native MSL ones (simdgroup-matrix GEMMs for pointwise Conv, 3×3 Conv and the recognizer head), runs the DB postprocess on the CPU from the shared probability map, and reuses reclaimed arena slots. Recognition batches up to 8 crops of similar width (widest/narrowest ≤ 1.5) into one graph: each crop keeps its natural width, the padded columns are zeroed before every operator that mixes along the width, SE means divide by each crop's own area and CTC decodes only each crop's own steps, so the text matches the exact-width graphs. This is the default on Metal (PPOCR_DISABLE_GPU_REC_WIDTH_BATCH=1 turns it off; PPOCR_ENABLE_GPU_REC_WIDTH_BATCH=1 enables it on Vulkan, where it is slower on MoltenVK). Before these changes Metal measured 76 ms / 539 ms on the same machine, and 147.6 ms on the page before width batching. The remaining time is mostly GPU arithmetic in the recognizer's pointwise Conv GEMMs (about 1 TFLOPS on M4). PPOCR_METAL_KERNEL_PROFILE=1 with PPOCR_GPU_PROFILE=1 prints GPU time per kernel.
MoltenVK does not report per-dispatch timestamps, so PPOCR_GPU_PROFILE shows only host-side times there. Its text also equals CPU, with 0 validation errors and identical results across 4 threads.
Method follows the open-source OCR model comparison: datasets SWHL/text_det_test_dataset (212 images) and SWHL/text_rec_test_dataset (310 crops) loaded with datasets, metrics from text_det_metric 0.0.8 and text_rec_metric 0.0.1. Detection is det-only (use_det=True, use_cls=False, use_rec=False); recognition is rec-only on the crops (use_det=False, use_cls=False, use_rec=True). Speed is Python wall clock per image after one warmup, one process at a time.
Machine: shared 8 vCPU Intel Xeon (family 6, model 207, KVM) with AVX-512, Python 3.12; other jobs were running on the host (load average 6–10 during the runs), so speed is the median of 5 interleaved runs and is indicative only. M4: Mac mini (10 CPU cores, 16 GB), idle, same method. Metrics below are for the default (exact) mode; fast-mode accuracy is listed under "Recognition fast mode". rapidocr==3.10.0 with onnxruntime 1.31.0 (default intra/inter threads). RapidOCRLite built from source at this commit, native CPU engine (AVX-512, 8 threads). Both use their default models, which are the same PP-OCRv6 small det/rec ONNX files (identical SHA256); RapidOCRLite downloaded them through default_models.yaml. All other settings are the shared config.yaml defaults.
| Dataset | Metric | rapidocr 3.10.0 | RapidOCRLite |
|---|---|---|---|
| text_det | Precision | 0.8540 | 0.8540 |
| text_det | Recall | 0.8445 | 0.8445 |
| text_det | H-mean | 0.8492 | 0.8492 |
| text_det | Speed (s/img, median of 5) | 0.2804 | 0.1345 |
| text_rec | Exact Match | 0.8419 | 0.8419 |
| text_rec | Char Match | 0.9515 | 0.9515 |
| text_rec | Speed (s/img, median of 5) | 0.0063 | 0.0070 |
RapidOCRLite now reproduces 3.10 bit for bit on these sets: besides the DB post-processing (ported cv2.minAreaRect / cv2.fillPoly arithmetic, pyclipper unclip via vendored Clipper 6.4.2) and sorted_boxes, the det input resize, the text-line crop (cv2.getPerspectiveTransform + warpPerspective INTER_CUBIC / BORDER_REPLICATE, including the per-platform float/fp16 bicubic arithmetic) and the rec resize/padding/normalisation (cv2.resize INTER_LINEAR fixed point; on Apple arm64 the KleidiCV path OpenCV uses there) are ported (src/cv_compat.cpp). Result on x86 (AVX-512 and AVX2, both run orders) and M4: 0/212 full-page text differences, 0/310 rec differences, identical metrics; det boxes identical on 211/212 pages on x86 (one page differs in the probability map) and 212/212 on M4. The remaining source of difference is the network arithmetic itself (Lite kernels vs onnxruntime).
Same SWHL sets and settings as above; full is det+rec on the 212 det images (use_cls=False). Interleaved runs, median of 5. The x86 host was shared with other jobs (load 6–10), so treat its numbers as indicative; the M4 rows were measured on the idle machine. exact is the default (output identical to 3.10); fast is Rec.fast_mode: true (see below).
| Host | Mode | rapidocr 3.10.0 | Lite exact (default) | Lite fast |
|---|---|---|---|---|
| x86 8 vCPU, AVX-512 | det-only | 0.2804 | 0.1345 (2.1× faster) | 0.1313 (2.1× faster) |
| x86 8 vCPU, AVX-512 | rec-only | 0.0063 | 0.0070 (1.11× slower) | 0.0067 (1.06× slower) |
| x86 8 vCPU, AVX-512 | full page | 0.3874 | 0.2034 (1.9× faster) | 0.1892 (2.0× faster) |
x86, PPOCR_FORCE_ISA=avx2 |
det-only | 0.2804 | 0.1333 (2.1× faster) | 0.1217 (2.3× faster) |
x86, PPOCR_FORCE_ISA=avx2 |
rec-only | 0.0063 | 0.0092 (1.46× slower) | 0.0085 (1.35× slower) |
x86, PPOCR_FORCE_ISA=avx2 |
full page | 0.3874 | 0.2328 (1.7× faster) | 0.1960 (2.0× faster) |
| Mac mini M4 (CPU, Accelerate) | det-only | 0.1119 | 0.0717 (1.56× faster) | 0.0713 (1.57× faster) |
| Mac mini M4 (CPU, Accelerate) | rec-only | 0.00571 | 0.00505 (1.13× faster) | 0.00503 (1.14× faster) |
| Mac mini M4 (CPU, Accelerate) | full page | 0.2968 | 0.1249 (2.38× faster) | 0.0995 (2.98× faster) |
3.x uses onnxruntime 1.31.0, which on M4 runs its GEMMs on the SME matrix unit; RapidOCRLite reaches the matrix unit through Accelerate (PPOCR_DISABLE_ACCELERATE=1 falls back to NEON). The det-only column does not depend on the mode; its exact/fast difference is run-to-run noise.
By default recognition reproduces 3.10 exactly: lines sorted by aspect ratio, batches of rec_batch_num (6) padded to the widest line, minimum width 320. Fast mode keeps the same crop, resize and normalisation, but runs each line at about its own width (x86 rounds widths up to 32 so similar lines share a batch; AArch64 keeps exact widths). Single-line rec (use_det=False) keeps the 320 minimum, because dropping it cost about 2 points of exact match (PPOCR_REC_FAST_NO_MIN=1 drops it anyway). Text can then differ slightly from 3.10.
- Python:
RapidOCR(params={"Rec.fast_mode": True})orfast_mode: trueunderRec:inconfig.yaml. Other parameters are unchanged. - C API:
rpocr_options.rec_fast_mode = 1(field appended at the end; callers built against an older header pass a smallerstruct_sizeand get 0). C++:rpocr::Options::rec_fast_mode. - Environment:
PPOCR_REC_FAST=1(or0) overrides the option.
Accuracy in fast mode (same sets as above; det is not affected):
| Host | text_rec Exact / Char Match | rec lines differing from 3.10 | full pages with text differing from 3.10 |
|---|---|---|---|
| x86 AVX-512 / AVX2 | 0.8355 / 0.9510 (3.10: 0.8419 / 0.9515) | 9 / 310 | 113 / 212 |
| M4 | 0.8452 / 0.9520 (3.10: 0.8419 / 0.9516) | 4 / 310 | 116 / 212 |
In exact mode both hosts give 0 / 310 and 0 / 212.
The PyPI name of this line is rapidocrlite; the import name stays rapidocr, so code is the same as on main: pip install rapidocrlite, then from rapidocr import RapidOCR. Both distributions install the same rapidocr package directory, so do not install rapidocrlite and the official rapidocr in one environment; run pip uninstall rapidocr first.
5.0.0a6 is a pre-release. It is on PyPI only after a v5* tag is published (see Releasing). Then install it with:
pip uninstall rapidocr   # if the official package is installed
pip install --pre RapidOCRLite
from rapidocr import RapidOCRLoongArch64 (Linux, glibc ≥ 2.38). PyPI does not accept any loongarch64 platform tag yet, so the manylinux_2_38_loongarch64 wheels (CPython 3.9–3.13) are attached to the GitHub Release only, never uploaded to PyPI. They are verified under QEMU user-mode emulation only (no real-hardware testing, no performance numbers). Install one from its release URL; pick the file that matches your Python version and the release tag:
pip install numpy Pillow PyYAML requests tqdm   # or your distro's python3-* packages
pip install https://github.com/RapidAI/RapidOCRLite/releases/download/v5.0.0a13/rapidocrlite-5.0.0a13-cp312-cp312-manylinux_2_38_loongarch64.whl
From a checkout of this branch (CMake ≥ 3.20, a C++20 compiler, and the Python dependencies in pyproject.toml):
pip install .That build follows pyproject.toml: shared librapidocrlite, examples and tests off, Vulkan off. A local wheel is the same build packaged first:
pip wheel . -w dist
pip install dist/rapidocrlite-*.whl
pip install ./python also works from a checkout. It points CMake at the parent tree and does not produce a self-contained sdist. The repository-root pip install . does.
git submodule update --init --recursive
cmake -S . -B build -DCMAKE_BUILD_TYPE=Release
cmake --build build -j
cmake --install build --prefix "$PWD/install"
PPOCR_BUILD_SHARED and PPOCR_BUILD_STATIC default to ON. Turn Vulkan off for a CPU-only library:
cmake -S . -B build -DCMAKE_BUILD_TYPE=Release -DPPOCR_ENABLE_VULKAN=OFFTurn it on for a source package (headers and glslangValidator required):
CMAKE_ARGS="-DPPOCR_ENABLE_VULKAN=ON -DPPOCR_BUILD_STATIC=OFF" pip install .cmake_minimum_required(VERSION 3.20)
project(ocr_app C)
find_package(RapidOCRLite REQUIRED)
add_executable(ocr_app main.c)
target_link_libraries(ocr_app PRIVATE RapidOCRLite::rapidocrlite)The install prefix contains librapidocrlite.so (SONAME librapidocrlite.so.5), headers under include/rapidocrlite/, and lib/cmake/RapidOCRLite/RapidOCRLiteConfig.cmake. Link RapidOCRLite::static (librapidocrlite.a) for the static library. The old find_package(ppocr) / ppocr::ppocr / ppocr::static names still work as compatibility wrappers. At run time the dynamic loader has to see librapidocrlite.so.5 (LD_LIBRARY_PATH or an rpath).
Paths below are the PP-OCRv6 tiny files. With the paths omitted, RapidOCR() downloads the configured default (PP-OCRv6 small, unless Det.model_type / Rec.model_type is tiny).
from rapidocr import RapidOCR

engine = RapidOCR(params={
    "Det.model_path": "PP-OCRv6_det_tiny.onnx",
    "Rec.model_path": "PP-OCRv6_rec_tiny.onnx",
    "Rec.rec_keys_path": "ppocrv6_tiny_dict.txt",
    "Global.use_cls": False,
})
result = engine("hello.png")
print(result.txts)
print(result.scores)
print(result.to_json())
result.vis("vis_result.jpg")
result.boxes is a float32 array of shape (N, 4, 2) in TL, TR, BR, BL order. File paths, URLs, bytes, and PIL images are read as RGB. A numpy ndarray is treated as BGR, matching 3.x OpenCV images, and converted to RGB before the native engine.
Automatic download of the tiny pair (files land in the package models/ directory when Global.model_root_dir is null):
from rapidocr import RapidOCR

engine = RapidOCR(params={
    "Det.model_type": "tiny",
    "Rec.model_type": "tiny",
    "Global.use_cls": False,
})
result = engine("hello.png")
print(result.txts)python -m rapidocr hello.png \
--det PP-OCRv6_det_tiny.onnx \
--rec PP-OCRv6_rec_tiny.onnx \
--dict ppocrv6_tiny_dict.txt \
--model-type tiny--model-type is tiny, small, or medium. The console script rapidocr calls the same main.
#include "rapidocrlite/rapidocrlite.hpp"

#include <iostream>

int main(int argc, char** argv) {
  rpocr::Options options;
  options.backend = rpocr::Backend::cpu_only;
  rpocr::OCR ocr(argv[1], argv[2], argv[3], options);
  for (const rpocr::Result& result : ocr.Recognize(rpocr::LoadPPM(argv[4]))) {
    std::cout << result.text << '\t' << result.confidence << '\n';
  }
}
./ppocr_cpp_api_demo det.onnx rec.onnx dict.txt image.ppmImages passed to the library are packed RGB, row-major, 8-bit. LoadPPM reads binary P6. JPEG and PNG decoding stays in the application (Pillow does it for Python).
#include "rapidocrlite/rapidocrlite.h"

#include <stdio.h>

int main(int argc, char** argv) {
  rpocr_options options;
  rpocr_options_init(&options);
  options.backend = RPOCR_BACKEND_CPU;

  rpocr_ocr* ocr = rpocr_create(argv[1], argv[2], argv[3], &options);
  rpocr_image_buffer loaded = {0};
  if (rpocr_load_ppm(argv[4], &loaded) != RPOCR_OK) return 1;

  rpocr_image image = {loaded.width, loaded.height, loaded.rgb};
  rpocr_result result = {0};
  if (rpocr_recognize(ocr, &image, &result) != RPOCR_OK) {
    fprintf(stderr, "%s\n", rpocr_last_error());
    return 1;
  }
  for (size_t i = 0; i < result.count; ++i) {
    printf("%s\t%.4f\n", result.items[i].text, result.items[i].confidence);
  }
  rpocr_result_free(&result);
  rpocr_image_free(&loaded);
  rpocr_destroy(ocr);
  return 0;
}
rpocr_recognize on one handle is serialized. Create one handle per thread when pages should run together. rpocr_options.struct_size is filled by rpocr_options_init so later fields can be appended.
Wheels are CPU-only. A Vulkan-enabled build selects the device in the same place 3.x puts use_cuda:
engine = RapidOCR(params={
    "Det.model_path": "PP-OCRv6_det_tiny.onnx",
    "Rec.model_path": "PP-OCRv6_rec_tiny.onnx",
    "Rec.rec_keys_path": "ppocrv6_tiny_dict.txt",
    "Global.use_cls": False,
    "EngineConfig.ppocr_cpp.use_vulkan": True,
    "EngineConfig.ppocr_cpp.device_index": 0,
})
result = engine("hello.png")
print(result.txts)
device_index -1 skips CPU Vulkan devices such as lavapipe. Set the index (or PPOCR_VULKAN_DEVICE_INDEX) when lavapipe is the device you want, and point VK_ICD_FILENAMES at its ICD. If no compute device exists, Python logs a warning and stays on CPU. backend accepts cpu, hybrid, or vulkan.
In C++ the default Backend::hybrid stays on CPU unless PPOCR_ENABLE_HYBRID_GPU_GRAPH is set. Backend::gpu_only throws std::runtime_error when the device or a shader cannot run. The C ABI returns RPOCR_ERR_UNSUPPORTED from rpocr_create in that case.
rpocr::Options options;
options.backend = rpocr::Backend::gpu_only;
options.vulkan_device_index = 0;  // -1: automatic; CPU/lavapipe are skipped
rpocr::OCR ocr(det, rec, dict, options);
One recorded command buffer can drop CTC timesteps on some adapters. The default GPU path submits fenced segments. PPOCR_ENABLE_GPU_GRAPH_REPLAY=1 opts into the single command buffer after that adapter has been qualified.
On macOS, source builds include a native Metal backend (PPOCR_ENABLE_METAL, default ON on Apple; needs glslang and spirv-cross, e.g. brew install glslang spirv-cross). It runs the same GPU graph and fused kernels as Vulkan, translated to MSL at build time, with weights resident in shared-storage MTLBuffers. No Vulkan loader or MoltenVK is needed. Native MSL kernels (src/metal_native_kernels.hpp) replace the pointwise Conv, 3×3 Conv and row-GEMM modes; PPOCR_METAL_DISABLE_NATIVE=1 falls back to the translated kernels, and PPOCR_METAL_DEVICE_DB_POSTPROCESS=1 keeps the DB postprocess on the GPU. Width-batched recognition is described in the Apple silicon benchmark notes above.
engine = RapidOCR(params={
    # model paths as above
    "EngineConfig.ppocr_cpp.backend": "metal",   # or "use_metal": True
})
rpocr::Options options;
options.backend = rpocr::Backend::metal; // rpocr::MetalAvailable() reports supportIn C, set RPOCR_BACKEND_METAL; rpocr_metal_available() reports support. Without Metal (other platforms, a build without it, PPOCR_DISABLE_METAL=1) all three fall back to CPU and do not fail. The driver is chosen once per process: Metal and Vulkan do not mix in one process. ppocr_metal_check compares Metal to CPU and runs a multithreaded determinism check; tests/run_metal_macos.sh runs it under Metal API validation (MTL_DEBUG_LAYER=1).
Python keys use the 3.x Section.name form. A YAML config_path is loaded with PyYAML and then overridden by params.
| Key | Role |
|---|---|
Det.model_path, Rec.model_path, Rec.rec_keys_path |
Local ONNX files and the recognizer dictionary. Omitted paths are downloaded. |
Det.model_type, Rec.model_type |
tiny, small, or medium inside the PP-OCRv6 URL table. |
Det.ocr_version, Rec.ocr_version |
PP-OCRv6. Older version names raise NotImplementedError. |
Det.limit_side_len, Det.limit_type |
Resize limit. min matches 3.x (short side). max is the C++ long-side default. |
Det.thresh, Det.box_thresh, Det.unclip_ratio |
Detector mask threshold, box score, and unclip. |
Det.mean, Det.std |
Detector normalization, BGR order, length 3. |
Det.use_dilation |
2×2 dilation of the detector mask. On in the Python config, off in rpocr::Options. |
Global.text_score |
Drop lines below this score. Also a per-call argument. |
Global.use_cls |
Accepted. The native engine does not run an angle classifier and warns once. |
Global.model_root_dir |
Download directory. The package models/ directory when null. |
Rec.rec_batch_num |
Recognizer batch size. |
EngineConfig.ppocr_cpp.use_vulkan |
Request the Vulkan graph. |
EngineConfig.ppocr_cpp.device_index |
Vulkan device. -1 skips lavapipe. |
EngineConfig.ppocr_cpp.use_metal |
Request the Metal graph (macOS); CPU otherwise. |
EngineConfig.ppocr_cpp.backend |
cpu, hybrid, or vulkan. |
C++ defaults live on rpocr::Options in include/rapidocrlite/rapidocrlite.hpp (det_limit_side_len 960, det_limit_type 0, ImageNet det_mean / det_std, rec_batch_size 4). PPOCR_BENCH_THREADS overrides the persistent SIMD pool (default min(16, hardware_concurrency)).
RapidOCR(config_path=..., params={"Section.key": value}) and
engine(img, use_det=..., use_cls=..., use_rec=..., text_score=..., box_thresh=..., unclip_ratio=...)
keep the same names. result.txts, result.scores, result.boxes, result.elapse, to_json(), to_markdown(), and vis() are still there.
3.x (main, through v3.9.2) |
rapidocr 5 |
|---|---|
| ONNX Runtime, OpenVINO, Paddle, PyTorch, TensorRT, MNN | Built-in PP-OCRv6 interpreter. EngineType.ONNXRUNTIME and EngineType.PPOCR_CPP both select it. Other engine names raise NotImplementedError. |
| PP-OCRv4 and PP-OCRv5 model zoo | PP-OCRv6 ONNX detector and recognizer. |
Angle classifier (use_cls=True by default) |
The cls file is still downloaded when use_cls is true. The native engine ignores it and logs one warning. |
use_det=False or use_rec=False |
Supported as on 3.x: use_rec=False returns TextDetOutput (boxes, DB scores); use_det=False returns TextRecOutput for the whole image. Both False raises RapidOCRError. These modes run on the CPU graph, also with backend: metal (Metal keeps the full pipeline); the strict Vulkan GPU backend rejects them. Per-call arguments are stored on the engine and stay in effect for later calls, as in rapidocr 3.x main. |
| Word and character boxes | return_word_box / return_single_char_box warn. word_results is empty. |
elapse_list is [det, cls, rec] |
[None, None, total]. An empty page is RapidOCROutput() (boxes / txts / img are None). |
vis() draws with OpenCV in BGR |
vis() draws with Pillow and returns RGB. |
EngineConfig CUDA, OpenVINO, TensorRT, MNN, … |
Those keys load and can be read. They are not applied. Vulkan keys above are applied. |
A caller that only reads txts, scores, and boxes from a PP-OCRv6 model can switch by installing this package. Set use_cls=False to skip the warning. Do not pass an older OCR version.
There is no 4.x tag in this repository. Details and the C ABI are in docs/API.md and python/README.md.
- No direction classifier.
use_clsdoes not rotate boxes. - No per-word or per-character boxes.
word_resultsstays empty. - The native engine runs PP-OCRv6 ONNX graphs. PP-OCRv4 / v5 files are not executed.
- GPU-only mode has no CPU neural fallback. Hybrid stays on CPU unless
PPOCR_ENABLE_HYBRID_GPU_GRAPHis set. - Published wheels do not contain Vulkan shaders.
- C / C++ / Python API
- CPU performance notes (kernel history; the table above is the later rerun)
- Python package notes
- 3.x documentation site (Chinese,
main)
One workflow, .github/workflows/build-wheels.yml, builds the SDK archives, the Python wheels/sdist and the Java fat jar on every push to main; an annotated v5* tag publishes them: wheels and sdist to PyPI, SDK archives (incl. linux_loongarch64), wheels (plus the GitHub-only loongarch64 wheels) and the jar to that tag's GitHub Release. The steps, the trusted-publisher settings, and the tag command are in docs/RELEASING.md.
👥 Who use? (more)
Projects that depend on the rapidocr package include Docling, CnOCR, Umi-OCR, and LangChain. The 3.x line on main is what those releases install today. Register a new dependent at discussion 286.
- PaddleOCR for the models and the OCR pipeline this engine implements.
- PaddleOCR2Pytorch and PaddleX for the conversions and document models used by the wider RapidOCR project.
- Everyone listed on the contributors graph.
RapidOCR is an Apache-2.0 project. Sponsorship is described on the 3.x docs site.
| Sponsors | Application | Introduction |
|---|---|---|
 |
Quicker | Your fingertip toolbox |
@misc{RapidOCR 2021,
    title={{Rapid OCR}: OCR Toolbox},
    author={RapidAI Team},
    howpublished = {\url{https://github.com/RapidAI/RapidOCR}},
    year={2021}
}
RapidOCR source code is copyright RapidOCR Authors and licensed under the Apache License, Version 2.0 (license = "Apache-2.0" in pyproject.toml and python/pyproject.toml). The license text is at apache.org/licenses/LICENSE-2.0.
The OCR model files are derived from official PaddleOCR models. Copyright in the upstream weights is held by Baidu and/or the respective PaddleOCR rights holders. Those upstream models are distributed under the Apache License, Version 2.0. RapidOCR does not claim ownership of the upstream weights.