A local code map for AI coding agents: find the right file, trace how it connects, predict what a change breaks.
Works with Claude Code, Codex CLI, OpenCode and any MCP client. Runs on your machine. Sends nothing anywhere.



Try it · Why · Find / Trace / Predict · Agents · Evidence · Contribute
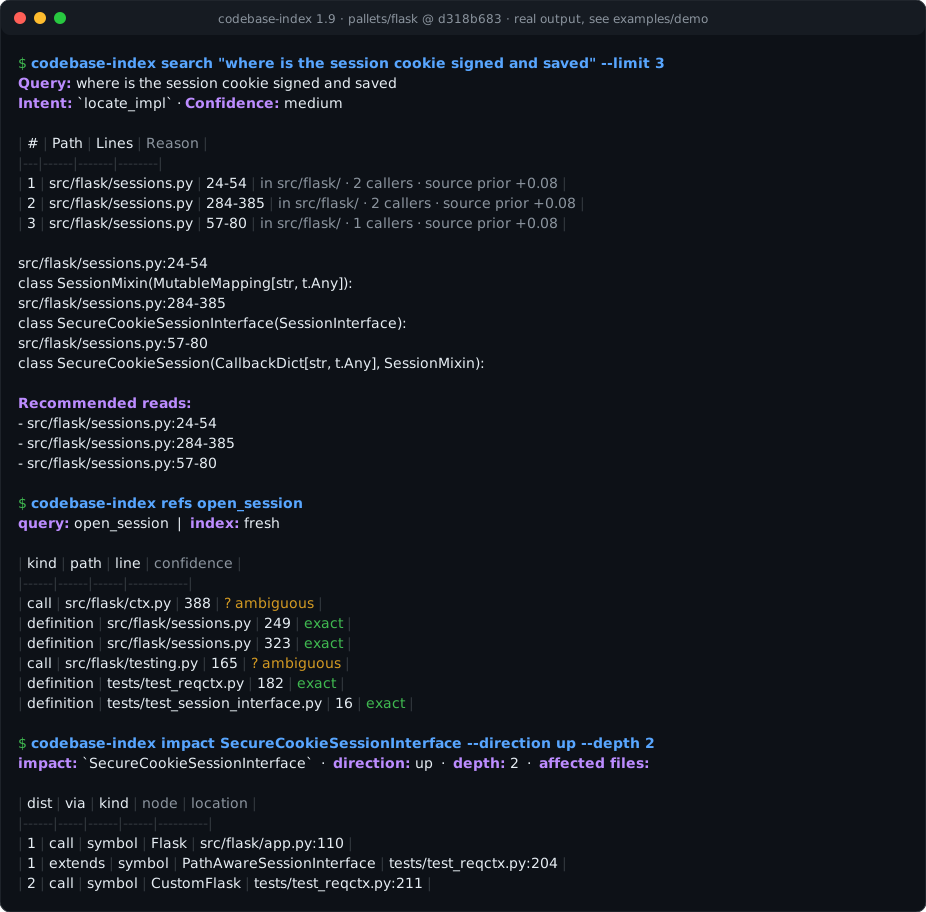
Real output on pallets/flask. Reproduce it with examples/demo.
pip install codebase-index
cd your-project
codebase-index index                                   # a few seconds for ~250 files
codebase-index search "where is the session cookie signed"
codebase-index impact SessionInterface --direction up  # what depends on it
codebase-index init                                    # wire it into Claude Code / Codex / OpenCode
That is the whole setup. The index is a SQLite file under .claude/cache/, the
skill tells your agent to query it before reading files, and codebase-index doctor
tells you if anything is off.
Claude Code and Codex can already read files. The problem is deciding which files. On a repository with a few hundred files an agent that greps for keywords opens the wrong file more often than the right one, then reads whole files to compensate. That costs tokens, time, and, worst of all, wrong answers delivered with confidence.
codebase-index gives the agent a ranked, evidence-bearing answer to three questions
before it opens anything:
| Question | What comes back | |
|---|---|---|
| Find | Where is X implemented? | Ranked file:line ranges, a reason for each rank, and a bounded read plan |
| Trace | What calls this? How does A reach B? | Definitions vs references, shortest dependency paths, each edge tagged extracted / inferred / ambiguous |
| Predict | What breaks if I change this? What does my diff touch? | Upstream and downstream dependents by distance, with graph-coverage honesty |
Every answer carries its own uncertainty: index freshness, result confidence, and whether the graph is partial for a language. The agent can tell "nothing references this" from "the graph doesn't know", which grep never can.
How it differs from what you already have
- grep / ripgrep: exact text, no ranking, no notion of definition vs call, no dependency graph. Use it when you know the string. Use this when you know the question.
- Repo-map style context (Aider and friends): a signature listing pushed into every prompt. Good orientation, query-agnostic, and it must fit in the budget. This is a queryable index instead: per-question ranking, line ranges, graph traversal, and a stable JSON/MCP contract any agent can call.
- Cloud code search / IDE indexing: powerful, but your code leaves the machine or you adopt an IDE. This is a small Python package on SQLite and Tree-sitter: no server, no account, no telemetry.
The comparison guide says when each of those is the better choice.
All examples below are real output on Flask at commit d318b683; see
examples/demo/EXPECTED_OUTPUT.md for the full transcript.
Find the implementation, not a keyword hit:
$ codebase-index search "where is the session cookie signed and saved" --limit 3
| # | Path                    | Lines   | Reason                                       |
| 1 | src/flask/sessions.py   | 24-54   | in src/flask/ · 2 callers · source prior +0.08 |
| 2 | src/flask/sessions.py   | 284-385 | in src/flask/ · 2 callers · source prior +0.08 |
| 3 | src/flask/sessions.py   | 57-80   | in src/flask/ · 1 callers · source prior +0.08 |
Trace references with confidence, and paths between symbols:
$ codebase-index refs open_session
| kind       | path                       | line | confidence  |
| call       | src/flask/ctx.py           | 388  | ? ambiguous |
| definition | src/flask/sessions.py      | 249  | exact       |
| definition | src/flask/sessions.py      | 323  | exact       |

$ codebase-index path wsgi_app dispatch_request
wsgi_app (src/flask/app.py) → full_dispatch_request → dispatch_request   · 2 hop(s)
Predict the blast radius of a symbol, or of the diff you have right now:
$ codebase-index impact SecureCookieSessionInterface --direction up --depth 2
| dist | via     | node                      | location                  |
| 1    | call    | Flask                     | src/flask/app.py:110      |
| 1    | extends | PathAwareSessionInterface | tests/test_reqctx.py:204  |
| 2    | call    | CustomFlask               | tests/test_reqctx.py:211  |

$ codebase-index diff-impact          # after editing src/flask/sessions.py
affected files (8): src/flask/app.py, src/flask/ctx.py, src/flask/globals.py, ... (edge kind + confidence per row)
More: explain "how are blueprints registered", describe dispatch_request,
architecture (modules, god nodes, surprising links), graph User --output graph.html.
Add --json to any command for the machine-readable packet.
| Agent | Setup | What it gets |
|---|---|---|
| Claude Code | codebase-index init --target claude, or the plugin: /plugin marketplace add denfry/codebase-index then /plugin install codebase-index@codebase-index |
A skill that routes repository questions to the index and reads only recommended_reads ranges; optional PostToolUse hook keeps the index fresh |
| Codex CLI | codebase-index init --target codex |
A managed block in AGENTS.md plus the skill resources |
| OpenCode | codebase-index init --target opencode |
/codebase-index command, agent file, skill resources |
| Any MCP client (Claude Desktop, Cursor, VS Code, Zed, Windsurf, ...) | pip install "codebase-index[mcp]" then codebase-index mcp --root /path/to/repo |
11 tools (search_code, find_refs, impact_of, impact_of_diff, path_between, ...) with a versioned JSON envelope |
| Anything with a shell | codebase-index --json ... |
The same payloads as plain JSON, plus a local SQLite database you can query yourself |
init --target auto detects which of these are present. See
INSTALLATION.md and MCP.md.
Numbers below come from runs whose raw logs are in this repository. Nothing here is a claim about tools we have not benchmarked.
Index vs a disciplined grep agent, on public repositories. Three repos at pinned commits (Flask, Gson, Fastify), 450 questions mined from git history (commit subject → files that commit changed, so neither side wrote the answer key), the same tokenizer charging both sides for what enters context:
| pooled, n = 450 | hit@3 | MRR | context tokens / question |
|---|---|---|---|
| codebase-index | 0.547 | 0.456 | 3,835 |
rg + 80-line windows |
0.304 | 0.263 | 3,495 |
Every delta is significant at p < 0.001 (paired bootstrap CI in the log). Read it as:
1.8× more likely to put the answer in the top three, at about 10% more context.
Reproduce with python tests/eval/run_baselines.py --clone; details, caveats and the
repo-map-style comparison are in BENCHMARKS.md.
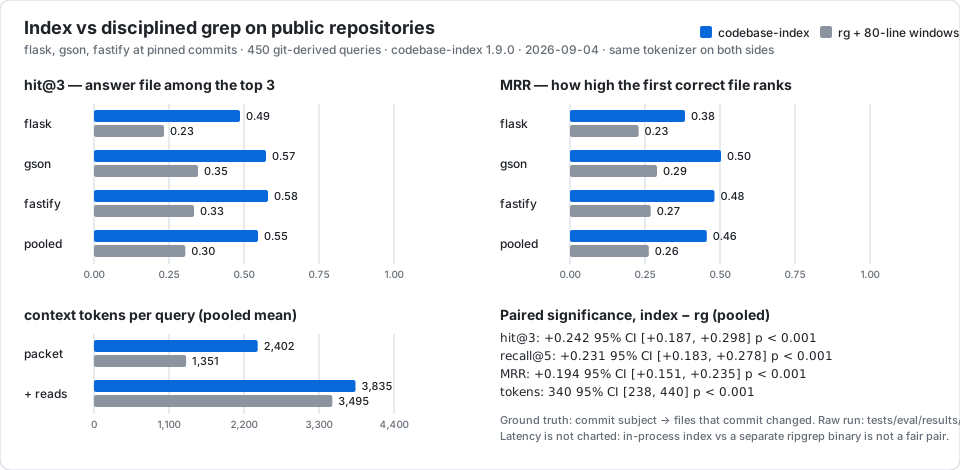
Every ranking signal is ablated. A change to the ranker ships only if it is significant on a pooled multi-language query set (tests/eval). 1.9.0 removed two signals that could not show a benefit and rejected five plausible ones.
What is not measured yet: whether an agent completes tasks better with the index. That needs model calls and a rubric and is the top item in BENCHMARKS.md. Please do not quote task-success numbers for this project; there are none.
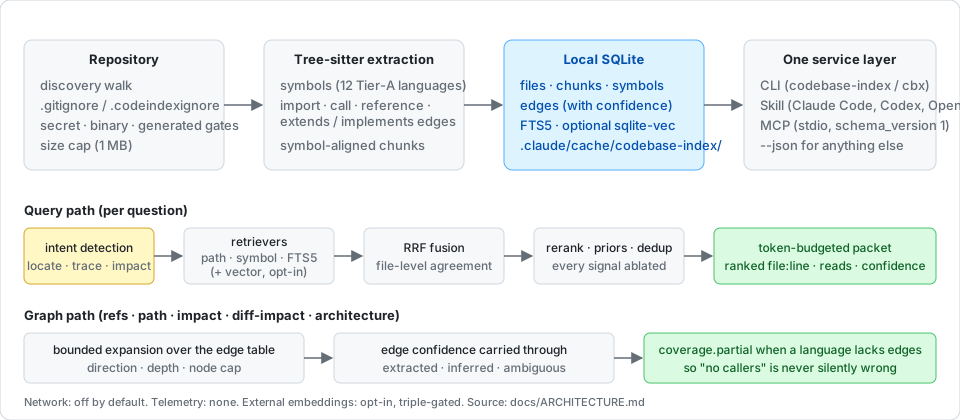
Indexing walks the repository through ignore and secret gates, extracts symbols and import/call/reference/inheritance edges with Tree-sitter for 12 languages, and stores chunks, symbols and edges in one SQLite file with FTS5. A query goes through intent detection, path/symbol/FTS retrievers (vector is opt-in), reciprocal-rank fusion that rewards cross-retriever agreement on a file, a rerank with calibrated source priors, and a token budget that emits ranked ranges plus a bounded read plan. The CLI, the installed skills and the MCP server all call the same service layer, so behaviour cannot drift between surfaces.
Deep dives: Architecture · Retrieval · Evidence memory · Schema · Languages · Skill design
- No network by default. The base install has no network dependency and makes no requests. There is no telemetry, no crash reporting, no usage counter.
- Secrets never get in.
.env*, keys, certificates, credential files, binaries, dependency and build directories, generated and oversized files are excluded before parsing;.gitignore,.codeindexignore,.claudeignoreand.cursorignoreare honoured. - Secrets never get out. Snippets are redacted again at output time (AWS keys, private-key blocks, JWTs, connection strings, Slack tokens, high-entropy values).
- One opt-in exit, triple-gated. External embeddings require an explicit config flag, an API key in the environment, and a printed endpoint warning, or they are refused. Local embeddings stay local.
- Verify it yourself.
codebase-index doctor --strictaudits the gates and exits non-zero in CI if one is off.
Details and residual risks: SECURITY_MODEL.md. Report vulnerabilities privately: SECURITY.md.
Symbol and graph extraction (Tier A): Python, JavaScript, TypeScript, Java, Go, Rust,
C, C++, C#, Ruby, PHP, Kotlin. Generic Tree-sitter definitions (Tier B): Lua.
Full-text search for everything else that is text, including Markdown, YAML, JSON,
TOML, SQL, Dockerfiles, Terraform and CI configs. refs and impact report
coverage.partial when a language has no graph edges, so an empty result is never
silently presented as "no callers". Tiers and how to add a language:
LANGUAGES.md.
Current line: 2.0.x, on PyPI, MIT. CI runs Linux, macOS and Windows on Python 3.11–3.13 with an 80% coverage gate, golden snapshots for every CLI and MCP payload, a packaging smoke test on every PR, and a skill-copy drift check.
What works today: hybrid retrieval with optional local vectors; Tree-sitter symbols
and edges; search, explain, symbol, refs, impact, diff-impact, path,
describe, architecture, graph, verify; token-budgeted, skeletonized packets;
evidence memory that withholds byte-identical snippets within a session and reports
evidence that changed; incremental update, watch, and hooks; CLI, Claude Code plugin/skill, Codex, OpenCode and
MCP delivery; a reproducible multi-repository benchmark.
What does not exist yet: framework-aware typed edges (routes, DI, migrations), multi-repository workspaces, paged MCP results, an agent task-level benchmark, signed release artifacts. See the roadmap.
Fifteen minutes from clone to a first PR: docs/DEVELOPMENT.md. Where help is most useful: benchmark reproductions on your own repositories, new Tier-A languages, graph edge kinds, and MCP client verification. Labels and the retrieval-quality PR rules are in CONTRIBUTING.md.
pip install -e ".[dev,mcp]"
pytest && ruff check src tests && mypy src/codebase_index
python tests/eval/run_eval.py --ablate # required for any ranking changeNext: verified MCP client configs and paged results; an agent task-level evaluation; a large-monorepo benchmark run; then framework-aware typed edges behind a hand-labelled graph benchmark. Full list with the "not a claim until it ships" rule: docs/ROADMAP.md. History: CHANGELOG.md.