
Not a copilot. A crew of autonomous agents that understand, navigate, and evolve your codebase — together.
English: README.md · 中文:README_zh.md
Most AI coding tools share a fundamental flaw: they treat code as text, not structure — and they treat context as infinite, when it is the scarcest thing you have.
| Traditional Tools | Yagent |
|---|---|
| Flat text pattern matching | 🧠 Structural code understanding — AST + call graphs + hybrid retrieval |
| Single agent, working alone | 🤖 Hub-and-Spoke multi-agent: Director orchestrates, six specialists execute |
| Static capabilities | 🧬 Meta-Agent: designs & registers new agents at runtime — the system evolves |
| Keyword-only search | 🔍 Natural-language semantic search — "find where auth logic is implemented" |
| Every tool schema sent on every step | 🗂️ Deferred tool schemas: cold tools ship as name + one-line brief; the model fetches the schema when it actually needs it |
| Long sessions silently degrade | 🗜️ Three-tier context compression + a cross-agent note board, so conclusions stay addressable instead of being re-derived |
| One model for everything | 🎯 Benchmark-scored auto-routing: fast / balanced / high, picked per sub-task |
| "Trust me, it compiles" | ✅ Forced delegation, design gate, git checkpoints, activity-aware timeouts, and /resume from durable rollout logs |
| Agent | Role | Permissions | Default Max Steps |
|---|---|---|---|
| 🎼 Director | Orchestrator — the only agent that talks to you. Decomposes, delegates, reviews | Read-only + delegation | 100 |
| 🔬 Repo-Agent | Code archaeologist / auditor — AST, semantic search, call graphs, impact analysis | Read-only, may delegate DevOps | 50 |
| ✏️ Coding-Agent | Staff engineer — edits, shell, design & reflection tools, self-correction | Full read/write + shell | 150 |
| 🌐 Browser-Agent | Drives real Chrome for docs, issues, Stack Overflow, and live web verification | 14 browser tools + its own workspace (no shell, no file writes) | 200 |
| 🔧 DevOps-Agent | SRE — shell execution, environment diagnostics, process management | Read-only + shell | 50 |
| 💬 Chat-Agent | Technical advisor — Q&A and explanations with no filesystem access at all | None | 50 |
| 🧬 Meta-Agent | Agent factory — designs a new agent as JSON, it is registered and runs immediately | Single-shot, tool-less | 50 |
| 🎛️ Custom Agents | Runtime products of the Meta-Agent (e.g. delegate_security_auditor) |
Capability subset chosen by the LLM | 15 |
Authority is not a suggestion in a prompt — it is derived. Each agent declares a capability profile (a bitmask of allowed effects), and its tool surface is computed from the central registry. Add a tool and it appears wherever its capability is granted; forget one and startup validation fails loudly instead of the tool silently vanishing.
        TUI (Bubble Tea v2)  ·  HTTP + WebSocket  ·  --prompt
                              │
                   ┌──────────┴──────────┐
                   │    🎼 Director      │  Planner · Thought & Plan journal
                   │  (orchestrator)     │  · circuit breaker · review
                   └──────────┬──────────┘
     ┌────────┬────────┬──────┴──────┬─────────┬─────────┐
   🔬 Repo  ✏️ Coding  💬 Chat    🔧 DevOps  🌐 Browser  🧬 Meta
   read-only  write+    no fs     read+      real        designs →
   + graph    shell     access    shell      Chrome      registers
     └────────┴────────┴──────┬──────┴─────────┴─────────┘
                              │
        every result becomes  ┤  📝 a Blackboard note (structured handoff,
                              │  derived index)  ·  🪨 an offloaded artifact
                   ┌──────────┴──────────┐
                   │    ENGINE LAYER     │  🧩 Tool Registry — 50 tools, capability
                   │                     │    profiles, deferred schemas (load_tool)
                   │                     │  🎯 Model Router — fast / balanced / high,
                   │                     │    scored from a 478-model benchmark catalog
                   │                     │  🗜️ Three-Tier Compression ← 🧠 Thinklink
                   │                     │  📼 Rollout JSONL → /resume
                   └──────────┬──────────┘
                              │  MCP stdio (6 tools)
              🦀 codeseek — Tree-sitter AST · Petgraph call graph
                 · LanceDB dense · Tantivy BM25 · RRF · cross-encoder
The Repo-Agent is backed by codeseek — a Rust engine (git submodule, shipped inside the Go binary, called over MCP stdio) that understands code like a senior engineer.
- 25 Tree-sitter language IDs, with function/class extraction and call-graph edges verified for Rust · Python · JS · TS · Go · C/C++ · Java
- Call graph analysis via Petgraph: who calls this, what breaks if I change this, depth-limited graph traversal, and code skeletons — so an agent reads a module's shape instead of opening every file
- Six tools bridged over MCP:
semantic_search,query_code_skeleton,query_code_snippet,find_function_caller,find_function_callee,query_call_graph - Auto-indexing: file watcher with 2s debounce keeps the model in sync while you edit
- Graceful degradation: no embedding API, no reranker, or index still building → the engine falls back to graph-based name search and the agents fall back to file tools. Never a hard failure.
User Query
    ├─→ Stage 1 · Hybrid Search (dual-channel recall)
    │     ├── 🧠 Dense : LanceDB ANN (default Qwen3-Embedding-4B, 2560-dim, configurable)
    │     ├── 🔤 Sparse: Tantivy BM25 with a custom CodeTokenizer (snake_case / CamelCase)
    │     └── 🔗 RRF   : Reciprocal Rank Fusion merges both channels
    ├─→ Stage 2 · Code Graph Expansion
    │     └── PetCodeGraph BFS from seed symbols → callers/callees, restoring architectural position
    └─→ Stage 3 · Cross-Encoder Rerank
          └── Optional Qwen3-Reranker scoring of each (query, code) pair
| Pure Vector Search | Yagent Hybrid + Graph Expansion | |
|---|---|---|
| Recall | ❌ Semantic matches with different wording → missed | ✅ BM25 + dense dual channel |
| Precision | ❌ Short noisy snippets rank high | ✅ RRF + short-code penalty + cross-encoder |
| Context | ❌ Isolated snippets, no call relationships | ✅ Call chains expanded automatically |
| Code-aware | ❌ Generic tokenizers | ✅ CodeTokenizer for code naming |
| Robustness | ❌ Single point of failure | ✅ Three independent degradation paths |
Declaring all fifty tools in full costs the model several thousand tokens of boilerplate on every single step — and the agent needs maybe a dozen of them per task. Yagent tiers every tool as Hot / Warm / Cold:
- Hot tools carry their full JSON Schema every step (flow control and the tools an agent uses constantly).
- Cold tools appear only in a Deferred tools catalog in the system prompt —
name: one-line brief. - When the model wants one, it calls
load_toolwith up to 8 names batched, gets the real parameter schema, and proceeds. Skip that step and the system doesn't reject it as hallucination — it hands back the schema once, as a teaching fallback. - A per-step declaration budget (default 2500 tokens,
[tools.deferred.budget_tokens]) demotes oversized tools to Cold automatically, and[tools.deferred.hot] / [cold]let you retune tiers by name without recompiling. /resumerestores which schemas were already materialized, so a recovered session doesn't pay the round-trip again.- One switch (
disable = true) returns to the old all-schemas-always behavior — kept honest for A/B debugging.
Every step is checked against a budget derived from an embedded catalog of 478 models (context × 0.75; no catalog hit falls back to your configured threshold).
- Tier 1 — Rule: truncate tool results by value priority (cognitive results like
deepthinking/designare protected), keeping the most recent ones intact. - Tier 2 — Emergency: extract Thought & Plan blocks into the thinklink journal, keep the last 3 verbatim, LLM-summarize the rest, and rewrite memory as
[system, one user]. - Tier 3 — Ultimate: rebuild the working context from the thinking journal, keep the most recent plans, then hard-truncate to budget.
All three emit events and rollout records, and the TUI shows exactly what each tier bought you: per-tier saved tokens, percentage, a context trend sparkline, and a leaderboard of which tools got cut. One renderer, one accounting rule — so the sidebar, the bottom bar, and the collapsed row can never disagree.
When a sub-agent finishes, its result is written as a note with a structured handoff — conclusion, verifiable facts[] (each with a where: file:line, symbol, URL), open_questions, status — and large deliverables are offloaded to disk as artifacts, leaving a summary plus an ID in context.
An index of every note is injected into each Director turn and each delegation prefix, and context_refs lets the Director say "build on what Repo already found":
delegate_coding(task = "implement the fix",
                context_refs = ["agent:repo", "artifact:20261014-093012-a1b2c3d4"])
The index is derived state, rebuilt from disk and never persisted into session memory — which is precisely why compression can't evaporate it. Read-back is three tools: read_note (handoff + paged body), read_artifact (paged full text), list_notes (board directory). Boards are session-scoped, so a /resume picks up the same notes instead of re-exploring the repo from zero.
Point Yagent at several providers and it sorts them for you. The embedded model catalog carries benchmark results; routing scores each candidate (ai_score over the strict benchmark intersection, weighting DeepSWE / SWE-Bench Pro / GPQA Diamond at 1.5×) and picks three tiers from your own pool — highest, median, lowest. If fewer than three configured models share benchmark data, routing disables itself with the reason printed instead of guessing.
Then a fast model classifies every sub-task as fast / balanced / high: run a command and read a log → fast; ordinary coding and retrieval → balanced; architecture, planning, subtle debugging → high. Per-agent baselines override the default tier ([routing.baselines] coding = "high"), a failed classification falls back to the baseline rather than blocking the task, and alt+r / :route flips modes live with the chosen model and score shown in the TUI.
Provider selection is three-level — tool → agent → global — so micro_agent can run locally while the Director runs your frontier model. Both wire formats are first-class: api_format = "openai" and "anthropic" (native Messages, Extended Thinking with budget mapping, streaming tool_use reassembly), plus weighted fallback providers and a circuit breaker on top.
When a task falls outside the built-in crew, the Director asks the Meta-Agent, which designs → executes → registers:
- 🎨 One LLM call produces a new agent's system prompt, toolset, and goal as JSON
- ⚡ It runs immediately (15 steps) to finish the current sub-task
- 🔧 It stays registered as
delegate_<name>for the rest of the task, listed in the Director's prompt
Auto-creates
delegate_security_auditorfor a full-repo audit, ordelegate_performance_profilerfor bottleneck hunting.
Its tool palette is capped by the registry the same way every other agent's is — a generated agent cannot invent permissions.
Rebuilt on an external browser-control CLI driving an actual Chrome instance — 14 tools (open / inspect / snapshot / click / fill / type / select / tabs / wait / screenshot / eval …) so the agent can read rendered DOM, not just fetched HTML.
mode = "attach": connect to your existing browser over CDP and use a session you are already logged into- Isolated per-delegation workspace — screenshots, traces and upstream state land in
~/.yagent/data/browser/<delegation>/, never in your repository - URL policy (
allowed_domains/denied_domains), dialog policy, and an output cap so a giant page can't flood context - Authorization for sensitive JS — cookie/storage/network access and form submission require approval; screenshots are path-converged into the session workspace
- Honest capability degradation: no binary or no Chrome →
delegate_browser's own description becomes "unavailable + why + how to fix it", so the model stops trying
design— a pre-coding gate. For complex tasks the Coding-Agent's prompt requires a design pass before implementation: goal & scope, affected files, ordered steps, risks, verification criteria. Mid-implementation scope change means re-run it.deepthinking(reactive, for when conventional attempts failed) ·micro_agent(isolated sub-LLM reasoning, own provider slot) ·thinking(cheap self-reflection) — each with its own tool-level provider.- Structured Thought & Plan blocks —
goal / step / reason / planwith machine validation, parsed into a rolling journal that drives Tier-3 compression, feeds the TUI timeline, and survives context resets. - Parallel read-only execution — consecutive read-only calls (file reads, searches, call-graph queries, note reads, read-only delegations) are batched and run concurrently (default 4, ceiling 8). Concurrency is derived from tool effects, not a name list, and a contract test guards every widening of that surface.
- Git checkpoints — snapshot and roll back per coding sub-task.
- Forced delegation — the Director cannot write files, and repository exploration goes through the Repo-Agent. Replying without delegating triggers a reminder, up to three times.
| Concern | How Yagent Handles It |
|---|---|
| Blast radius | WorkspaceGuard: writing tools and run_bash must land inside the workspace; anything reaching outside needs authorization (persisted per session/project). run_bash carries no command blacklist — it combines the model's own is_dangerous flag with a check that any absolute path token pointing outside the workspace asks first. |
| Human in the loop | ask_user_for_help with confirm / select / input — blocking authorization travels on a critical bypass queue that is never dropped, matched by request_id. |
| Escalation for autonomy | -y / --yolo approves in-workspace operations; -Y / --full-yolo also removes ask_user_for_help entirely for unattended runs. |
| LLM flakiness | Exponential retry (≤30s) per step → weighted provider fallback → circuit breaker with reset timeout. |
| Stalled work | Activity-aware timeouts instead of a fixed deadline: heartbeats from each running tool distinguish an idle agent from a slow one (delegate_idle_timeout / delegate_total_timeout), and cancellation propagates into sub-agents. |
| Lost session | Synchronous rollout JSONL is the source of truth: /resume rebuilds conversation memory (repairing tool-call pairing), thinklink entries, per-agent token totals, compression history, model & context window, and re-adopts the blackboard. Interrupted runs raise a dialog listing unfinished plan items and dangling tool calls, and offer to continue. |
| Size bombs | 10MB edit/read caps, 1000 lines per read, soft warning at 2MB, tool-result budgets, artifact offloading for oversized deliverables. |
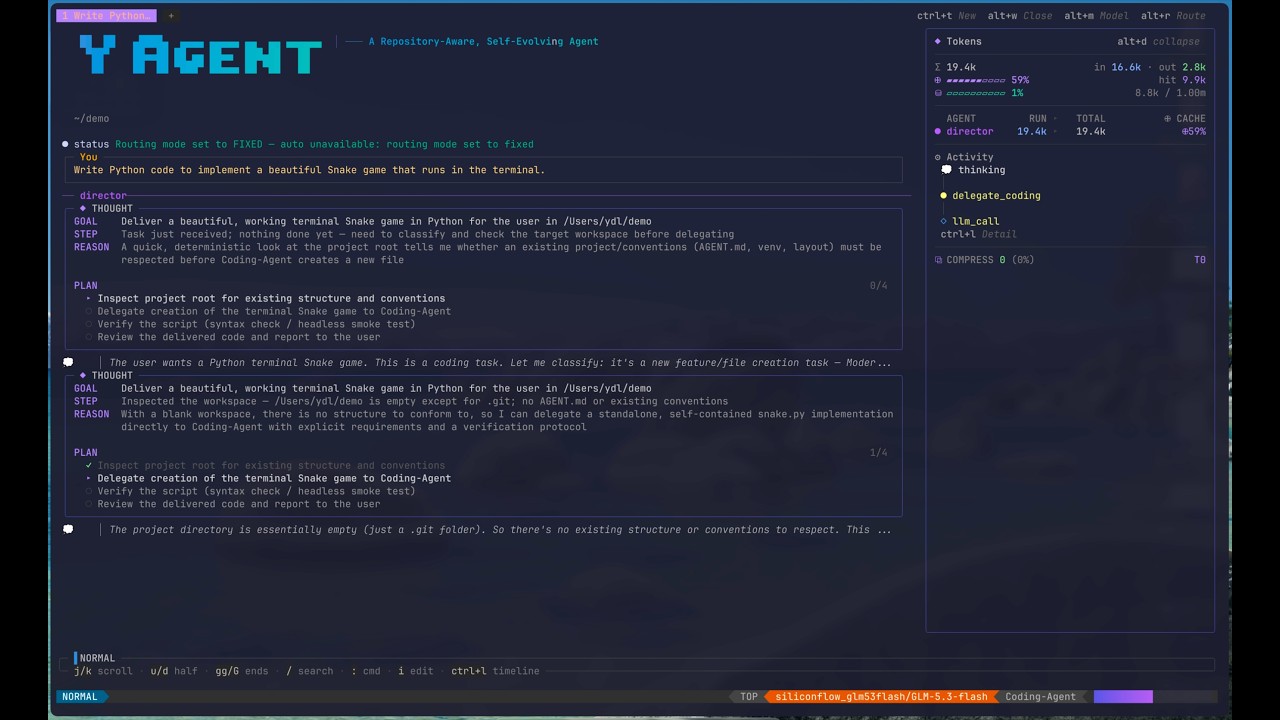
Built on Bubble Tea v2, with a single hand-drawn panel language (rounded borders, embedded mode labels, keycap hints) and a responsive layout engine down to narrow terminals.
- Up to 10 parallel session tabs (
ctrl+t,alt+1..9,alt+w), each snapshotting its own conversation, task, timeline, token counters and compression stats, keyed by its own session ID - Real vim modal editing —
Esc→NORMAL,i→INSERT, count prefixes (10j),/in-buffer search withn/N, and a:command line (:q :h :mode :language :route :model :timeout :clear :hist :resume) /skill-nameautocompletion from aSKILL.mdregistry, and@to pick a file through the embedded fzf- Token dashboard, one renderer: Σ totals, per-agent breakdown,
⊕prompt-cache hit rate (normalized across OpenAI and Anthropic accounting),⛁context-vs-window meter with green/yellow/red gradient, plus the⧉compression block showing per-tier savings (alt+tcollapses it to one line) alt+mmodel selector — rebind the global default, any of the 7 agents,deepthinking/design, or the LLM timeout at runtime;spacealso persists the choicectrl+gthinklink fullscreen with a per-agent filter (f),ctrl+ltimeline fullscreen, and a resume/history browser grouped by project and datectrl+zsuspends to your shell, and:languagetoggles the whole interface between Chinese ⇄ English
Grab the latest all-in-one release for your platform from GitHub Releases. The binary embeds the codeseek intelligence engine (Rust), fzf and ripgrep — extract, and run ./yagent. Zero dependencies.
- Go 1.25+
ripgreponPATH(used bysearch_by_regex; the release binary bundles it)- Rust + Cargo only if you want to rebuild codeseek from the submodule
git clone --recurse-submodules https://github.com/iohub/yagent.git
cd yagent
./build.sh              # Rust (codeseek) + Go → dist/bin/codeseek and ./yagent
go build -o yagent . # Go only, reusing the prebuilt dist/binYou don't have to hand-edit TOML: ./yagent setup opens a wizard that adds providers, tests the
endpoint with a real request, and asks the five first-run questions (answer language, approval mode,
routing, browser, per-call timeout). It writes config.toml comment-preservingly and nothing lands on
disk until you confirm the review screen. The same wizard runs inside the TUI as /setup, and opens
by itself on a fresh machine (template just generated, api_key still a placeholder, or a config that
won't load).
~/.yagent/config/config.toml is generated from an embedded template on first run (mode 0600, since
it can hold a literal key), or point at your own with -c — that path is used verbatim and never created.
[global.llm]
use_provider = "siliconflow"

[global.llm.providers.siliconflow]
model           = "deepseek-ai/DeepSeek-V3.2"
api_base_url    = "https://api.siliconflow.cn/v1"
api_key         = "your-api-key"
# api_key_env   = "SILICONFLOW_API_KEY"   # or take the key from the environment
temperature     = 0.0
max_tokens      = 23000
# context_window = 262144        # TUI context meter only (compression uses the model catalog)
# api_format     = "anthropic"   # native Messages + Extended Thinking
# reasoning_effort = "high"      # openai: passthrough · anthropic: thinking budget
# fallback_providers = ["mimo", { provider = "local", weight = 2 }]

[agents.llm.coding]              # per-agent and per-tool provider overrides
use_provider = "local"           # agents: director / coding / repo / chat / devops / browser / meta
[tools.llm.micro_agent]
use_provider = "local"

[routing]
mode = "auto"                    # benchmark-scored fast/balanced/high
[routing.baselines]
coding  = "high"
repo    = "balanced"

[codeseek]                       # Rust code intelligence over MCP
binary_path = ""                 # empty → extracted from the embedded binary

[browser]                       # Browser-Agent (needs browser-control + Chrome)
enabled = true
mode = "headless" # headless | headful | attach./yagent # TUI (default)
./yagent setup # configure providers + first-run choices, then exit
./yagent tui --taskfile TASK.md
./yagent -p "explain the build system" # non-interactive single shot
./yagent http --port 0 # HTTP + WebSocket, port auto-detected from 9800Flags: -d/--disable-agents · -c/--config · -y/--yolo · -Y/--full-yolo · -Q/--force-quit.
The working directory is the project root. Drop reusable prompts as *.md in .yagent/skills/ (or ~/.yagent/skills/) and they show up as /slash commands.
bash scripts/check_all.sh            # the one-command local gate: build + vet + 5 guards + full suite
RACE=true bash scripts/check_all.sh  # plus -race on the concurrent packages
go test ./internal/... -count=1 # ~970 tests across 129 files, seconds not minutes- End-to-end chains run against real components. Authorization round-trip, cross-delegation handoff (notes + artifacts + deferred-schema retry), delegation lifecycle (idle/total timeout & cancellation), and
/resumeall execute with the real dispatcher, realWorkspaceGuard, real note store and real rollout files — only the LLM is scripted, and it is scripted per agent identity, not by global call index. - Protocol layer pinned by shape.
httptestfakes assert the exact JSON going out and the exact usage accounting coming back (the two providers' cache-token conventions are opposite, and that is asserted). - Tests must be able to fail. A hygiene ratchet rejects assertion-less tests, unconditional skips, and duplicate helpers; a fixture that never triggers the branch under test is treated as a bug. Timing tests use seams, never
sleep— the suite stays fast enough to actually run. - Architecture ratchets:
director/may not importagents/(no cycles),toolspecstays a leaf, no hand-written tool lookup tables, and the file-size gate reports when it drifts out of sync instead of crying wolf. - Events have one source of truth:
protocol/agent-events.yamlgenerates the Go / TS / JSON-Schema.
| Document | Description |
|---|---|
| ARCHITECTURE.md · ARCHITECTURE.en.md | System architecture, modules, data flow |
| AGENTS.md | The knowledge base agents themselves read before contributing — module map, invariants, known pitfalls |
| tool-registry-design.md | Capability registry, profiles, and deferred tool schemas |
| blackboard-handoff-design.md | Cross-agent notes, structured handoff, derived index |
| browser-agent-design.md | Browser-Agent on the browser-control CLI |
| token-dashboard-design.md · token-compress-panel-design.md | Token accounting and compression telemetry |
| config-guide.md | Configuration guide |
| anthropic-config.md | Anthropic provider configuration |
| llm-fallback-config.md | Fallback and circuit-breaker configuration |
Known gap, stated plainly: the long-term knowledge retrieval injector (
internal/knowledge/injector.go) is temporarily gated off — the write path (consolidate_knowledge, repo-level memory consolidation) is live, but historical knowledge is not auto-injected into context yet.
We welcome all contributions — bug reports, feature requests, docs, and code.